
A fintech startup is building a document analysis pipeline that processes scanned bank statements and extracts structured data. Processing volume is 50,000 documents per day, and each document averages 8 pages. The team is evaluating whether to use Claude Haiku or Claude Sonnet for the vision extraction task. Accuracy testing shows Haiku achieves 94% field extraction accuracy and Sonnet achieves 97%. The downstream reconciliation system can tolerate up to 5% error rate before requiring human review. Which model selection strategy minimizes total cost while meeting accuracy requirements?
Select an answer to reveal the explanation.
Short Explanation
You want tiered routing: run Haiku initially and escalate only low-confidence fields to Sonnet. That captures Haiku's cost advantage on most documents while using Sonnet where its accuracy premium matters, keeping you within the 5% tolerance.
Full Explanation
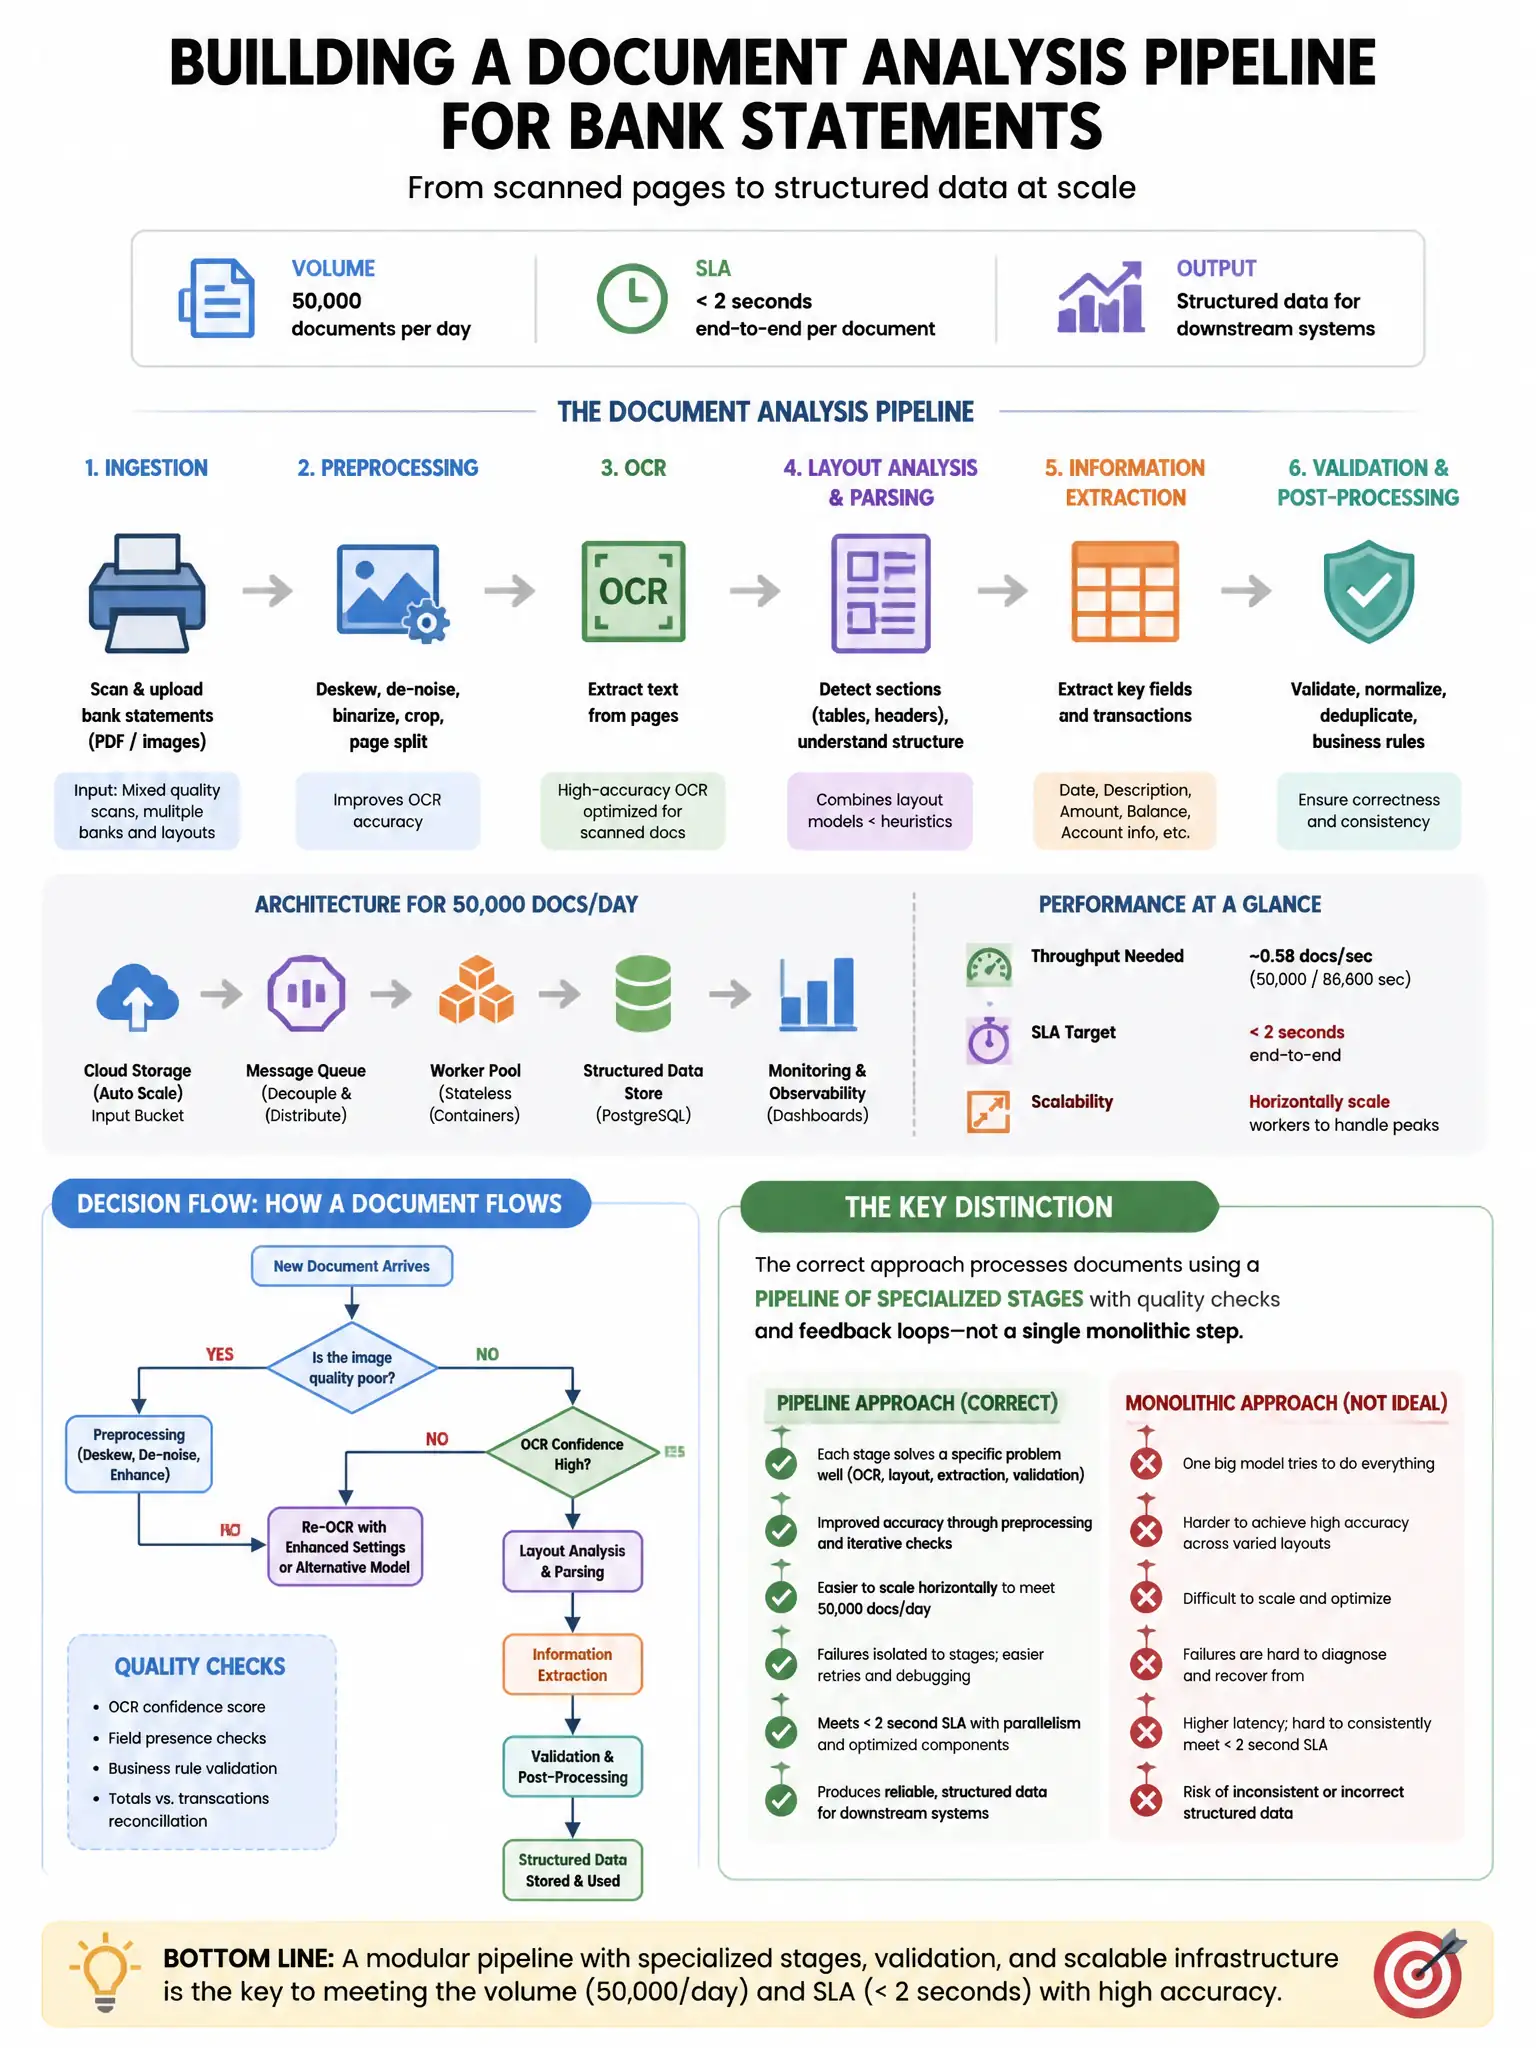
The tiered routing strategy—using Haiku for initial extraction and automatically escalating to Sonnet only for documents where Haiku returns low-confidence fields, based on confidence thresholds—is architecturally optimal here. It captures Haiku's cost advantage on the majority of documents while using Sonnet only where its accuracy premium is needed, staying within the 5% tolerance. The all-Haiku choice may look tempting because 94% field-extraction accuracy appears close to the 5% error tolerance, but it ignores that errors are not uniformly distributed; complex documents will cluster failures and push certain document classes above tolerance. The all-Sonnet choice pays roughly 5-fold the cost premium for marginal improvement on documents Haiku handles correctly. The all-Opus choice is cost-prohibitive at this volume and solves no problem given the reconciliation system already handles errors.