
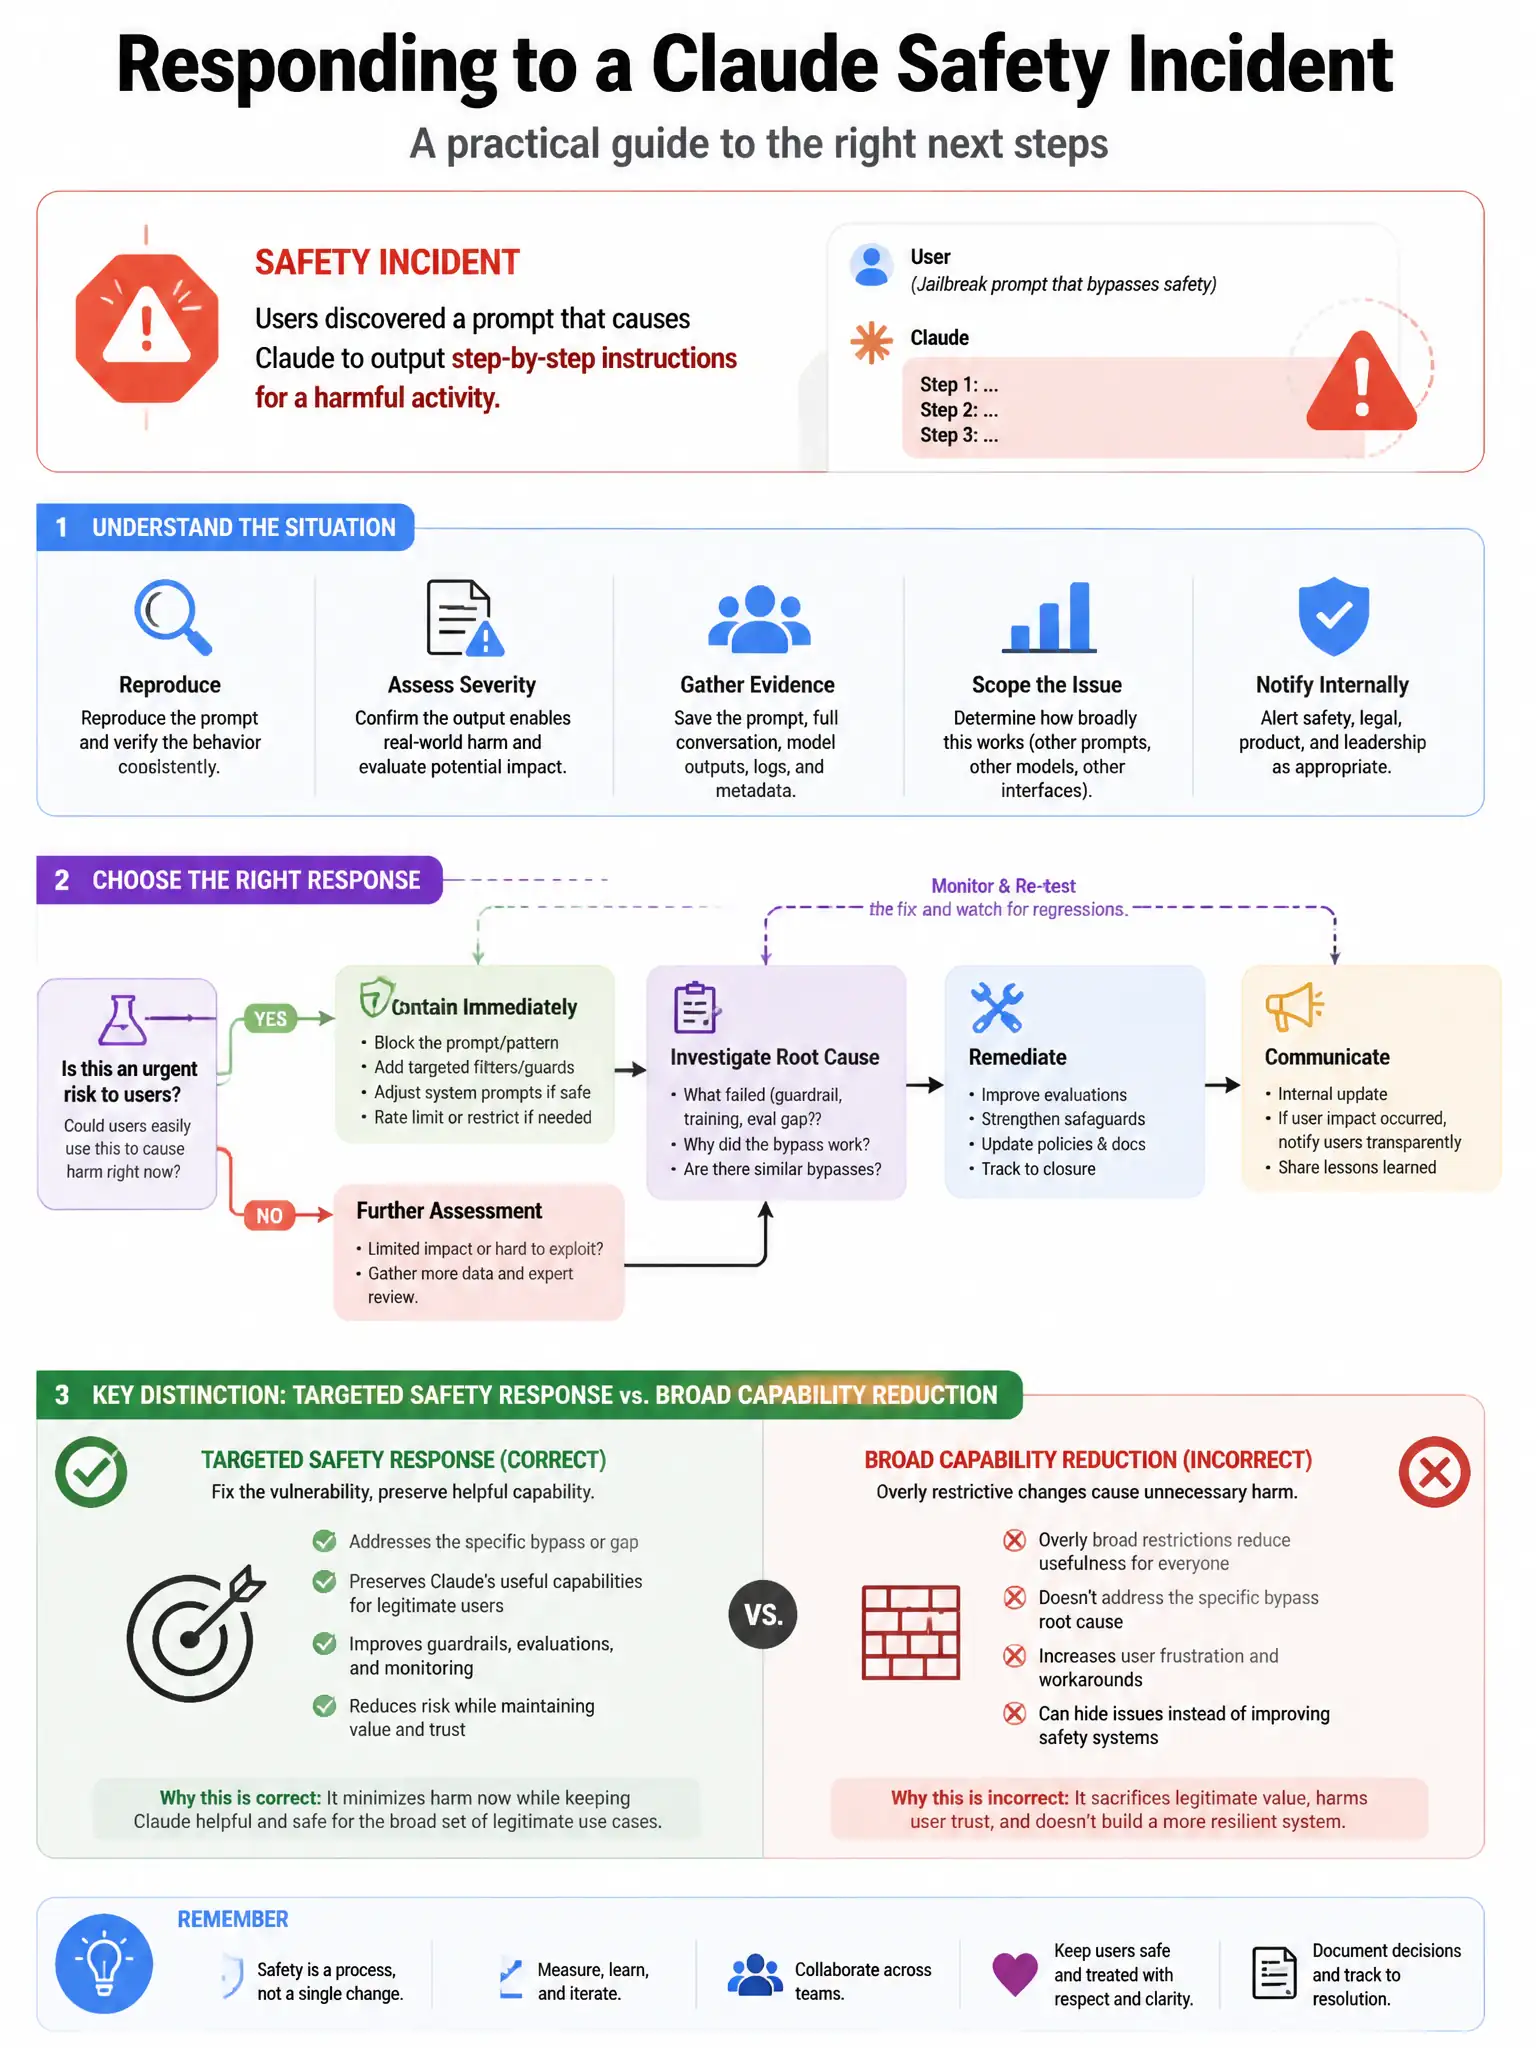
A Claude deployment has just experienced a safety incident: users discovered a prompt that causes Claude to output step-by-step instructions for a harmful activity. The team needs to respond. What is the correct immediate and long-term response architecture?
Select an answer to reveal the explanation.
Short Explanation
When a safety incident happens, you mitigate now and fix the class, not just the one prompt. Block or monitor the discovered pattern, rate-limit to shrink blast radius, notify Anthropic, then update prompts and monitoring for similar patterns.
Full Explanation
Incident response for a safety vulnerability requires immediate mitigation plus systematic remediation of the vulnerability class. Immediate actions: deploy output monitoring or filtering for the discovered pattern, apply rate limiting to reduce blast radius, and notify Anthropic, who can address model-level mitigations. Long-term: investigate similar patterns beyond the exact prompt discovered, update the system prompt to strengthen the relevant boundary, and enhance monitoring coverage across the vulnerability class. The proposal to disable the deployment and wait for Anthropic to patch it misunderstands the shared responsibility model; operators must implement defenses, not only rely on model-level fixes. The proposal to implement only a keyword filter for the specific prompt pattern is brittle, because adversarial users will rephrase the prompt to bypass the filter; the vulnerability class must be addressed systematically. The proposal to assess severity and, if no actual harm occurred, treat it as a low-priority enhancement request for the next development sprint is inappropriate for active safety incidents; the vulnerability is currently exploitable and more users may discover it.