
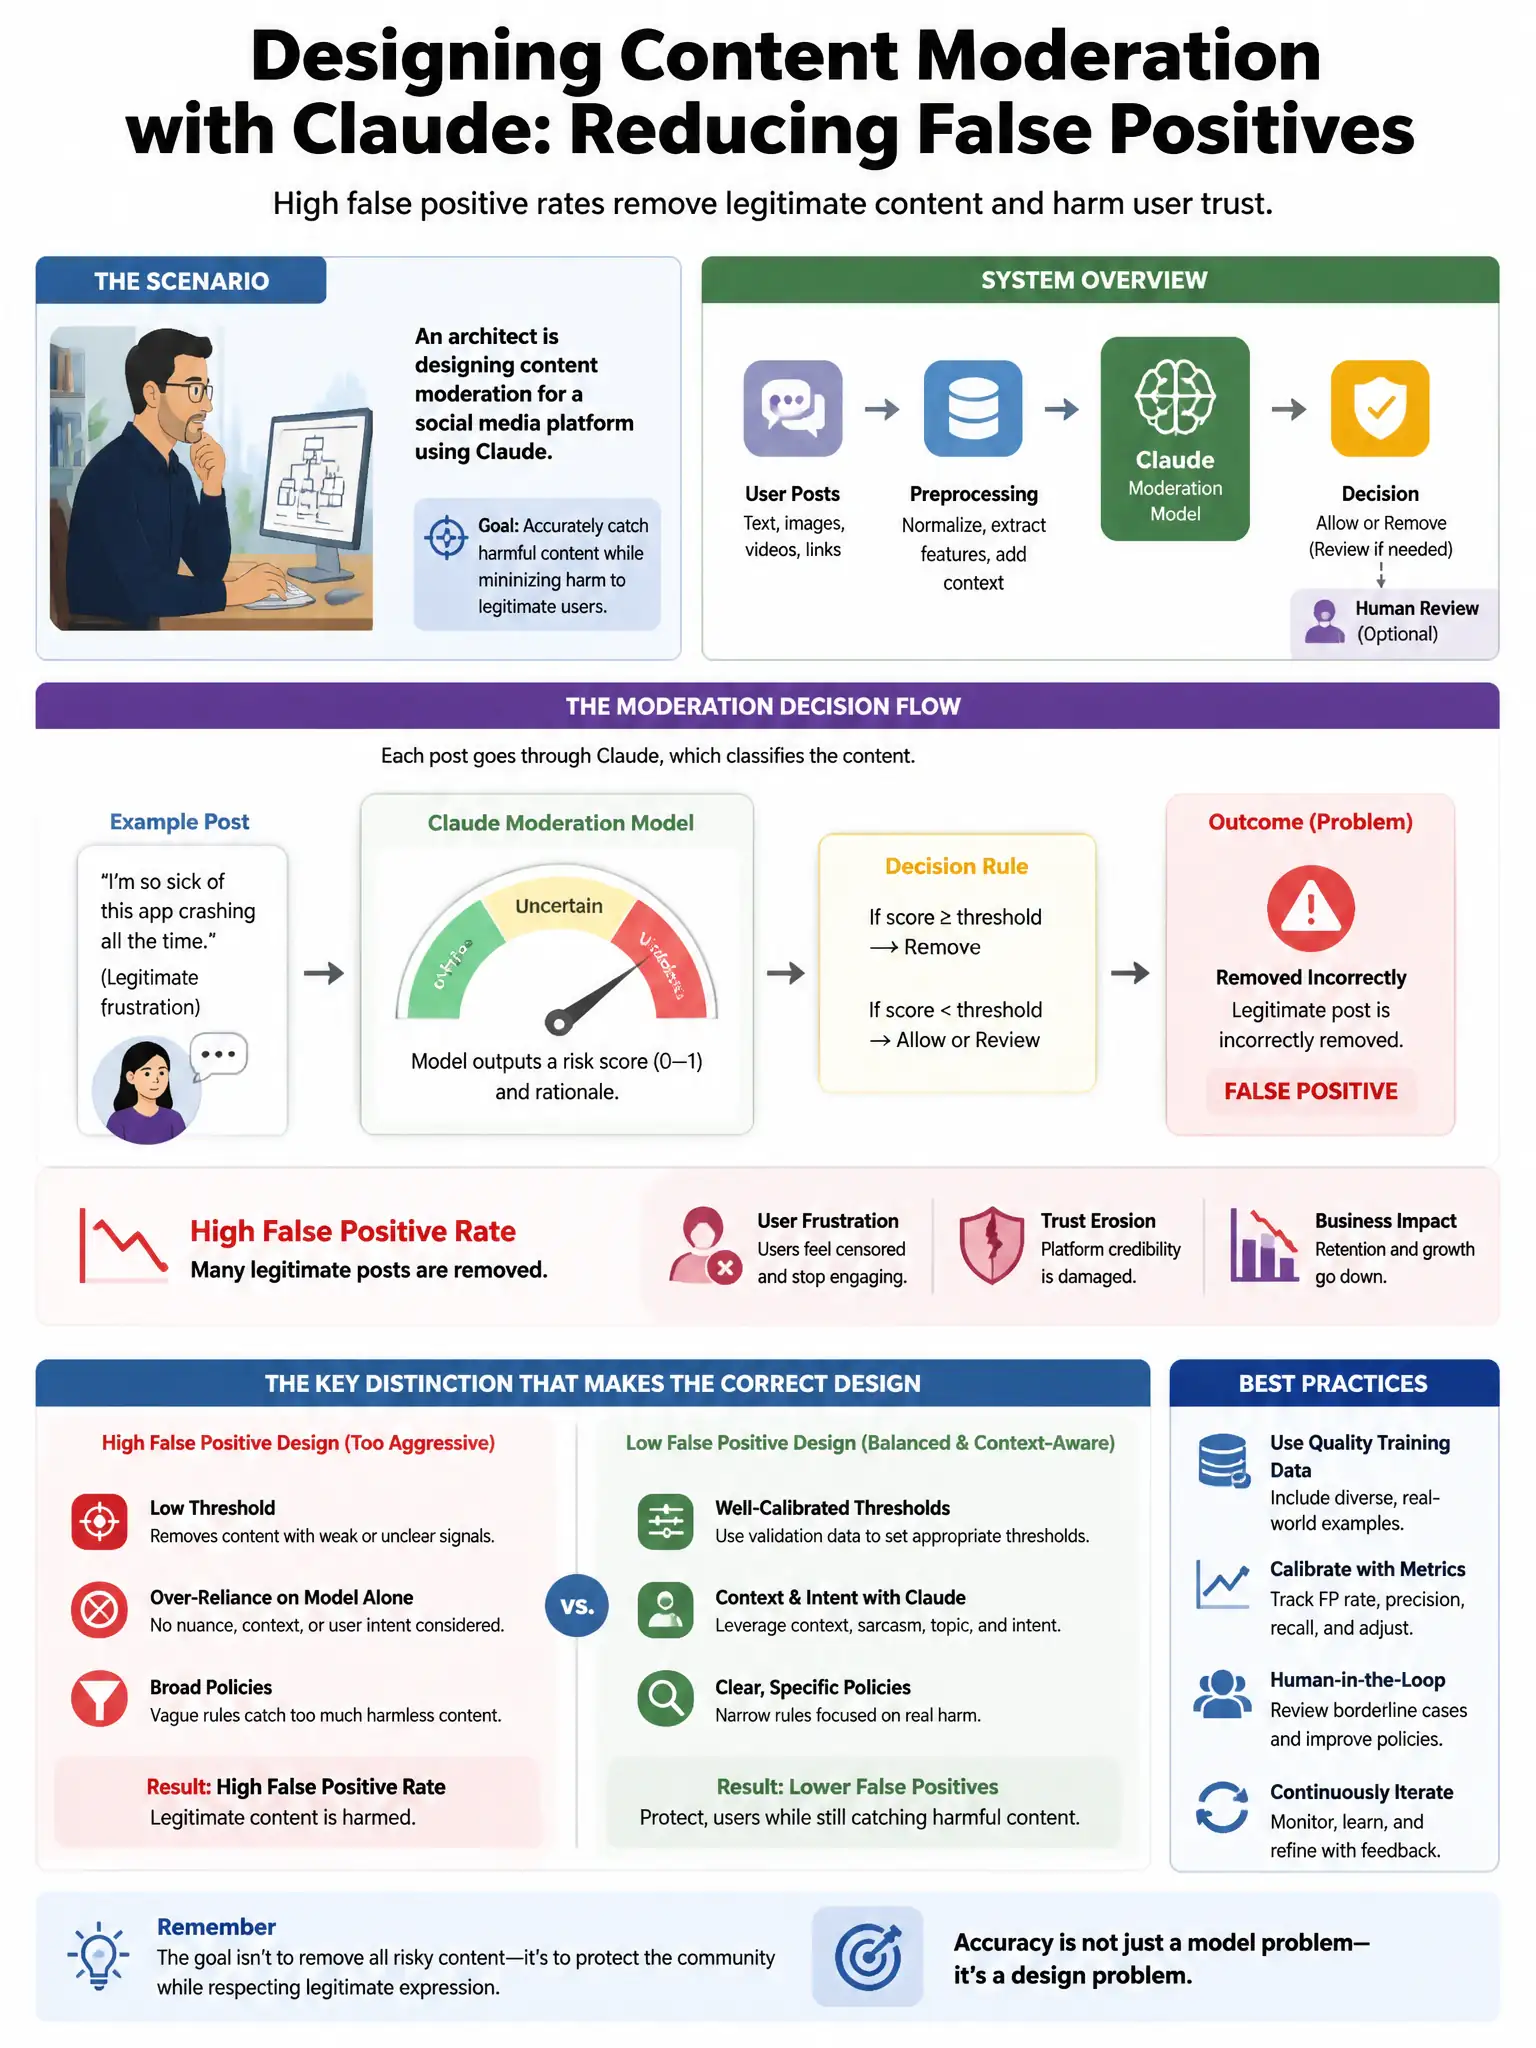
An architect is designing content moderation for a social media platform using Claude. The system has a high false positive rate, causing legitimate posts to be incorrectly removed. The team proposes lowering the confidence threshold for flagging. What is the correct tradeoff analysis?
Select an answer to reveal the explanation.
Short Explanation
You're dealing with a precision-recall tradeoff. Lowering the flagging threshold catches more harmful posts but also flags more legitimate ones, while raising it does the opposite. The right threshold depends on whether false positives or false negatives cost the platform more, so the policy team has to decide.
Full Explanation
Content moderation involves a fundamental precision-recall tradeoff. Lowering the flagging threshold increases recall (fewer harmful posts escape) but increases false positives (more legitimate posts flagged). Raising it reduces false positives but allows more harmful content through. The correct analysis is that there is no universally correct threshold — the optimal setting depends on the platform's policy framework: what harm category is being moderated, the consequences of false positives (user trust, legal exposure, appeals cost) vs false negatives (harm enabled, platform reputation). This is a policy decision requiring human governance input, not a purely technical optimization. The claim that Claude's Constitutional AI training ensures high precision at any threshold and that false positives indicate a need to upgrade the model version is incorrect because thresholding changes the operating point of any classifier and does not eliminate false positives. The claim that a lower threshold always improves the moderation system because catching more harmful content is always preferable is wrong — 'always flag more' ignores the real costs of false positives (user trust damage, legal liability, moderation workload). The claim that the false positive rate should be minimized above all other considerations because legal liability of incorrectly removing content exceeds that of allowing harmful content presents one stakeholder's perspective as the absolute priority, ignoring the platform's equal responsibility to prevent genuine harm.