
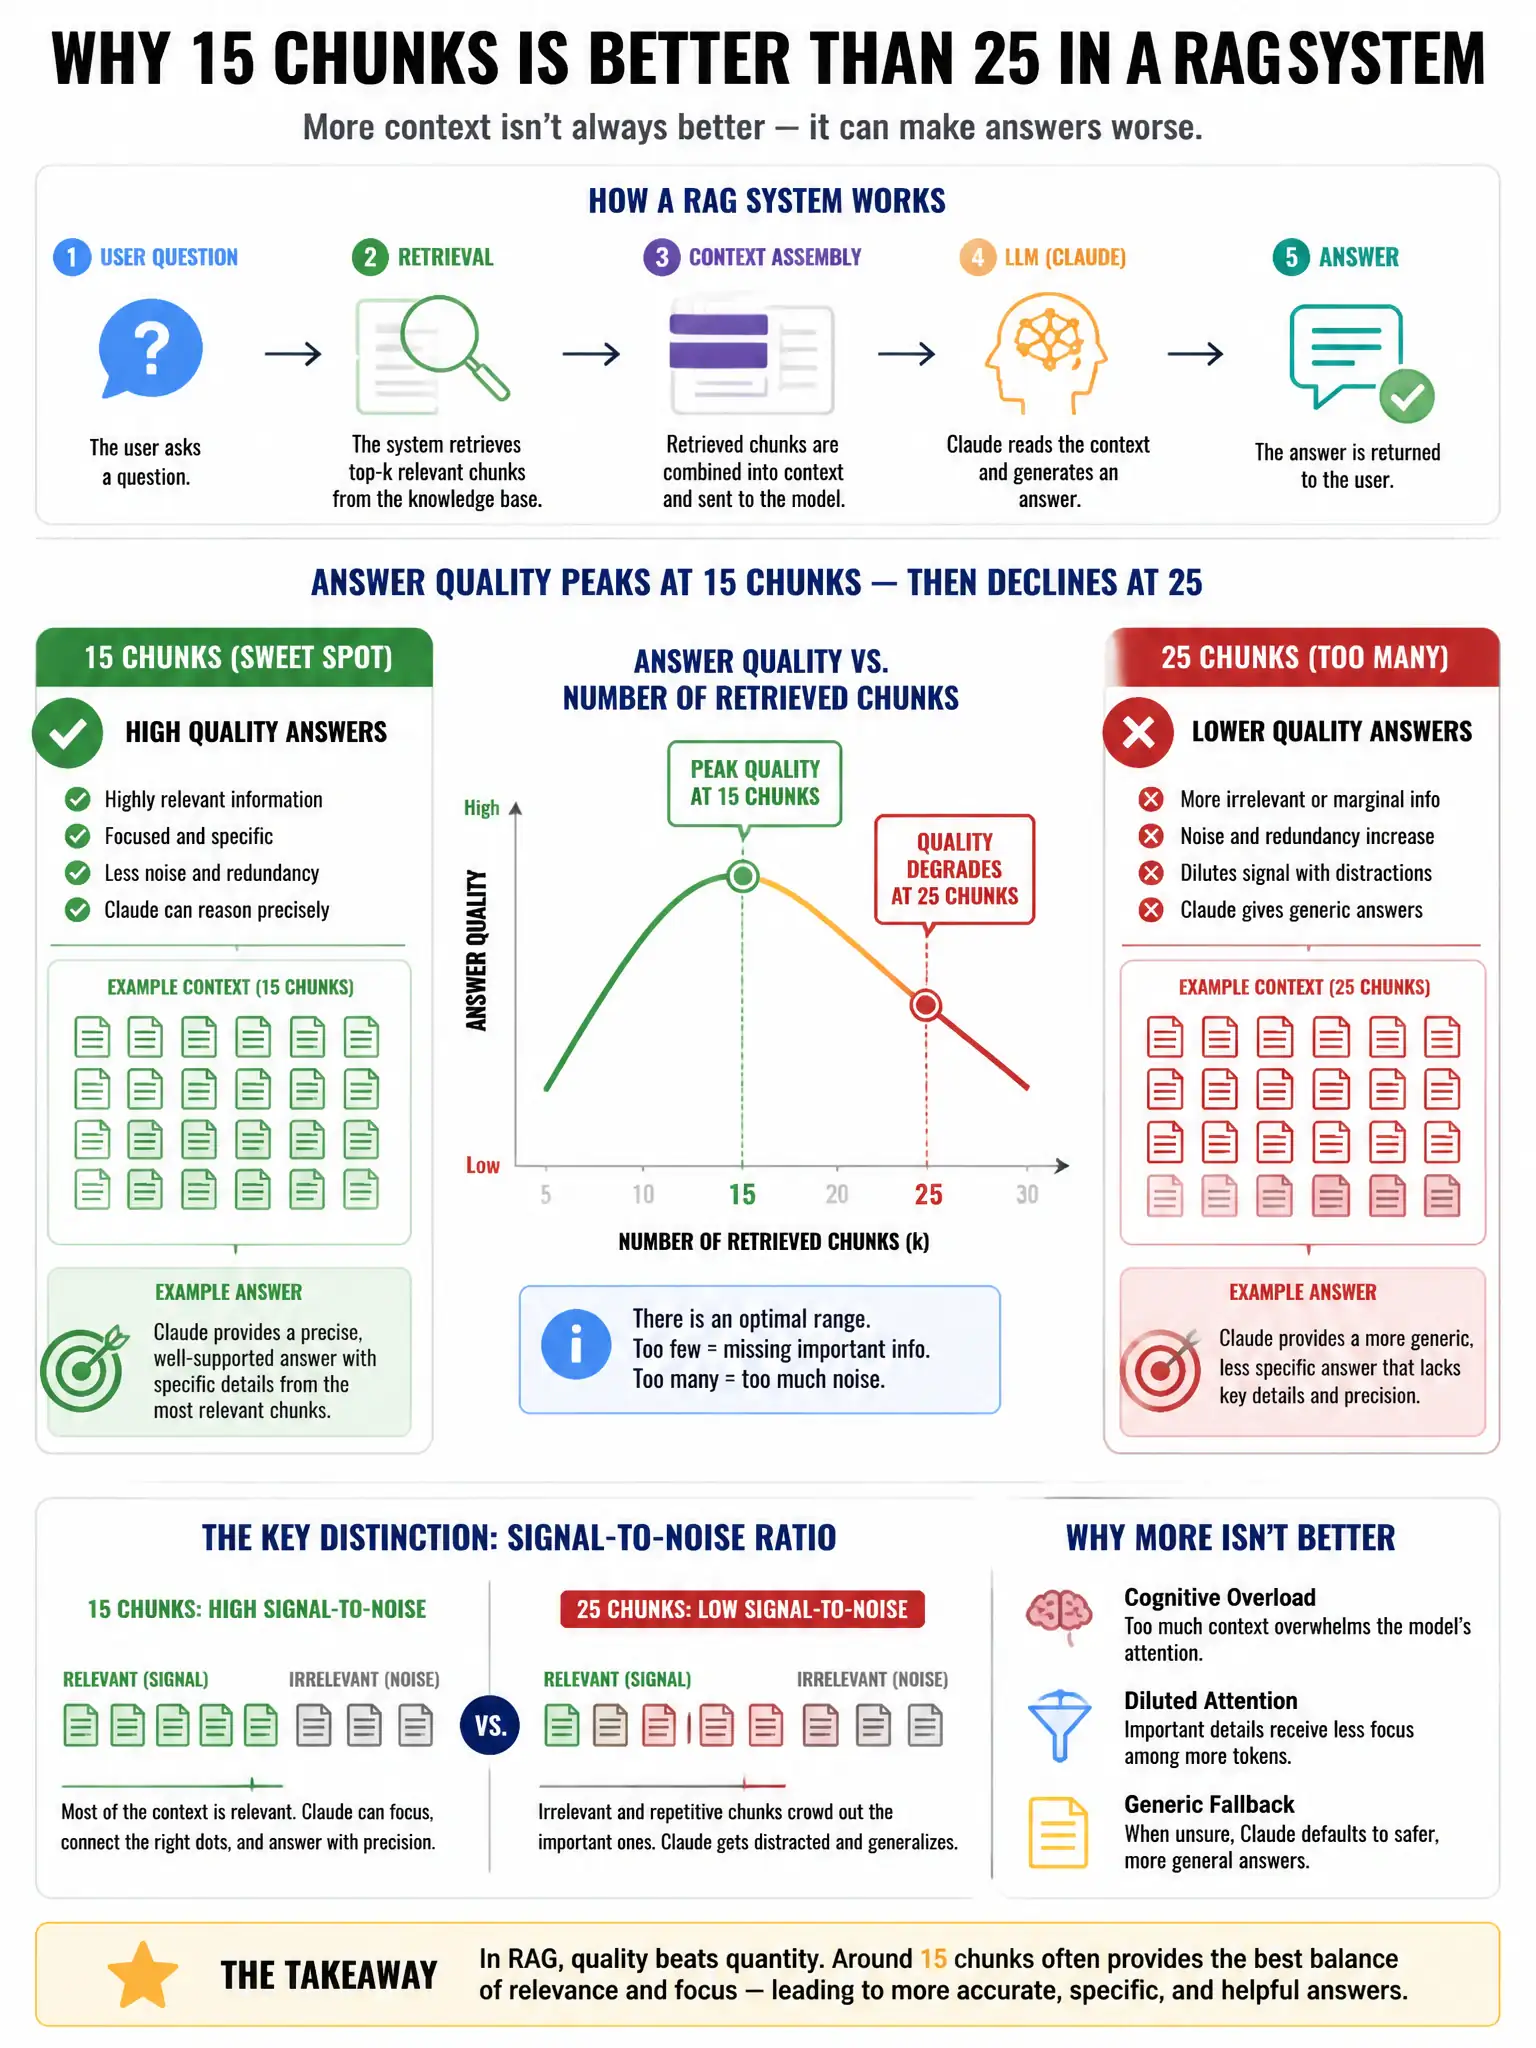
A RAG system shows that with 15 retrieved chunks Claude's answer quality peaks, but with 25 chunks quality degrades — Claude gives less specific, more generic answers. What phenomenon explains this, and what is the architectural mitigation?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you're seeing the lost-in-the-middle effect: the model pays more attention to the start and end of a long context and less to the middle, so relevant chunks get buried. Cap retrieval at the quality-optimal count, rerank, and put the best chunks at the beginning and end.
Full Explanation
The lost-in-the-middle phenomenon is well-documented in large language model research: models attend more to content at the beginning and end of their context window and less to content in the middle. With 25 chunks, the most relevant chunks may appear mid-context, reducing their influence compared with 15 chunks where relevant content is more prominently positioned. The mitigation is to use a reranker to rank chunks by query relevance, strategically order the context with highest-relevance chunks at the beginning and end of the context block, and cap retrieval at the quality-optimal count. The context-window-overflow explanation is incorrect because 25 chunks of typical 300-500 token size totals 7,500-12,500 tokens, well within Claude's 200,000-token window. The embedding-interference explanation is incorrect because adding more chunks to the retrieval context doesn't affect embedding computation quality, since embeddings are computed separately at indexing time. The token-budget-exhaustion explanation confuses input and output tokens because chunk context affects input token count, not output token budget.