
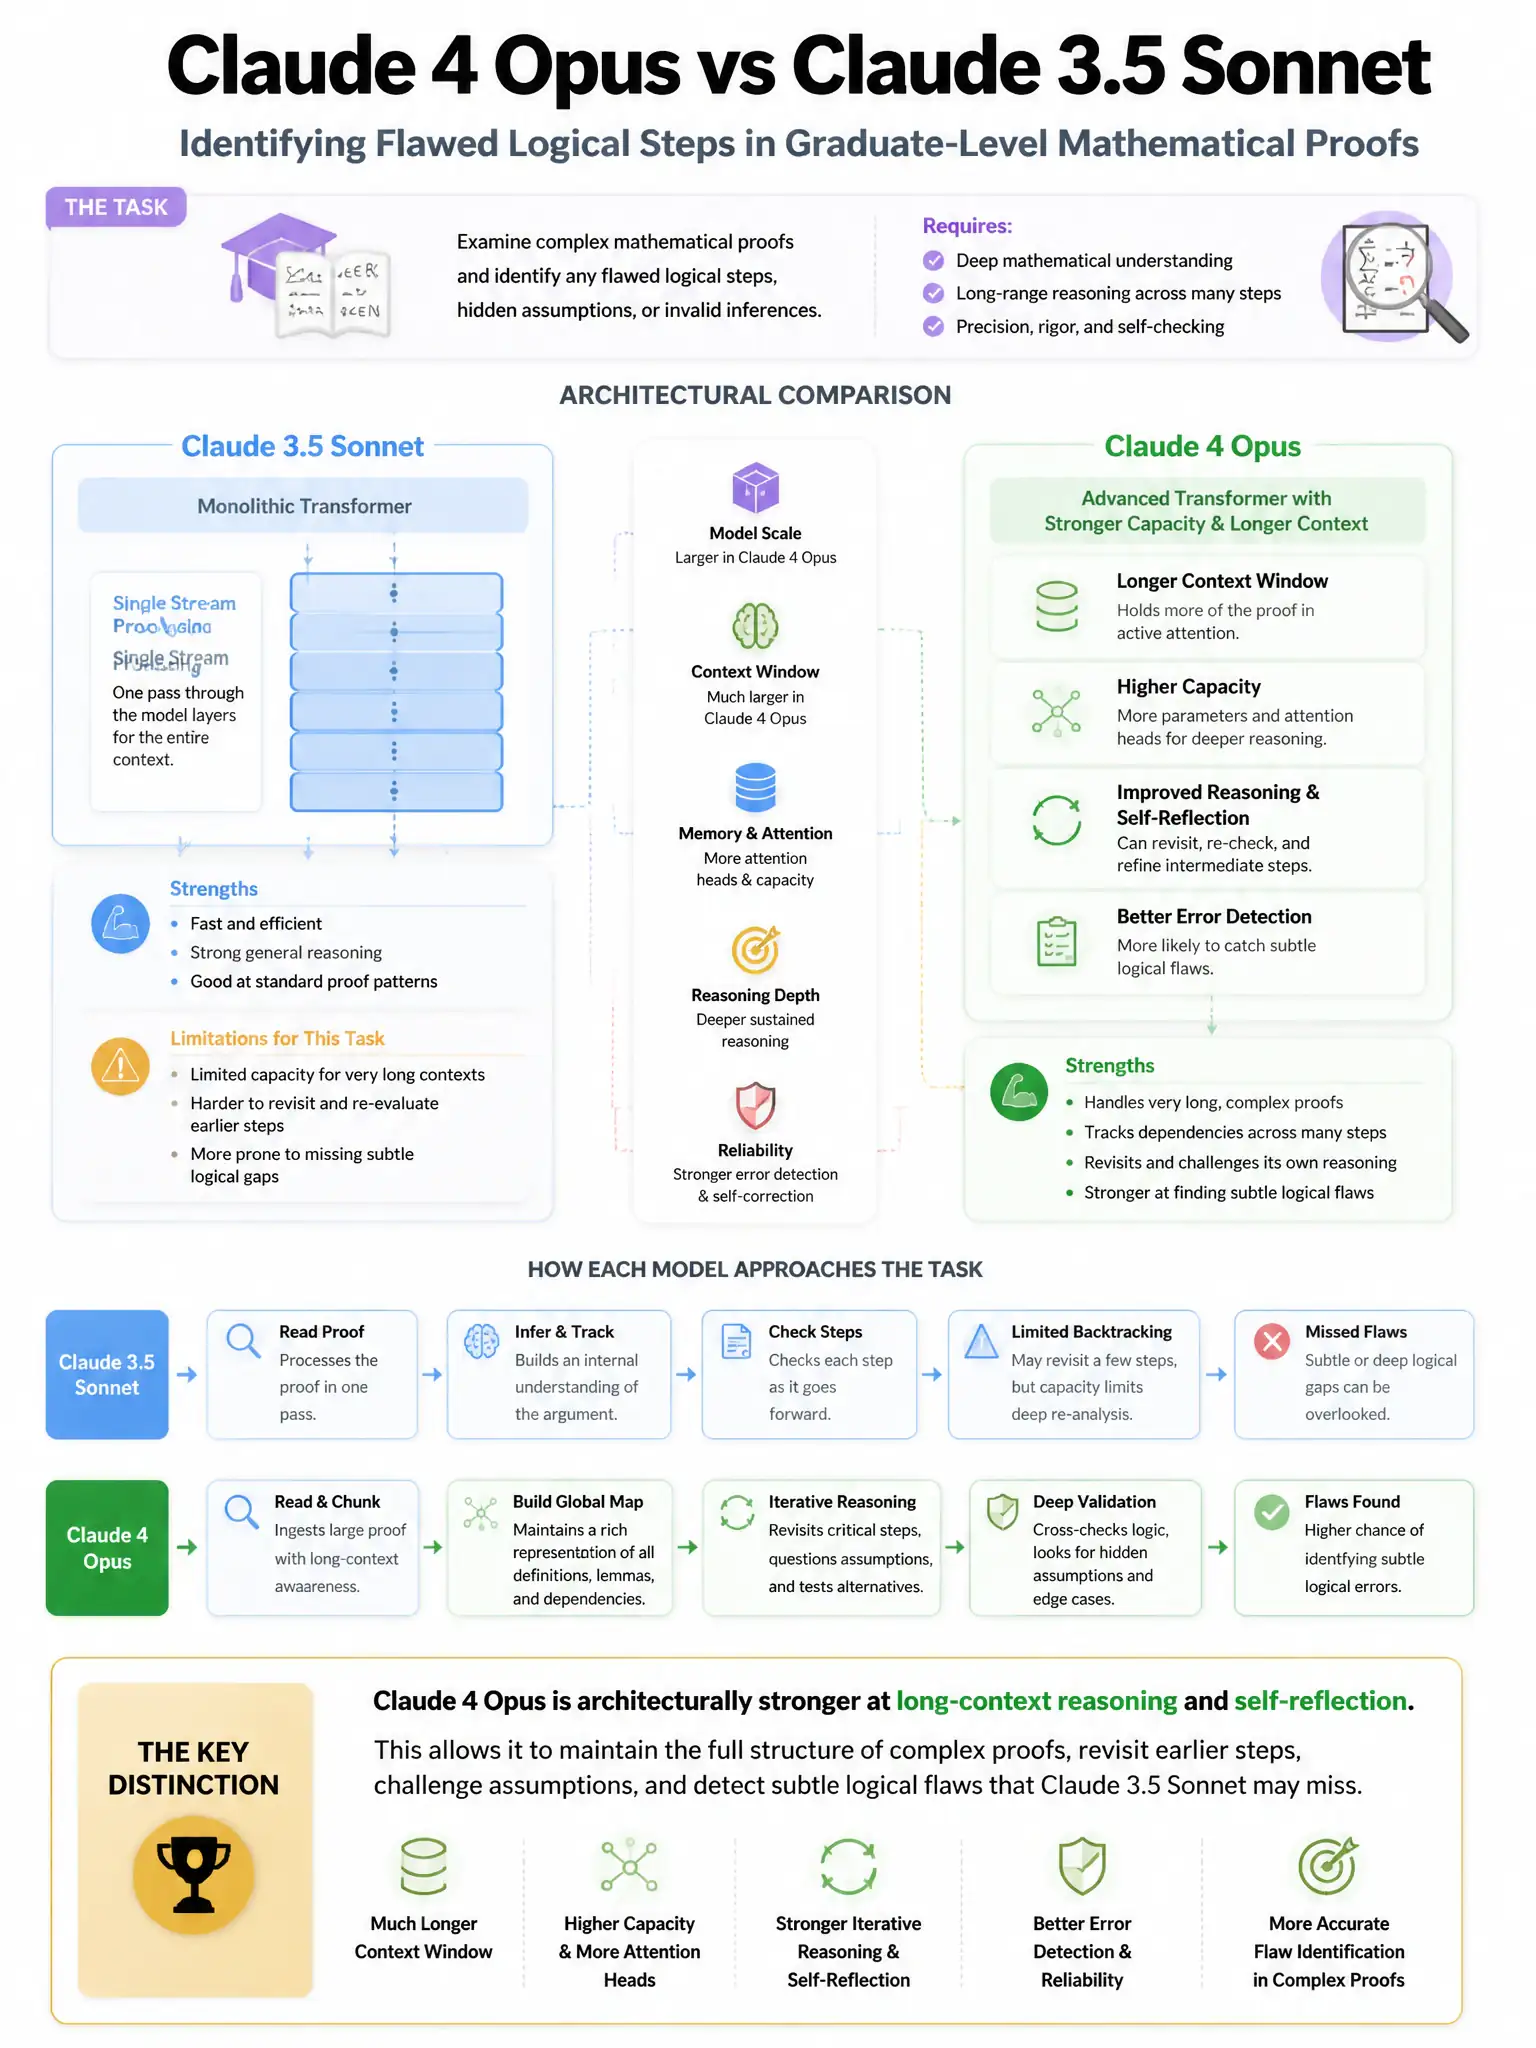
A team is comparing Claude 4 Opus with Claude 3.5 Sonnet for a task requiring identification of flawed logical steps in graduate-level mathematical proofs. Which architectural consideration should drive model selection?
Select an answer to reveal the explanation.
Short Explanation
For graduate-level proof checking, you need deep sustained reasoning across many logical steps, so the highest capability tier is the right call. Claude 4 Opus is built for exactly that kind of task, and its extra reasoning depth shows up in measurable quality gains.
Full Explanation
For complex multi-step reasoning tasks like graduate-level mathematical proof verification, Claude 4 Opus represents the highest capability tier and is specifically designed for tasks where reasoning depth matters most. Identifying flawed logical steps in graduate proofs requires sustained logical coherence across many reasoning steps — precisely the scenario where the top-tier model's additional capability translates to measurable quality differences. The option favoring Claude 3.5 Sonnet for faster inference is flawed because more speed does not help if each reasoning pass is lower quality. The option saying model selection is irrelevant and prompt structure determines output quality is incorrect; while prompt structure matters significantly, for truly complex reasoning tasks model capability creates a performance ceiling that prompting alone cannot overcome. The option saying both models are equivalent and should be selected solely on cost-per-token is incorrect because Claude 4 Opus represents a generational improvement in reasoning over Claude 3.5 Sonnet; they are not equivalent for hard reasoning tasks.