
A company is making 1 million Claude API calls per month with a 500-token system prompt. What would have the BIGGEST impact on reducing their monthly API costs?
Select an answer to reveal the explanation.
Short Explanation
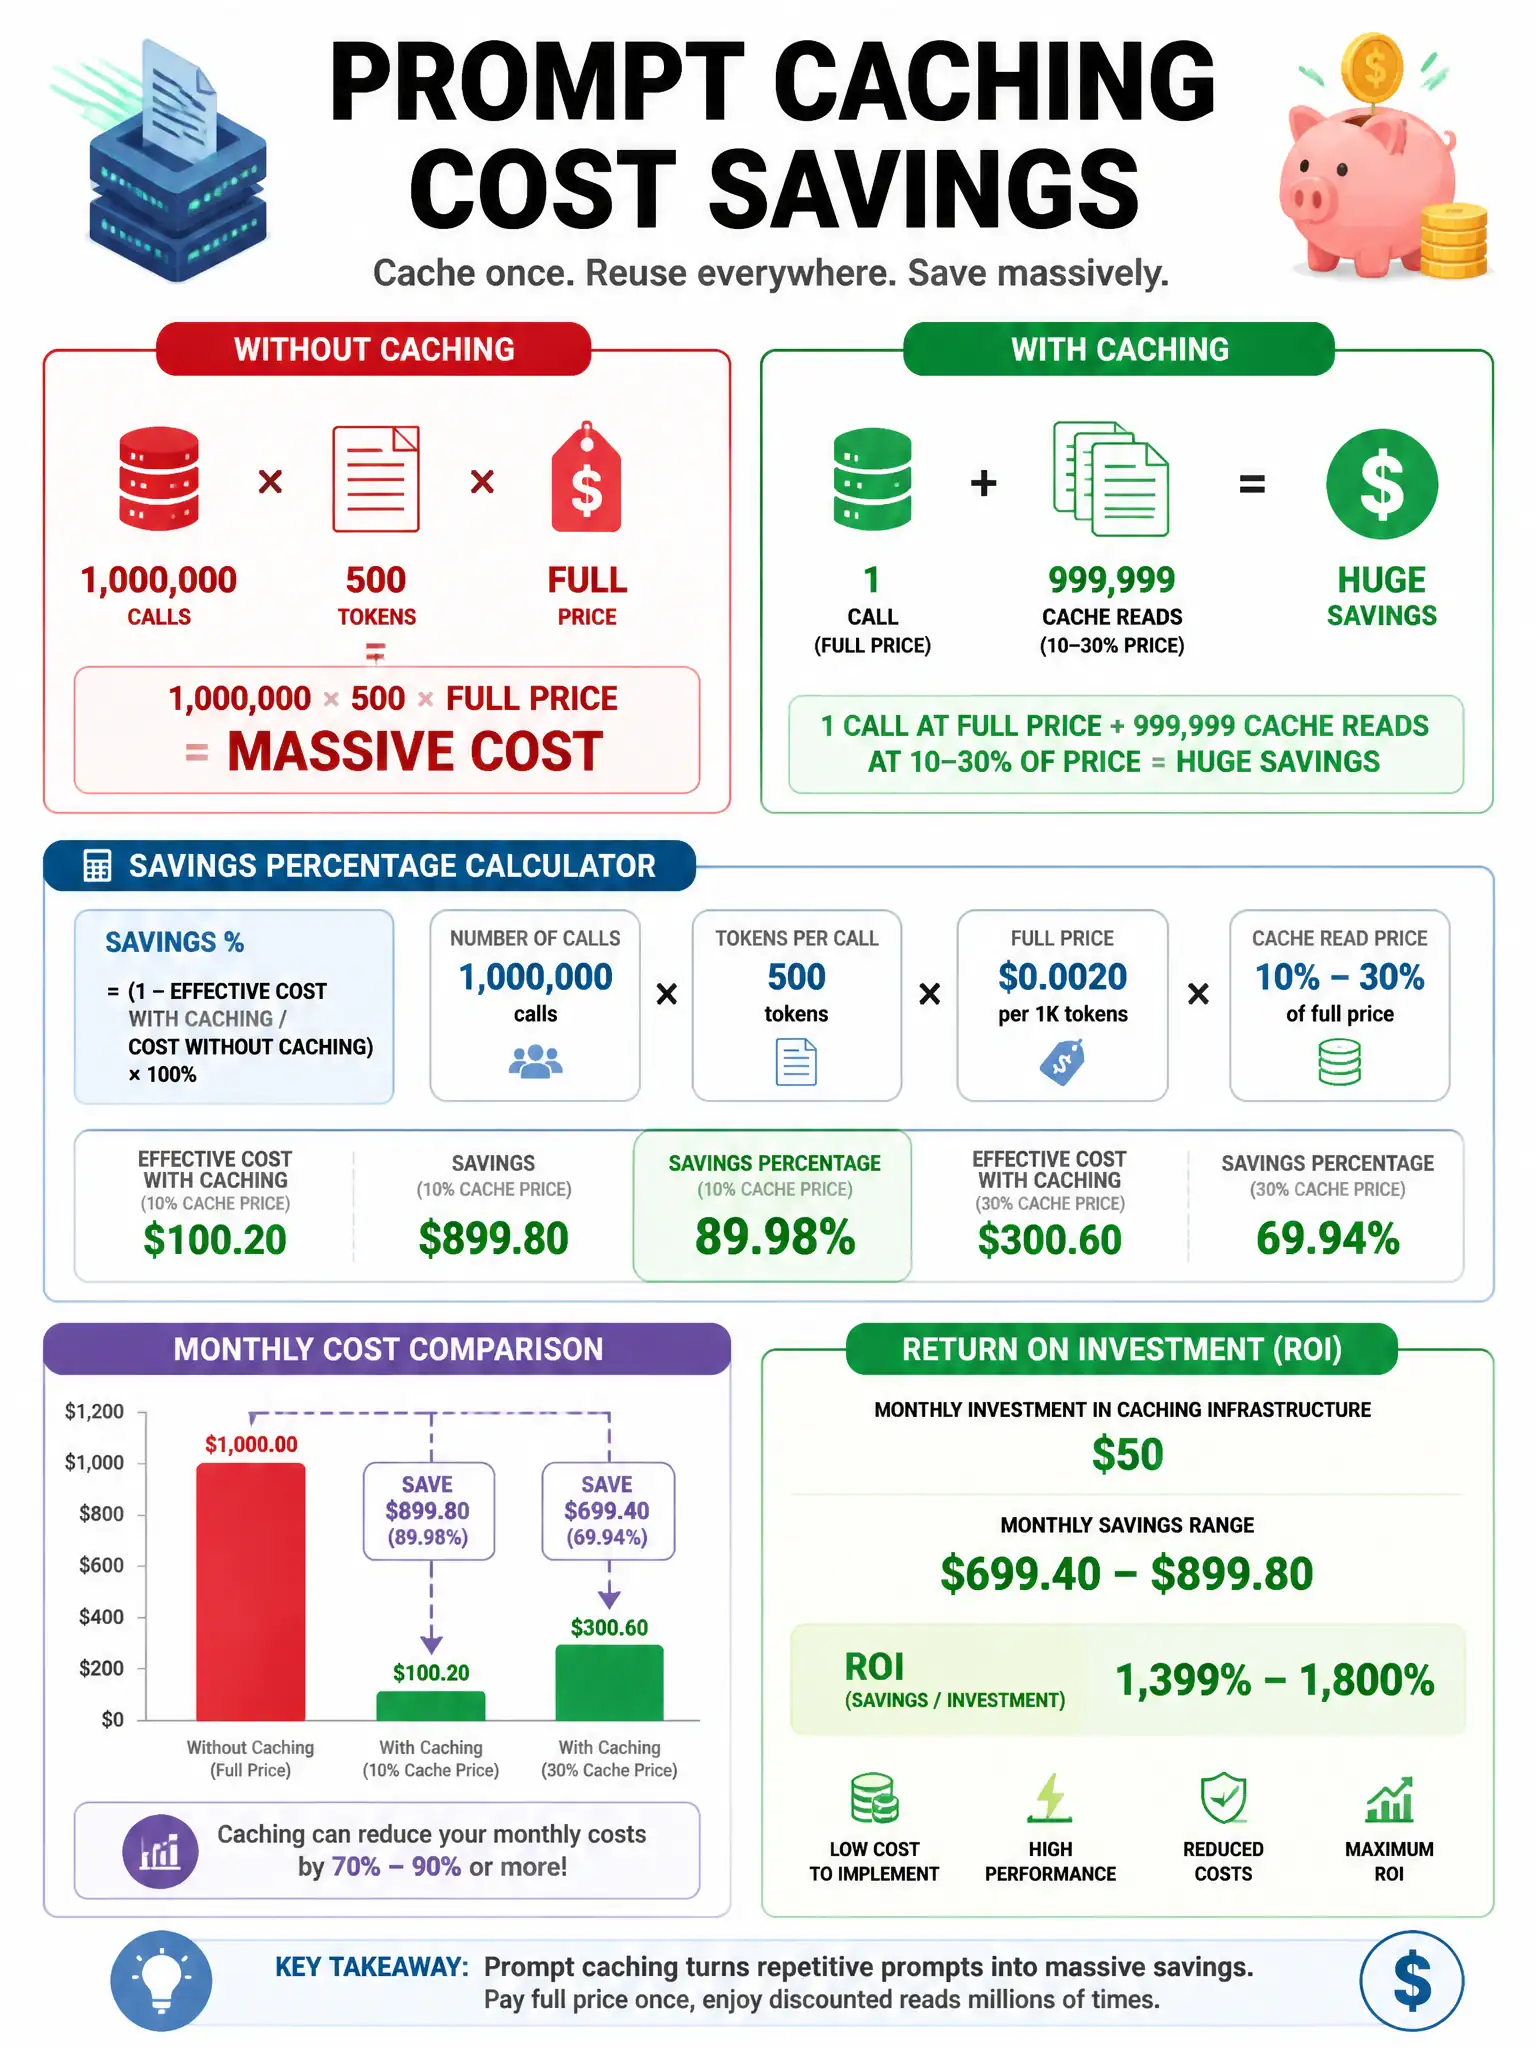
A 500-token system prompt across 1 million calls means you're paying for 500 million repeated input tokens every month. Caching that prompt turns almost all those repeat calls into cheap cache reads, so you slash the biggest repeated cost.
Full Explanation
Prompt caching's impact is most dramatic when the same content is repeated across many calls and that content is substantial. A 500-token system prompt repeated 1 million times equals 500 million input tokens at full price. With caching, the first call creates the cache entry at full price, and the subsequent roughly 999,999 calls read from cache at a reduced price, typically 10-30% of input token pricing, potentially saving 70-90% of system prompt token costs. Switching from HTTPS to HTTP does not affect pricing because it concerns transport security, not API cost. Removing the stop_sequences parameter has no pricing impact because stop sequences control generation behavior, not the billed token count. Reducing the max_tokens parameter by 50% only lowers the maximum allowed output length; it does not automatically reduce costs unless the model was actually generating output up to the previous limit, and even then it only affects output tokens rather than the 500 million repeated system prompt input tokens.