
What is the relationship between temperature and top_k in language model sampling?
Select an answer to reveal the explanation.
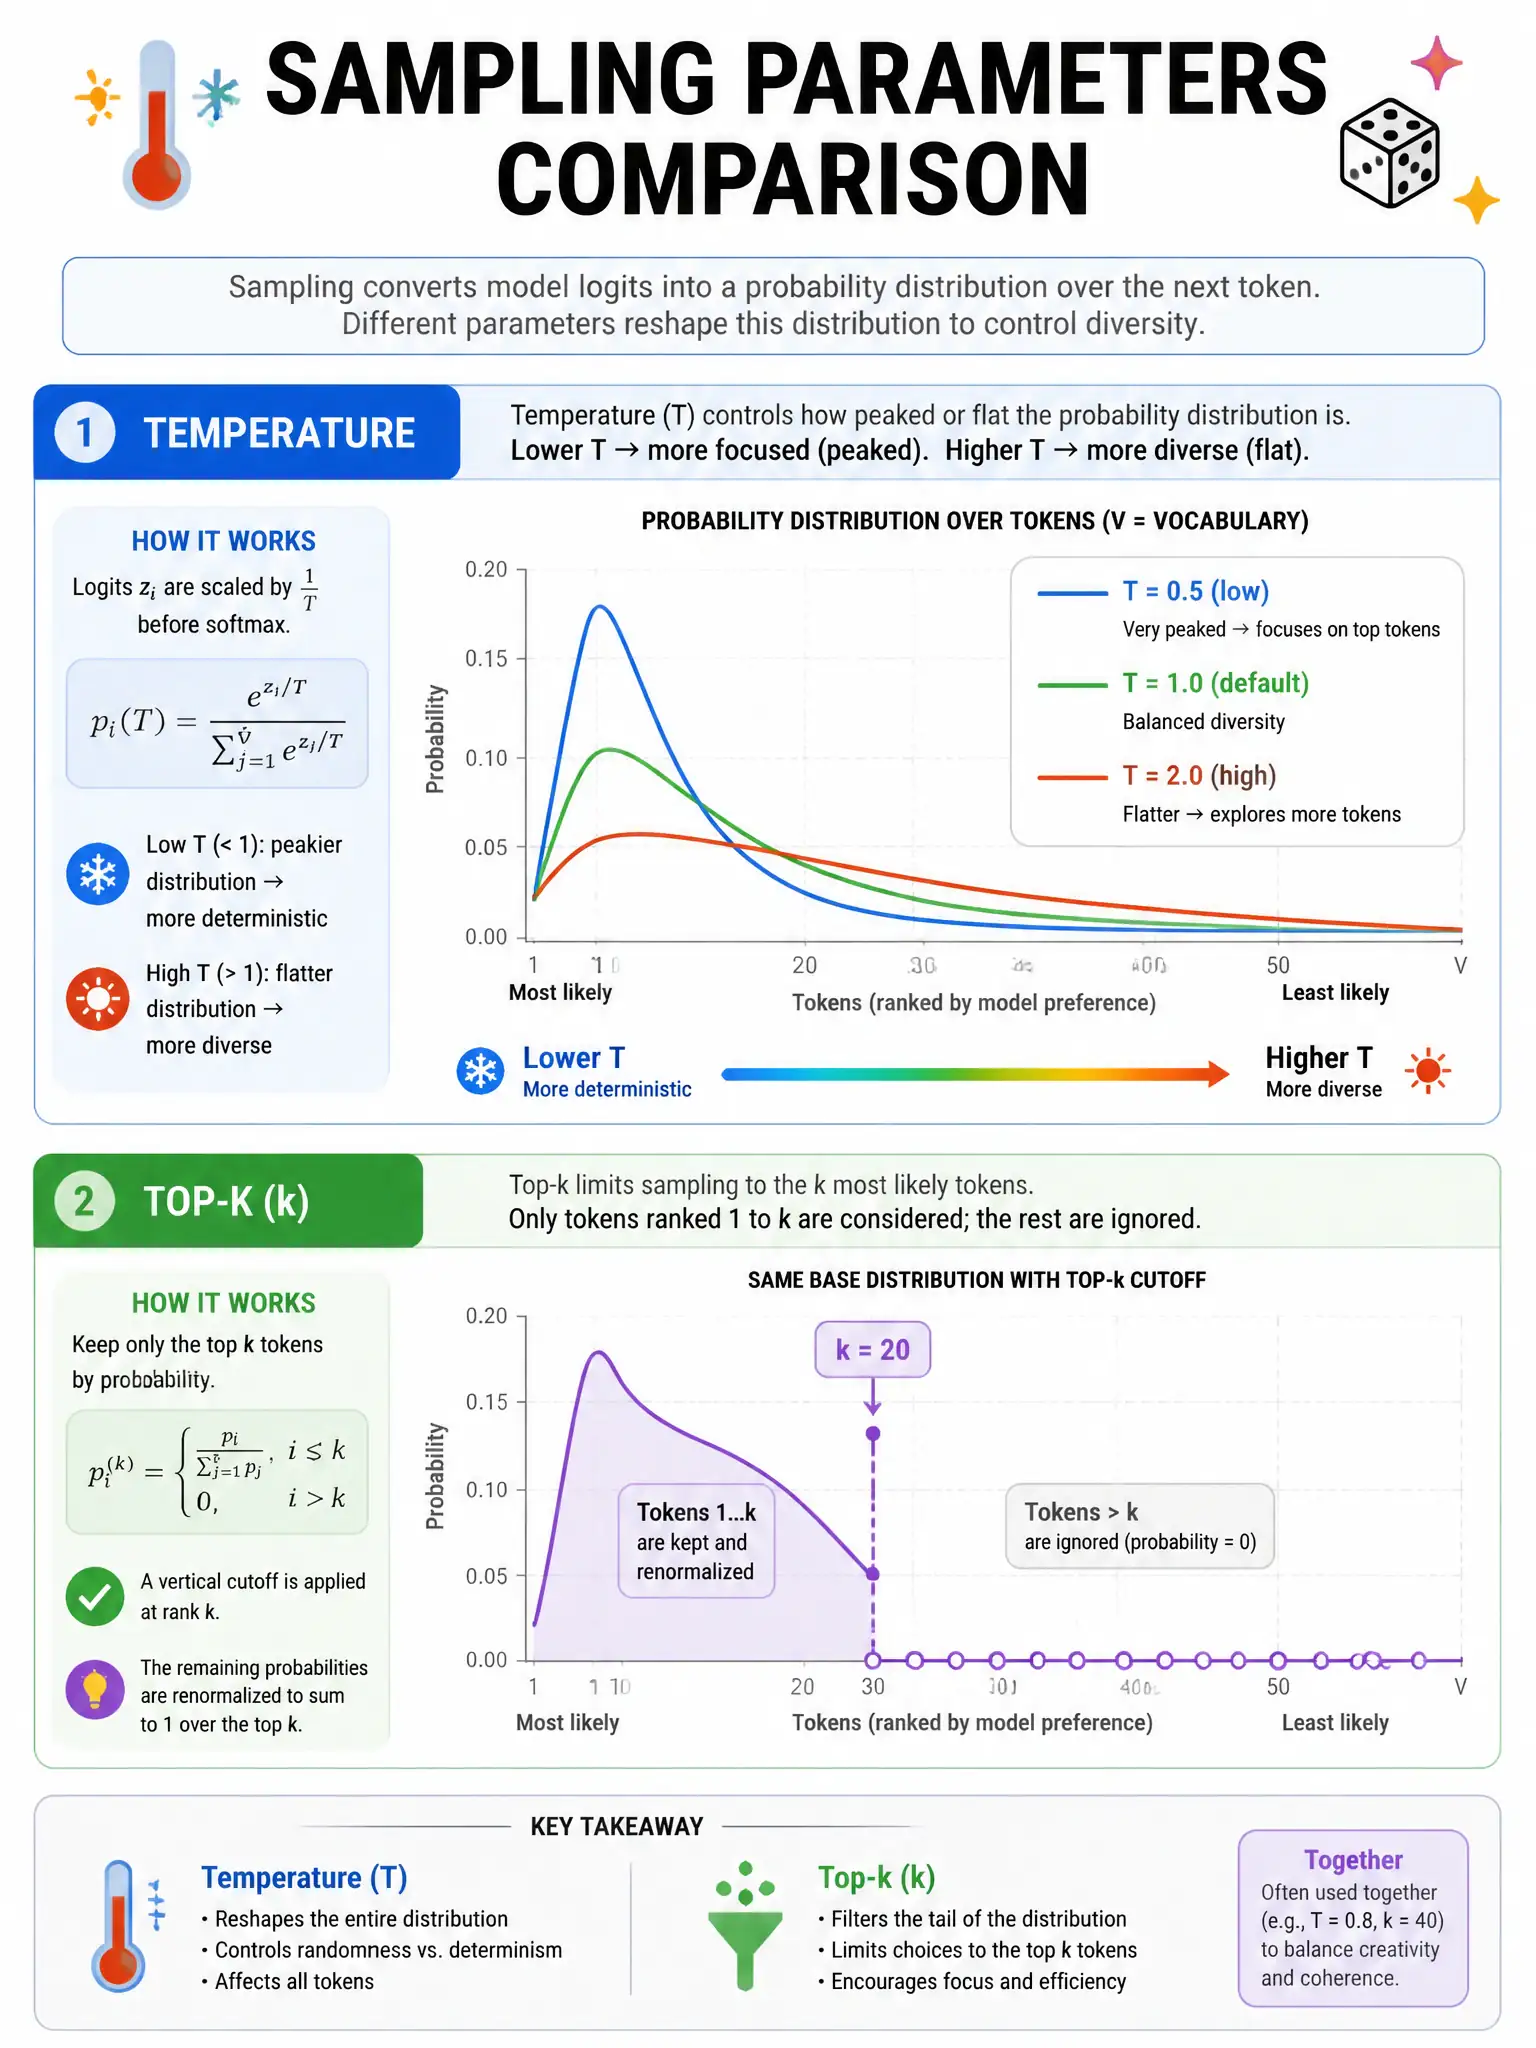
Short Explanation
You use temperature to reshape the probability distribution, squishing or spreading it. You use top_k to cut it off, so only the K most likely tokens are even considered. Both reduce chaos, in different ways.
Full Explanation
Temperature and top_k both control sampling randomness but work differently. Temperature scales the logit distribution before applying softmax — low temperature makes the distribution sharper (model more confident in top tokens), high temperature flattens it (more uniform). top_k limits the candidate set to the K highest-probability tokens before sampling, regardless of their actual probability values. Anthropic's Claude API uses temperature and top_p (not top_k by default), but understanding both helps when working with different models. The claim that temperature and top_k are the same parameter with different names is wrong because they are distinct mechanisms. The claim that temperature controls output length while top_k controls vocabulary size is wrong because it confuses them with unrelated parameters, such as max_tokens for length. The claim that top_k is a deprecated parameter that temperature has fully replaced is wrong because top_k is used in many model implementations.