
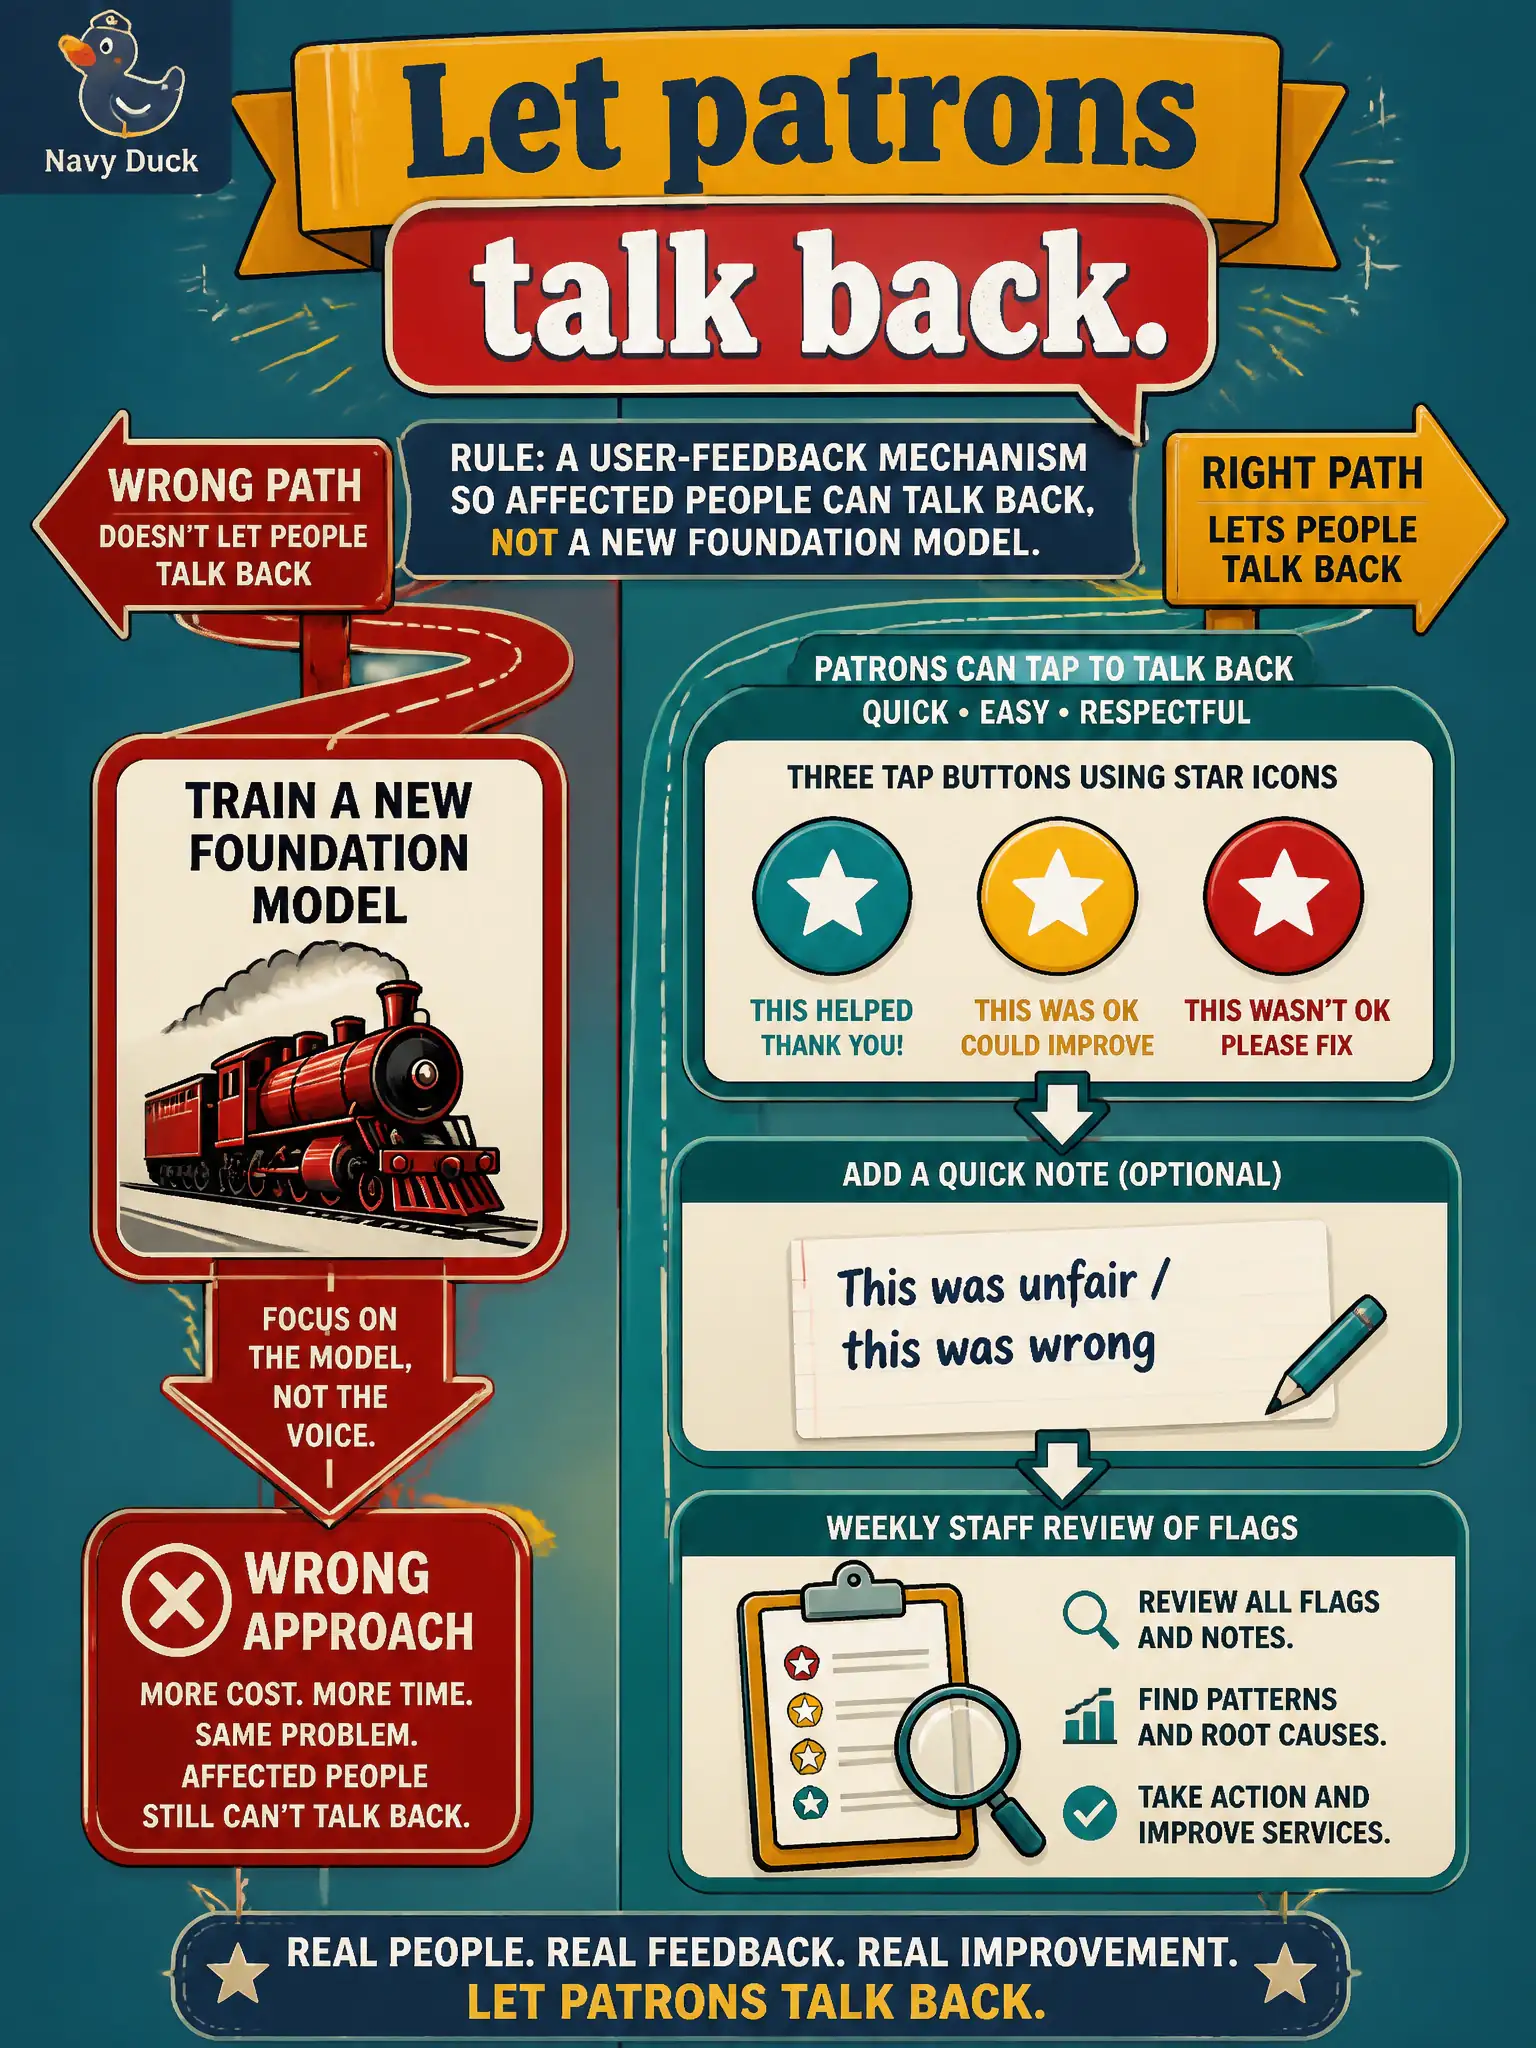
A community book-bike helper adds a three-face tap and a this was unfair / this was wrong note so patrons can flag bad answers. Staff review the flags weekly. Which explainable-AI design is that?
Select an answer to reveal the explanation.
Short Explanation
Think of a three-face tap and a this was unfair note, reviewed weekly. That is a user-feedback mechanism so people can talk back. It is not a new foundation model.
Full Explanation
The community book-bike helper's three-face tap and "this was unfair / this was wrong" note, reviewed weekly by staff, is a user-feedback mechanism. Explainable and human-centered AI is not only about showing a rationale; it is also about giving affected people a channel to talk back when answers feel harmful, biased, or simply wrong. Weekly review closes the loop so flags become evaluation evidence and remediation, not ignored complaints.
Calling the tap a new foundation model fails because collecting patron flags is an interaction and governance design, not a weight update. Calling it prompt caching fails because caching optimizes repeated inference prefixes; it does not create a fairness complaint channel. Calling it from-scratch pre-training fails because a weekend crawl does not equal a structured feedback and review process.
Exam caveat: feedback volume can be sparse or noisy—absence of flags is not proof of fairness, and raw flags need triage before they drive model changes. Operational check: log each flag with timestamp, answer snapshot, and reviewer disposition; set a weekly SLA to clear the queue; and feed recurring themes into evaluation cases before the next book-bike release.