
A scout-council lab wants to browse and try pretrained models, then optionally adapt one, without starting from random weights. They are not asking for a BI dashboard. Which AWS capability matches this job?
Select an answer to reveal the explanation.
Short Explanation
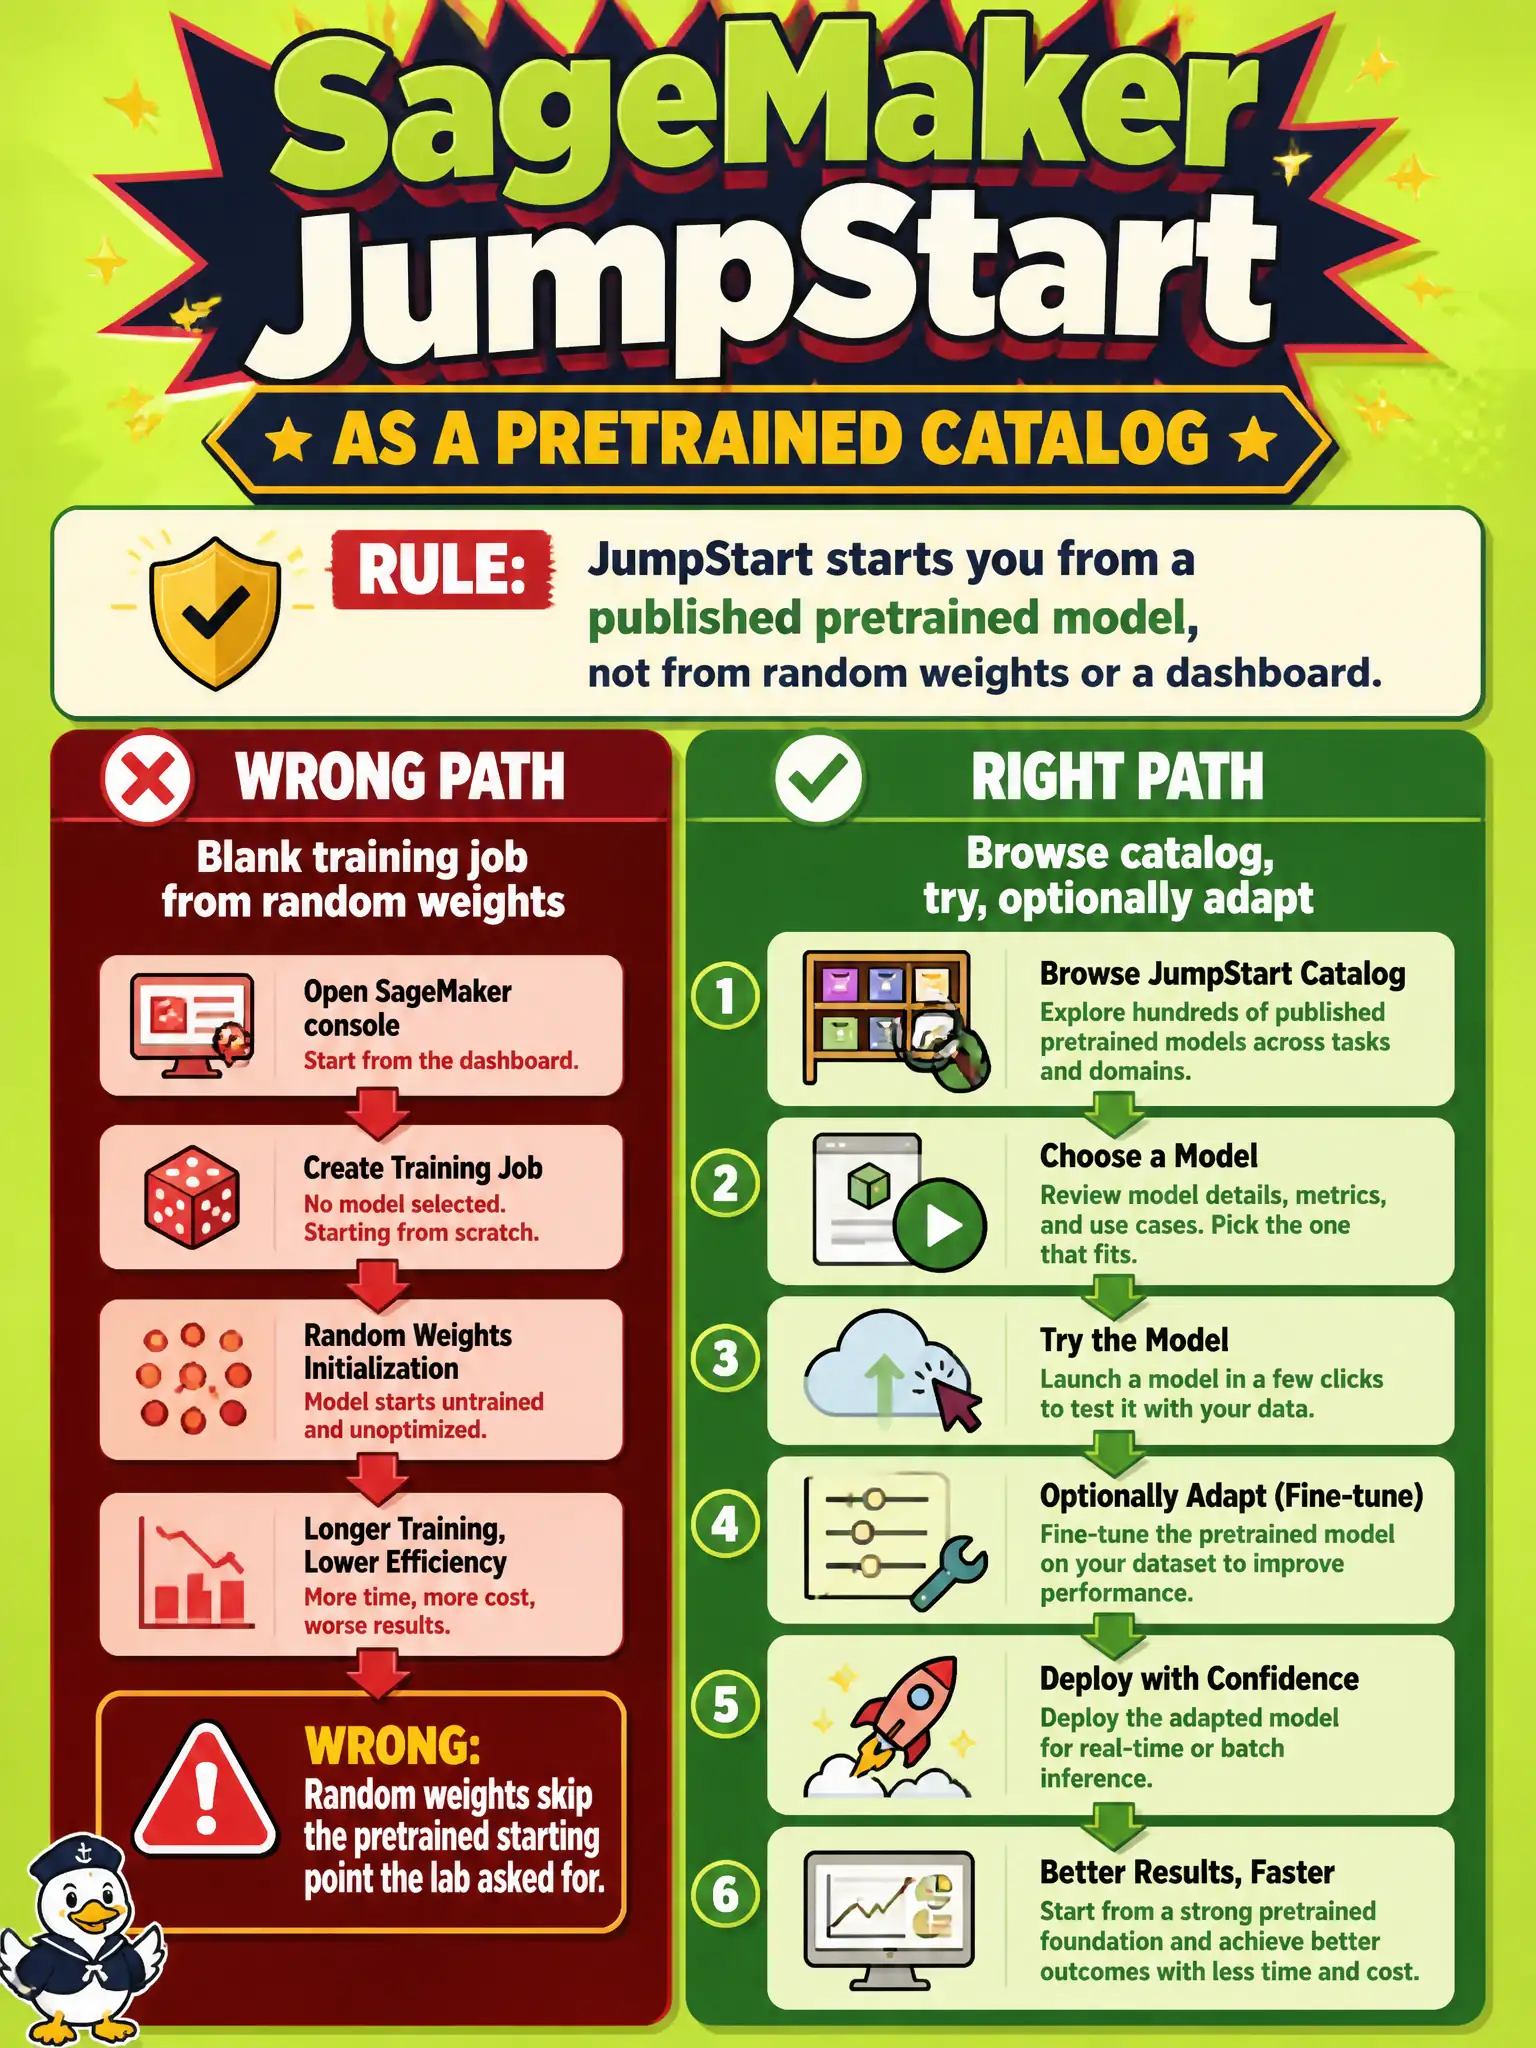
Think of a catalog of pretrained models you can try and then adapt, not starting from random weights. That is SageMaker JumpStart. Quick is a dashboard, and Transcribe is speech-to-text.
Full Explanation
Amazon SageMaker JumpStart is the catalog of pretrained models you can browse, try, and optionally adapt without starting from random weights. A scout-council lab that wants that start point—and is not asking for a BI dashboard—is describing JumpStart’s purpose in the SageMaker ecosystem: begin from a published artifact, evaluate, then adapt if needed.
A blank training job from random weights is the opposite start: full training from scratch instead of beginning from a published pretrained model. Amazon Quick is analytics and dashboards, not a pretrained model catalog you browse to adapt. Amazon Transcribe converts speech to text; browsing and trying models is not a speech-to-text problem and does not fulfill the lab’s request.
Exam caveat: starting from JumpStart still requires evaluation for your domain and careful handling of any fine-tuning data; pretrained does not mean automatically safe or accurate for council content. Operational check: pick a catalog candidate, run a labeled evaluation on council-like tasks, compare against a managed FM baseline, and only then decide whether to adapt or stay on prompting.
JumpStart’s value is speed to a competent baseline: try a published model on council-like samples before committing budget to from-scratch training. If adaptation is chosen, keep the adaptation data small, labeled, and access-controlled so the catalog convenience does not become an unmanaged data spill.