
A choir board introduced a meeting-notes summarizer and now tracks minutes saved per draft. They are not tracking a lab translation score. Which kind of metric is this?
Select an answer to reveal the explanation.
Short Explanation
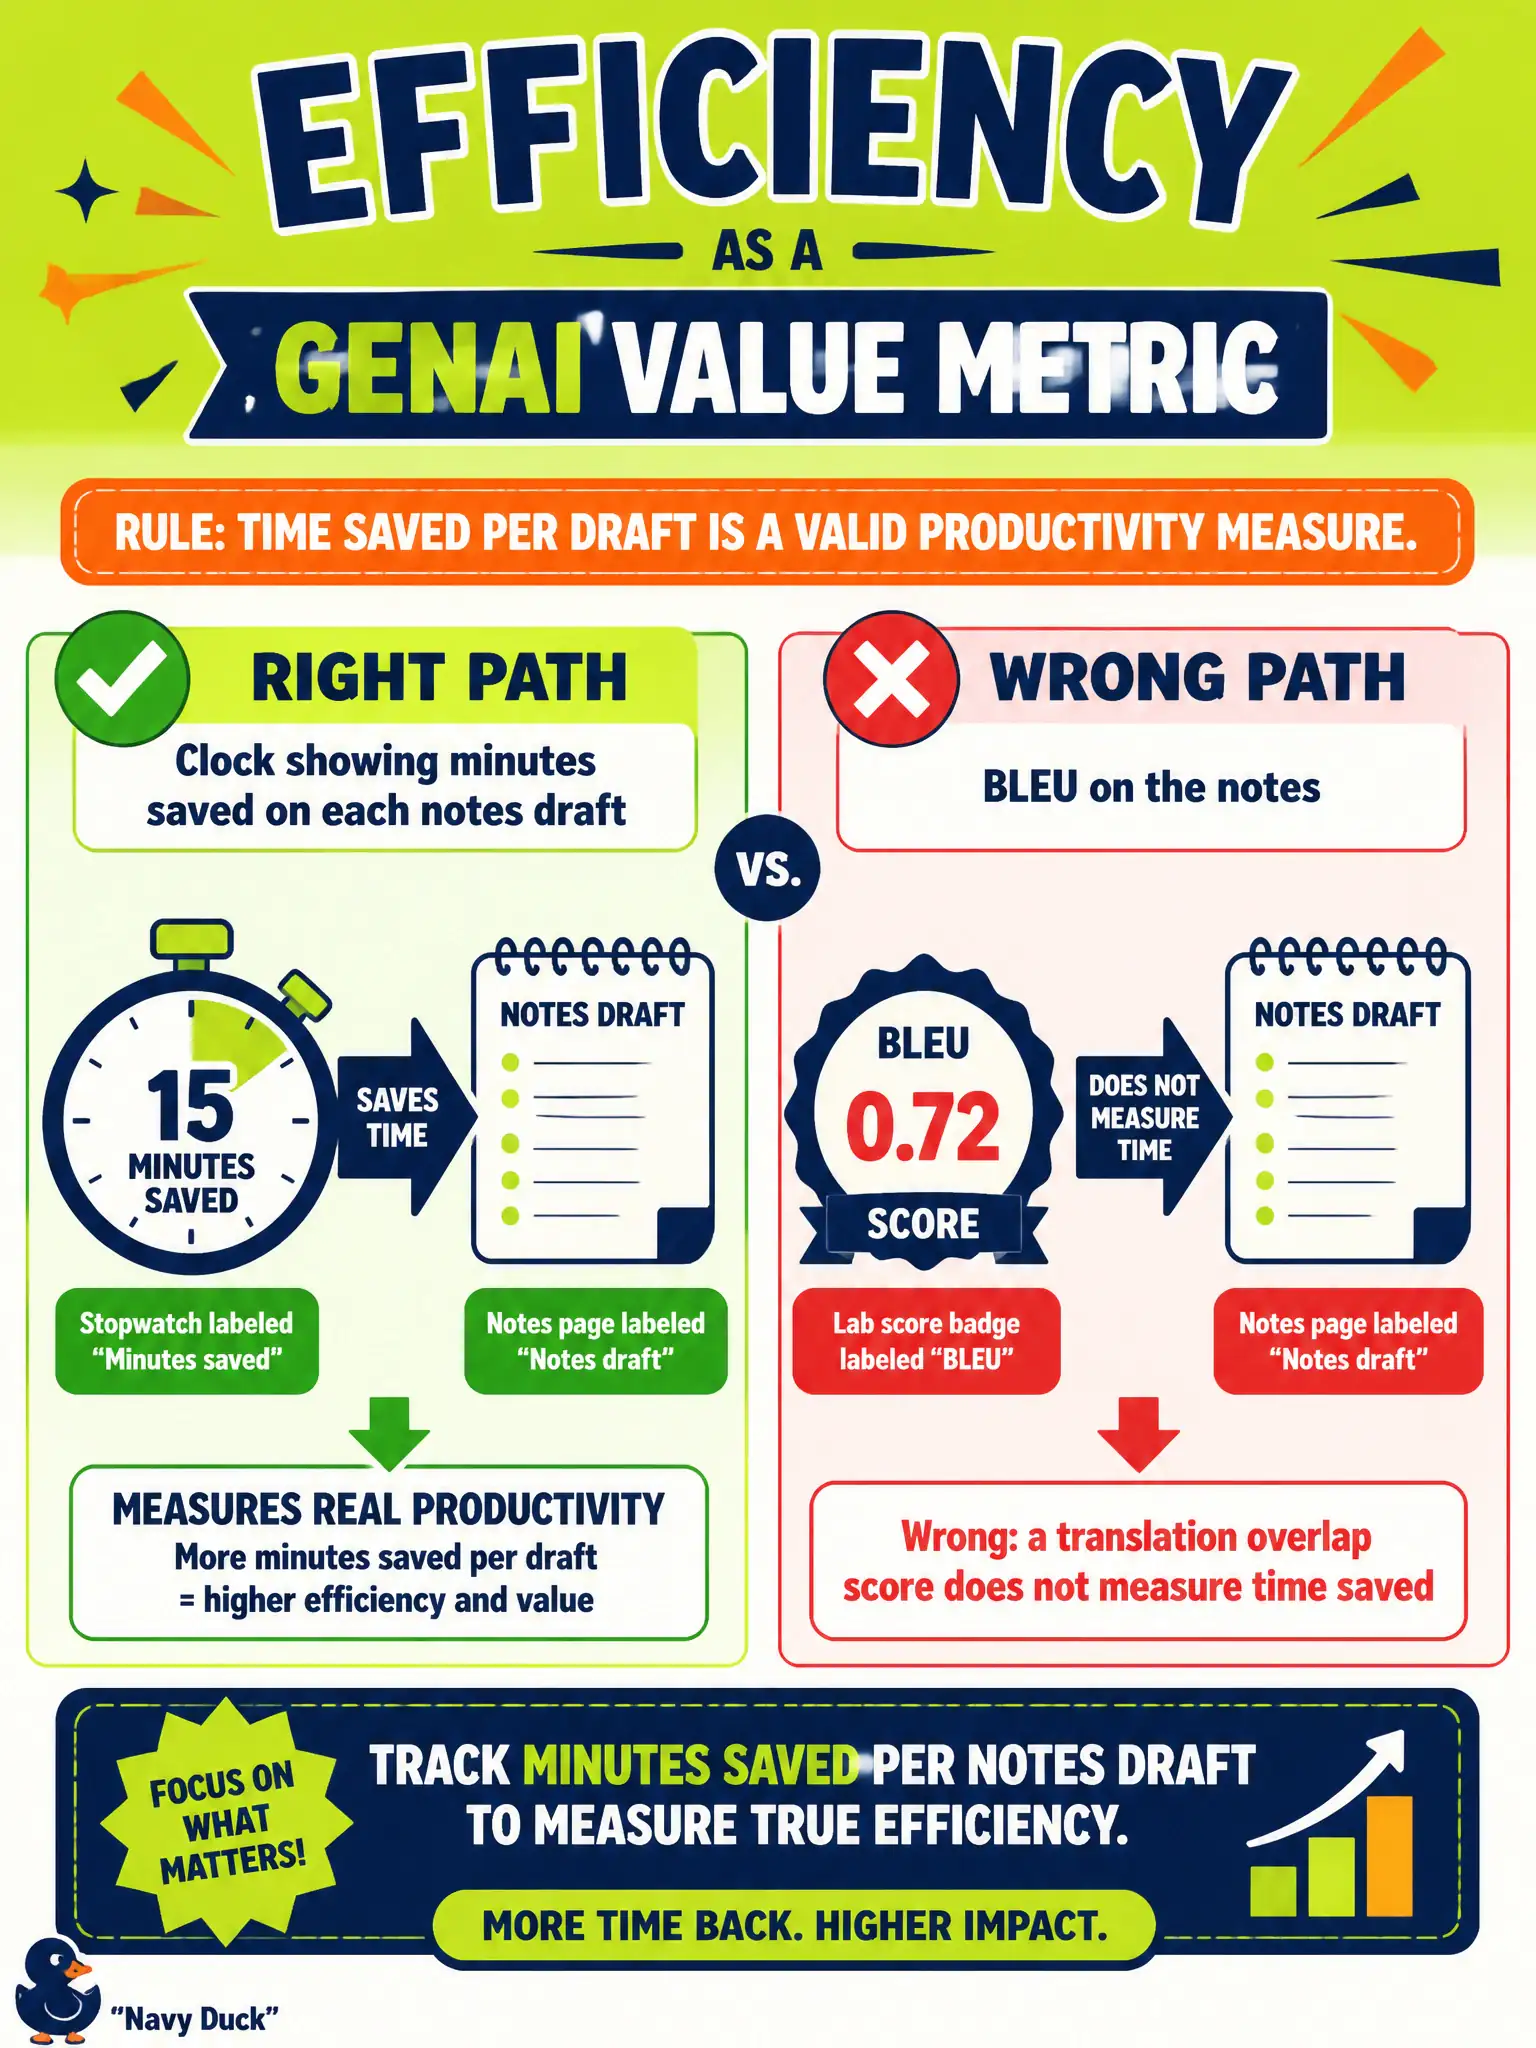
Think of a stopwatch on each notes draft. Minutes saved is an efficiency metric. BLEU is a translation exam, and this board is not running a one-second kiosk.
Full Explanation
Minutes saved per meeting-notes draft is an efficiency or productivity metric: it measures how GenAI changes the cost of doing a recurring staff task. Official Domain 2 value discussions allow that framing for generative helpers when leadership cares about time returned to people, not about a translation-lab score. The choir board’s stopwatch on drafts is therefore the right metric family for this use case.
Calling the same measure a BLEU score is wrong because BLEU estimates n-gram overlap with a reference translation; meeting notes are not a translation exam. A clustering metric on unused folder colors measures how documents group by metadata that the board does not use for success, so it cannot show productivity. A one-second kiosk latency SLA is a responsiveness target for a different product shape; this board is not running that kiosk and is not asking for that SLA.
Exam caveat: efficiency metrics still need a quality floor—faster drafts that invent decisions or miss action items can create rework that cancels the time saved. Operational check: sample reviewed notes for factual completeness while tracking median draft time, and stop treating speed alone as success if edit cycles grow.