
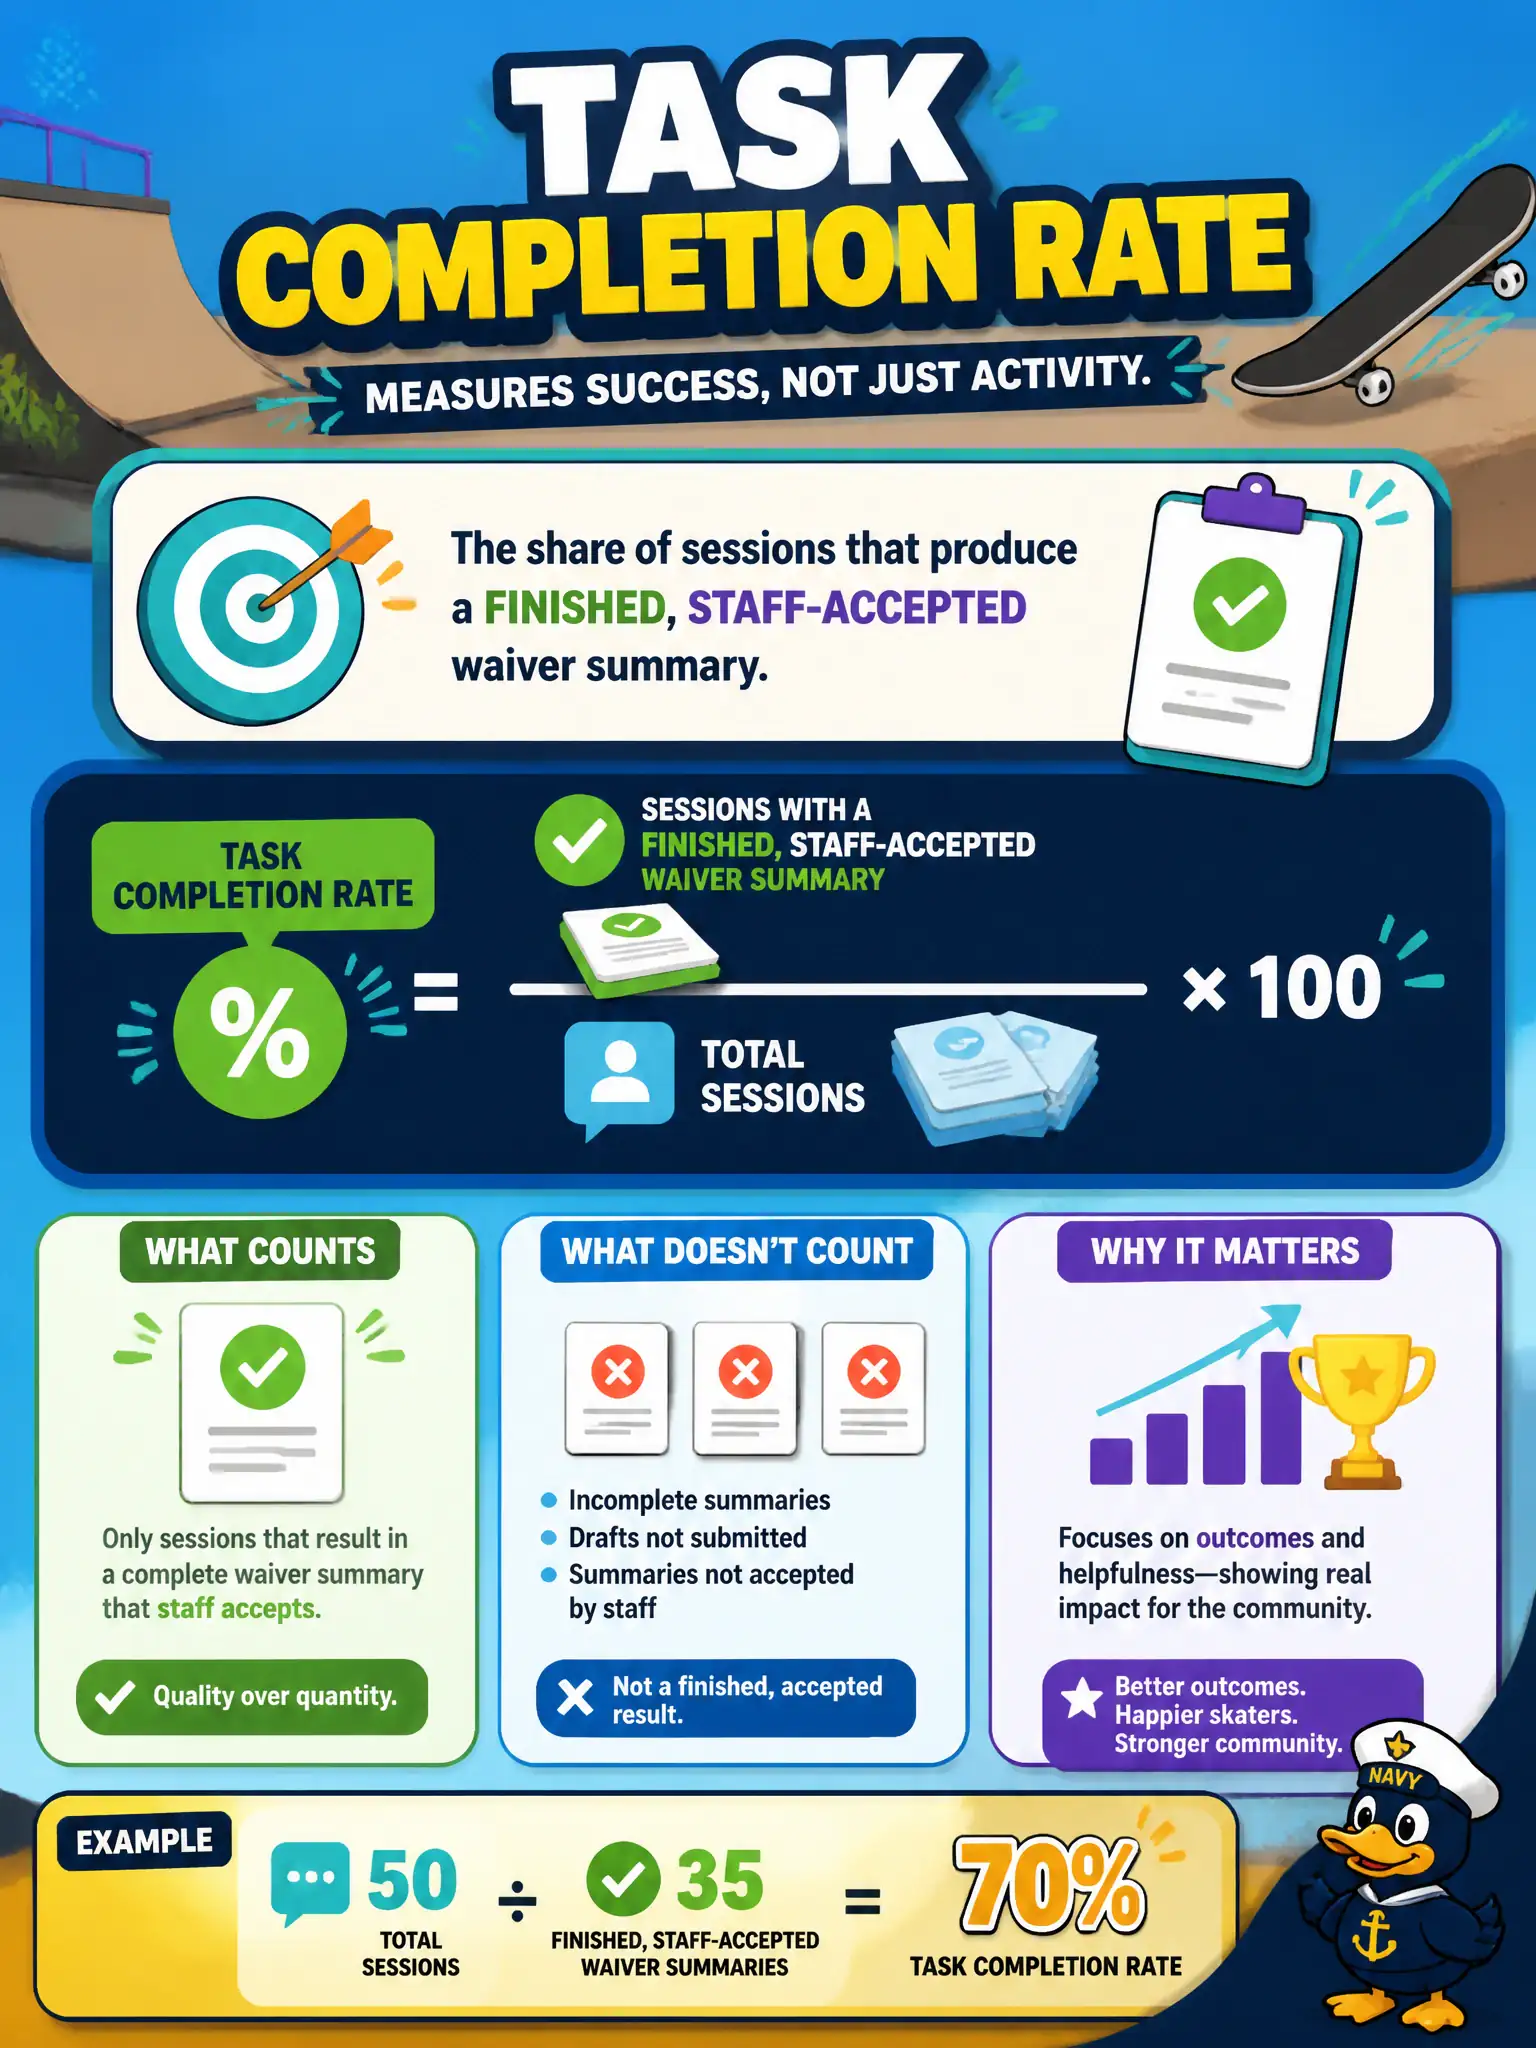
A municipal skate-shed waiver helper is scored on the share of sessions that produce a finished, staff-accepted waiver summary. Which metric is that?
Select an answer to reveal the explanation.
Short Explanation
Think of the share of sessions that produce a finished, staff-accepted waiver. That is task completion rate. BLEU, a cache, and a fluency quiz do not count finished waivers.
Full Explanation
The share of sessions that produce a finished, staff-accepted waiver summary is task completion rate. That metric counts end-to-end success against the municipal skate-shed workflow, including human acceptance, rather than scoring translation overlap or prose style. For operational helpers, completion of the required artifact is the right north star because incomplete waivers still create staff backlog and delay skate access.
BLEU is a translation overlap family; a finished waiver is not a translation task and should not be scored as one. Prompt caching reuses prompt prefixes for latency and cost; it is not a completion-rate metric for shed operations. A writing-fluency benchmark with no finished-waiver count ignores the actual acceptance criterion staff use at the shed desk.
Exam caveat: task completion can be gamed by incomplete but “submitted” drafts. Require staff-accepted as part of the definition so thin summaries do not count as wins on the municipal scorecard.
Operational check: log each session’s terminal state, compute accepted-waiver rate per release, and review a sample of incomplete sessions to see whether UX, retrieval, or model errors blocked completion before changing prompts or models for the skate-shed helper.