
Recycling-schedule API traffic spikes at evening set-out times. Operators want more Pods automatically when CPU rises. Which object changes the Deployment replica count?
Select an answer to reveal the explanation.
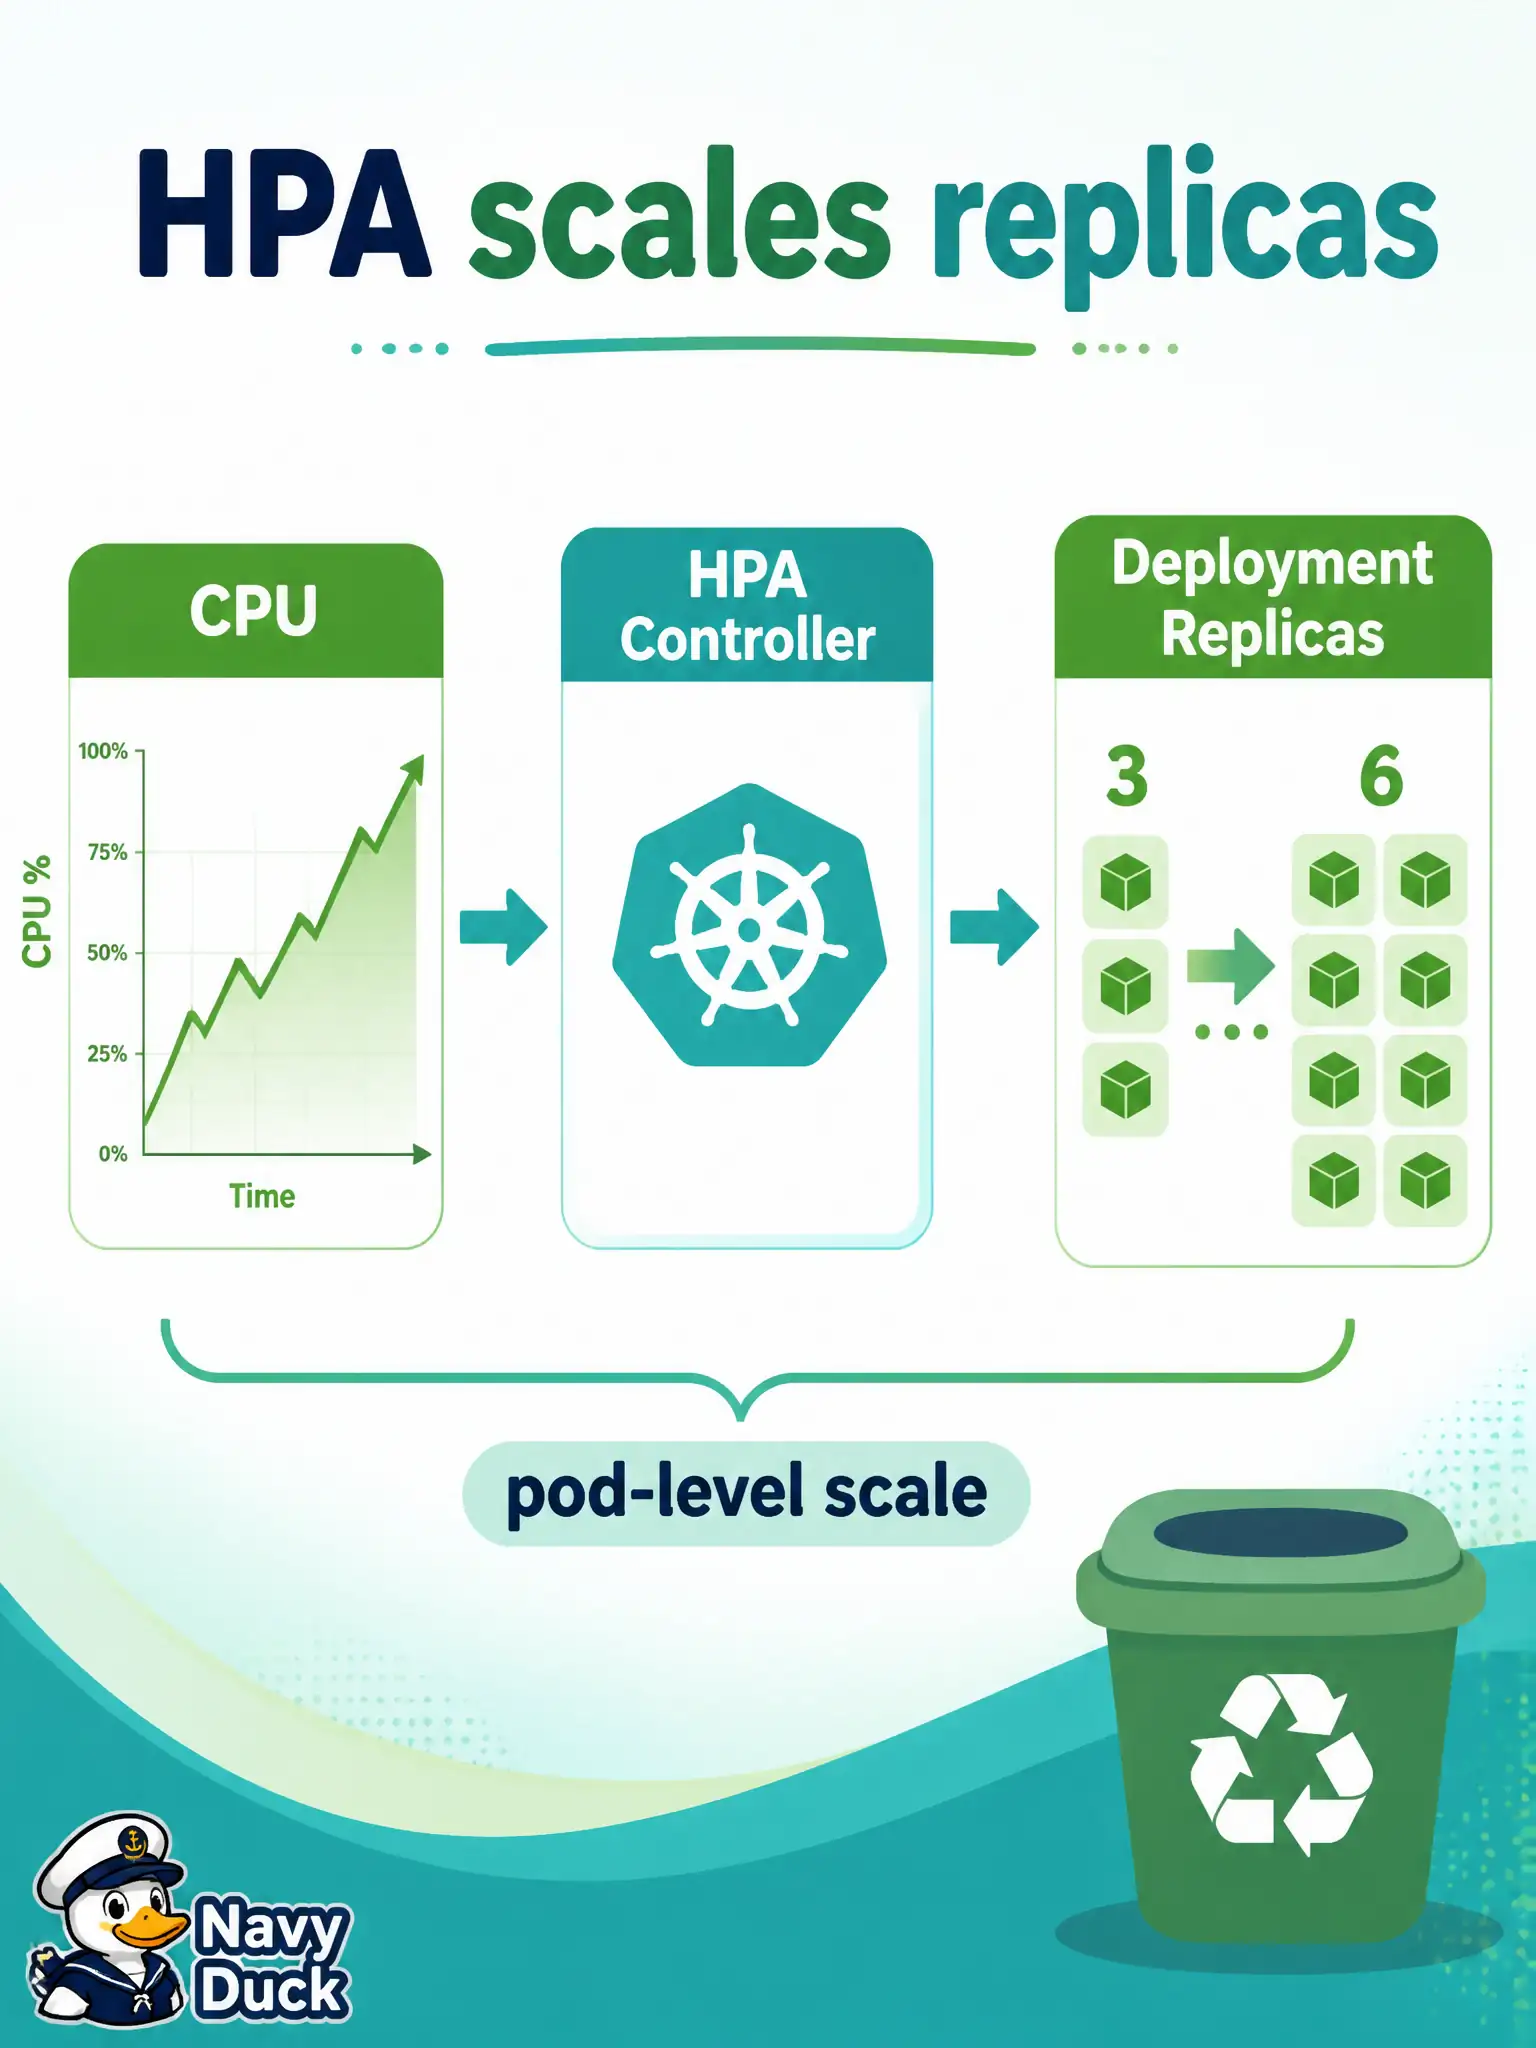
Short Explanation
HPA is the thermostat for replica count: watch CPU (or a custom metric), then dial Pods up or down. That is pod-level scale—not an email-only Monitoring alarm, and not a PDB freeze. On virtual-node pools, HPA scales Pods; you do not also stand up a node autoscaler for that pool.
Full Explanation
A Horizontal Pod Autoscaler watches a metric such as CPU (or a configured custom/external metric) and adjusts the Deployment's replica count up or down. For recycling-schedule traffic spikes at evening set-out times, HPA is the Kubernetes object that automatically grows Pods when demand rises and shrinks them when load falls—exactly the pod-level scale operators want. An OCI Monitoring alarm that only emails on-call does not change replica count. Alerting is useful operations telemetry, but without an automation path into the API server it leaves scaling as a human ticket, not an autoscaler. Vertical Pod Autoscaler is about container resource recommendations or vertical resizing, not about rewriting image tags, and it is not the primary tool for adding more Pods during a traffic spike. The distractor's claim that VPA only rewrites image tags is also conceptually wrong—and still would not deliver horizontal scale. A PodDisruptionBudget constrains how many Pods may be unavailable during voluntary disruptions; it does not permanently freeze replicas as an autoscaler substitute, nor does it raise replica count when CPU rises. Exam caveat: on virtual-node pools, HPA still scales Pods on the serverless data plane—you do not need a managed-node cluster autoscaler for that pool's worker VMs—but metrics must still flow (Metrics Server or custom metrics) or HPA cannot act. Operational check: generate evening-like CPU load against the API, confirm HPA status shows scaling toward a higher replica target, and verify new Pods become Ready and join the Service before traffic peaks clear.