
PROC TEXTMINE is run with WEIGHT=IDFLOG in the PARSE statement. What weighting scheme does IDFLOG apply to terms in the term-document matrix?
Select an answer to reveal the explanation.
Short Explanation
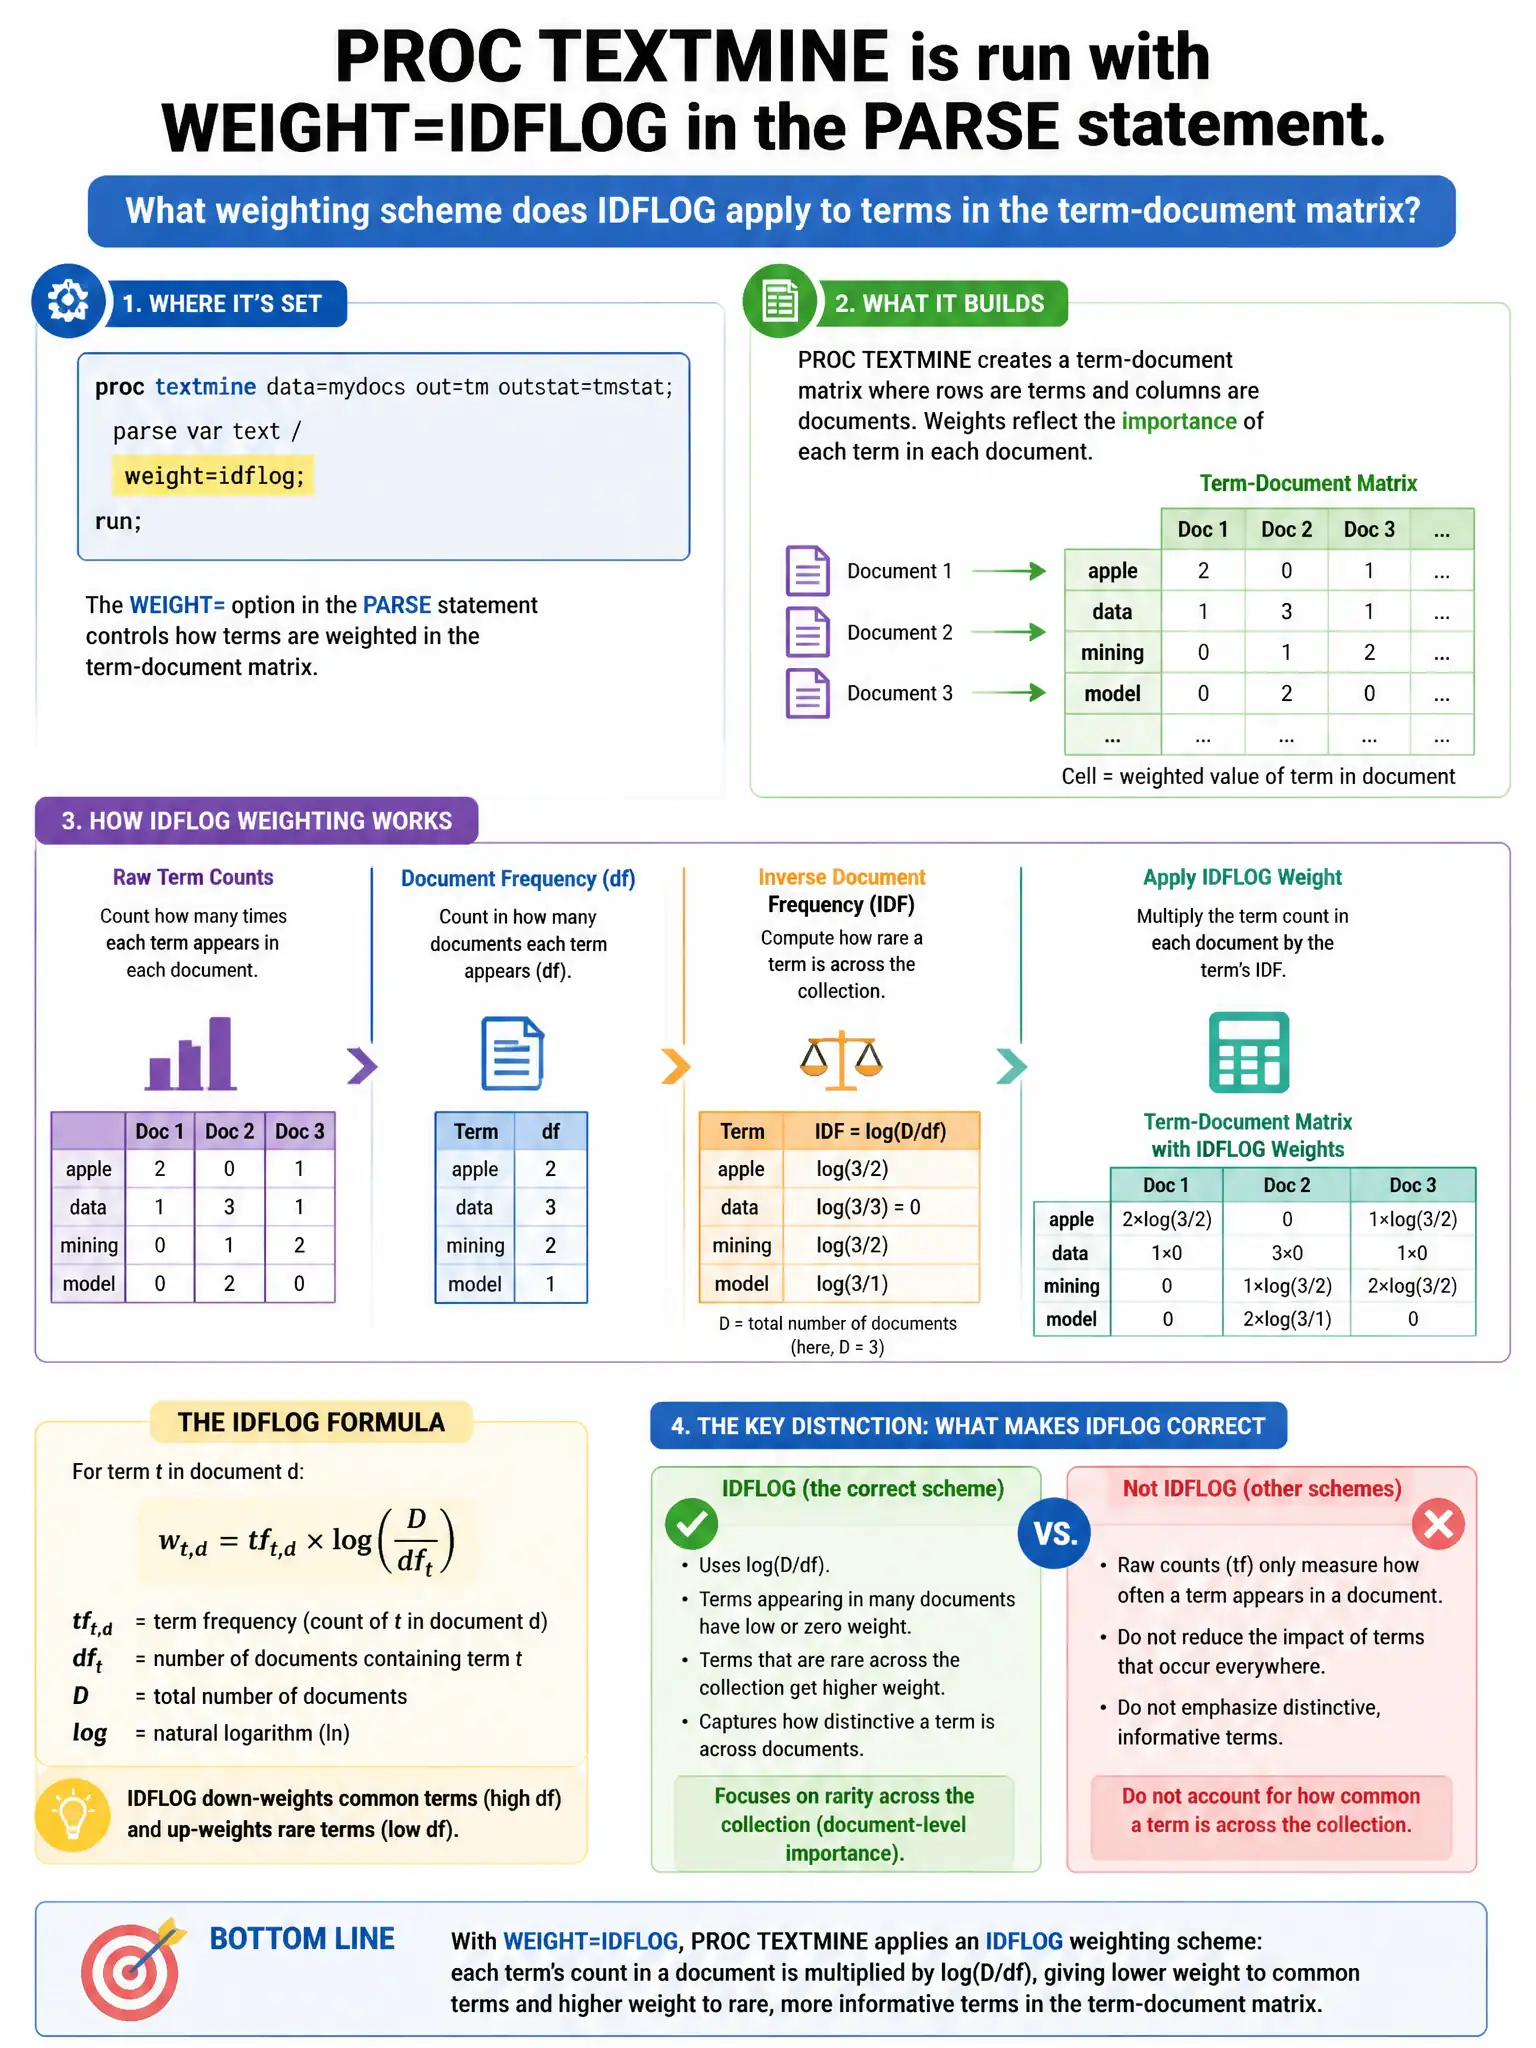
Here's the deal — you use WEIGHT=IDFLOG when you want terms that appear in fewer documents to get higher weight and common stopword-like terms to get lower weight. It's log-based inverse document frequency weighting, so rare domain-specific terms matter more.
Full Explanation
WEIGHT=IDFLOG in PROC TEXTMINE applies log-based inverse document frequency weighting: weight = log(total_docs / docs_containing_term). Terms that appear in nearly all documents, such as common words like 'the' or 'this', receive very low weight, while rare domain-specific terms receive high weight. This is the classic IDF weighting used in text retrieval. The option saying each cell is the raw count of term occurrences with no weighting applied describes a simple frequency weighting such as WEIGHT=FREQ, not IDFLOG. The option saying each cell is term frequency normalized by document length describes a length-normalized TF or entropy/normalization variant, not IDFLOG. The option saying IDFLOG squares the term frequency to amplify high-frequency terms within each document is wrong because IDFLOG does not square term frequencies.