
A practitioner builds a stacking ensemble with logistic regression, gradient boosting, and random forest as base learners, and a ridge regression as the meta-learner. What is the critical data hygiene requirement for training the meta-learner?
Select an answer to reveal the explanation.
Short Explanation
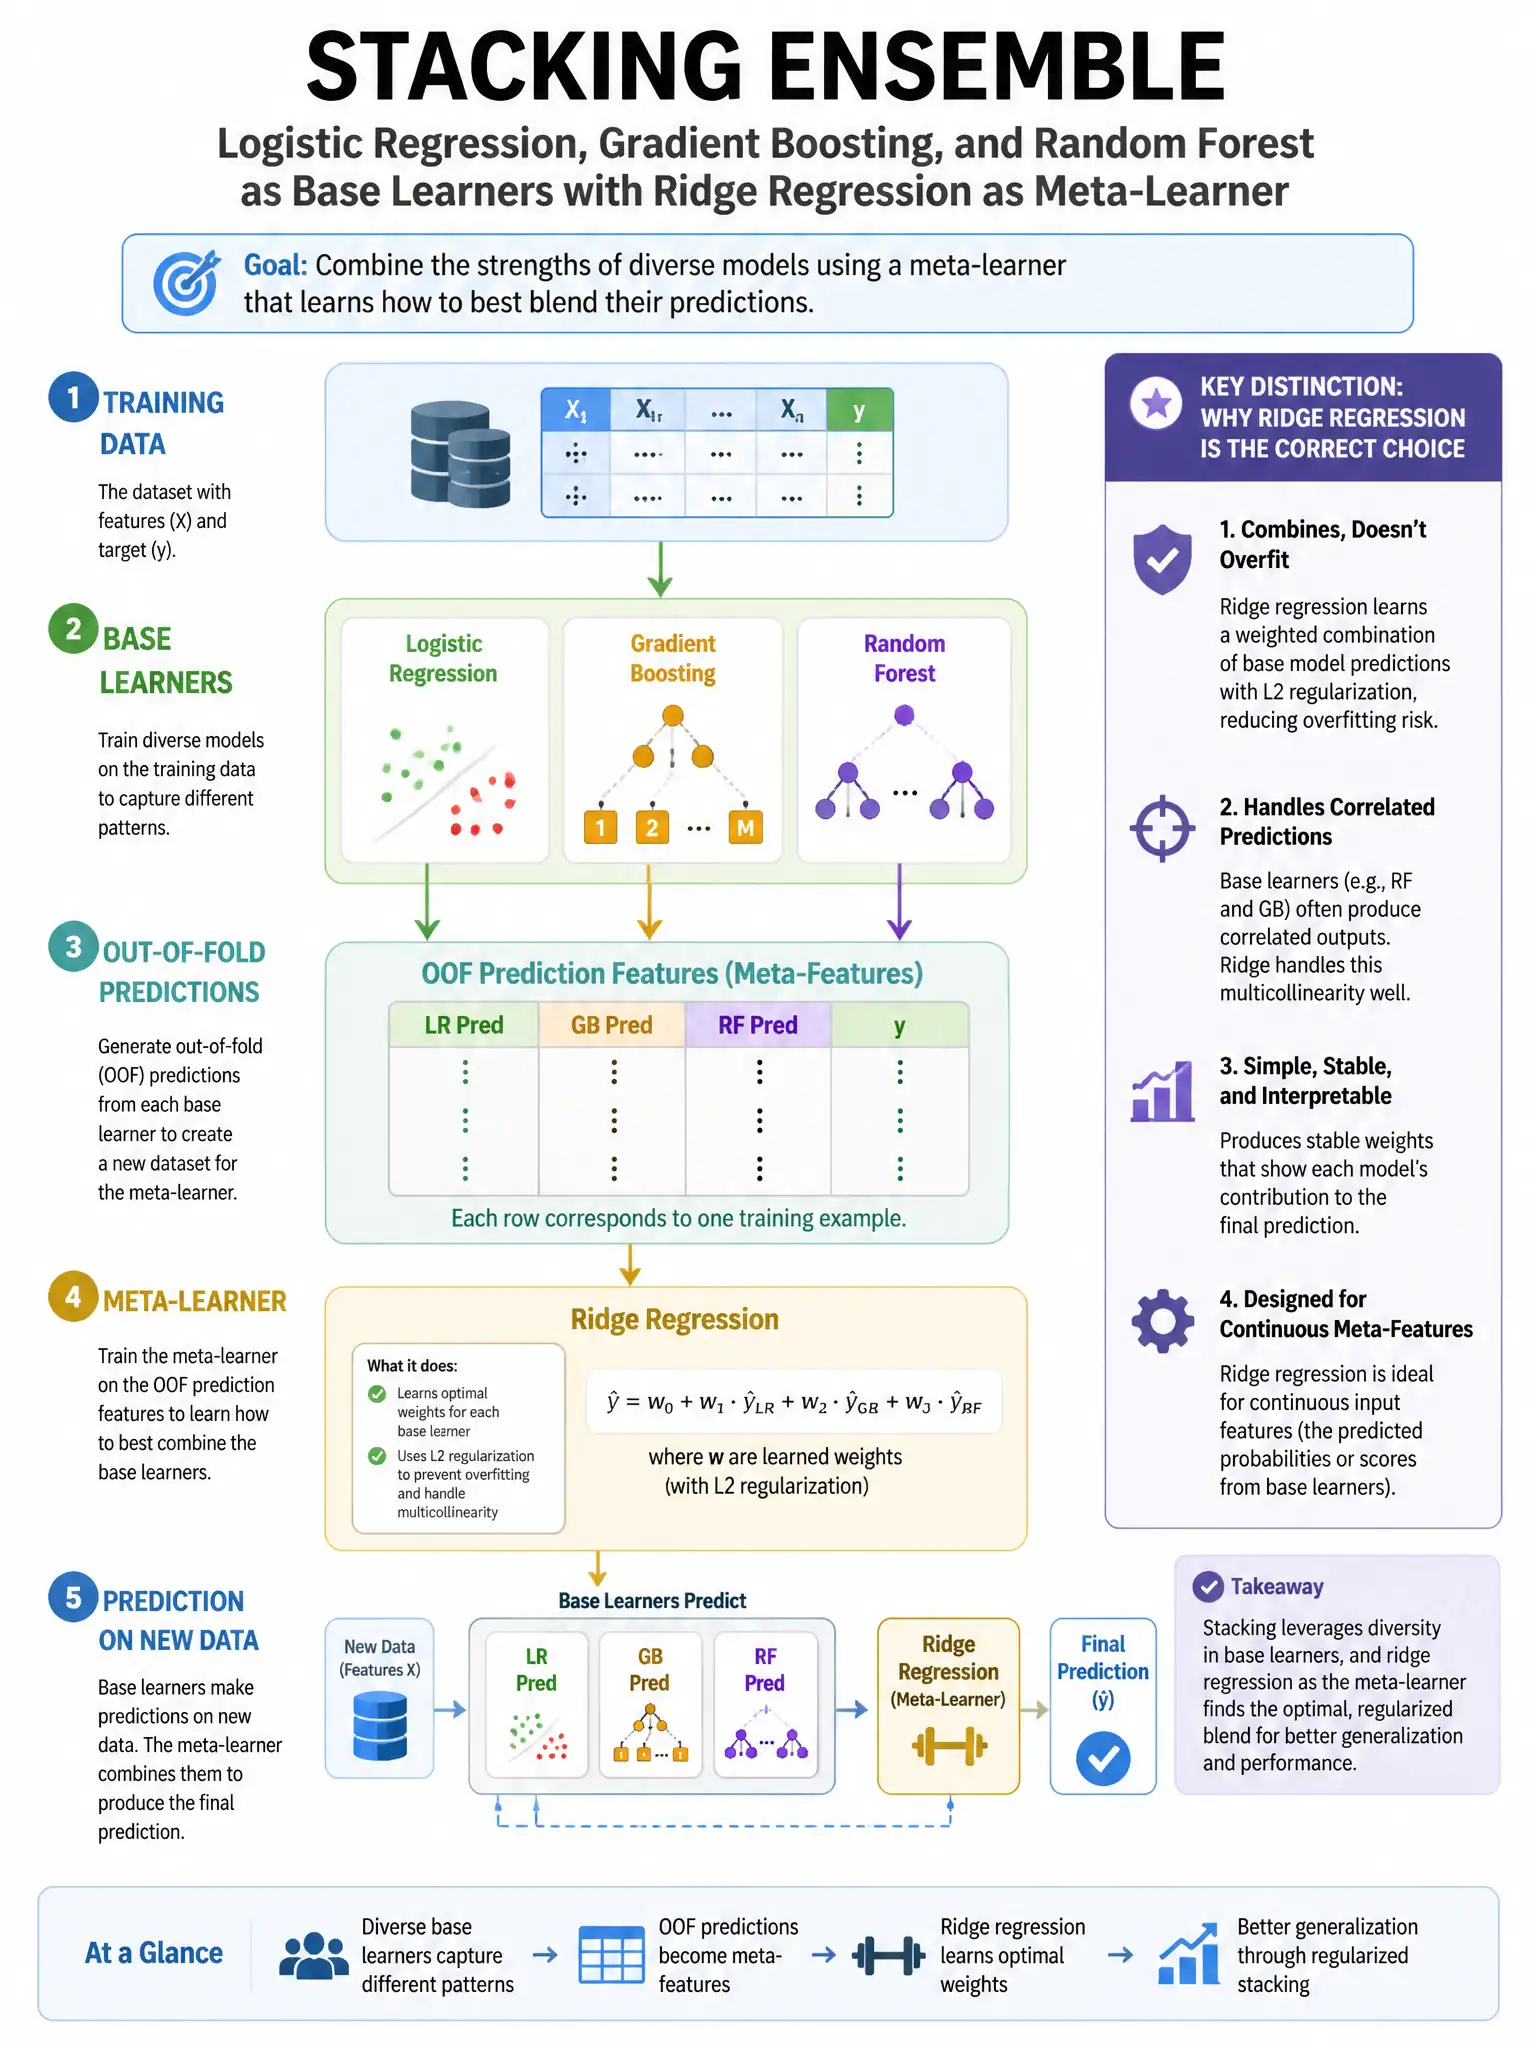
Here's the deal — train the meta-learner on out-of-fold predictions, not in-sample predictions. If base models predict their own training data, their overfitting leaks optimistic information to the meta-learner. Cross-validation gives each row a prediction from a base learner that never saw it.
Full Explanation
The critical requirement is that the meta-learner be trained on base-learner predictions computed using held-out cross-validation folds, not on in-sample predictions. If in-sample predictions are used as meta-learner features, overfitted base models produce overly optimistic predictions on their own training data, leaking information to the meta-learner. Cross-validation gives each observation a prediction from a base learner that never saw it. Requiring identical hyperparameters is wrong; diversity is beneficial. Requiring a separate test set is wrong; that set is for final evaluation, not meta-learner training. Requiring a 50/50 split is wrong; it wastes data and does not address leakage.