
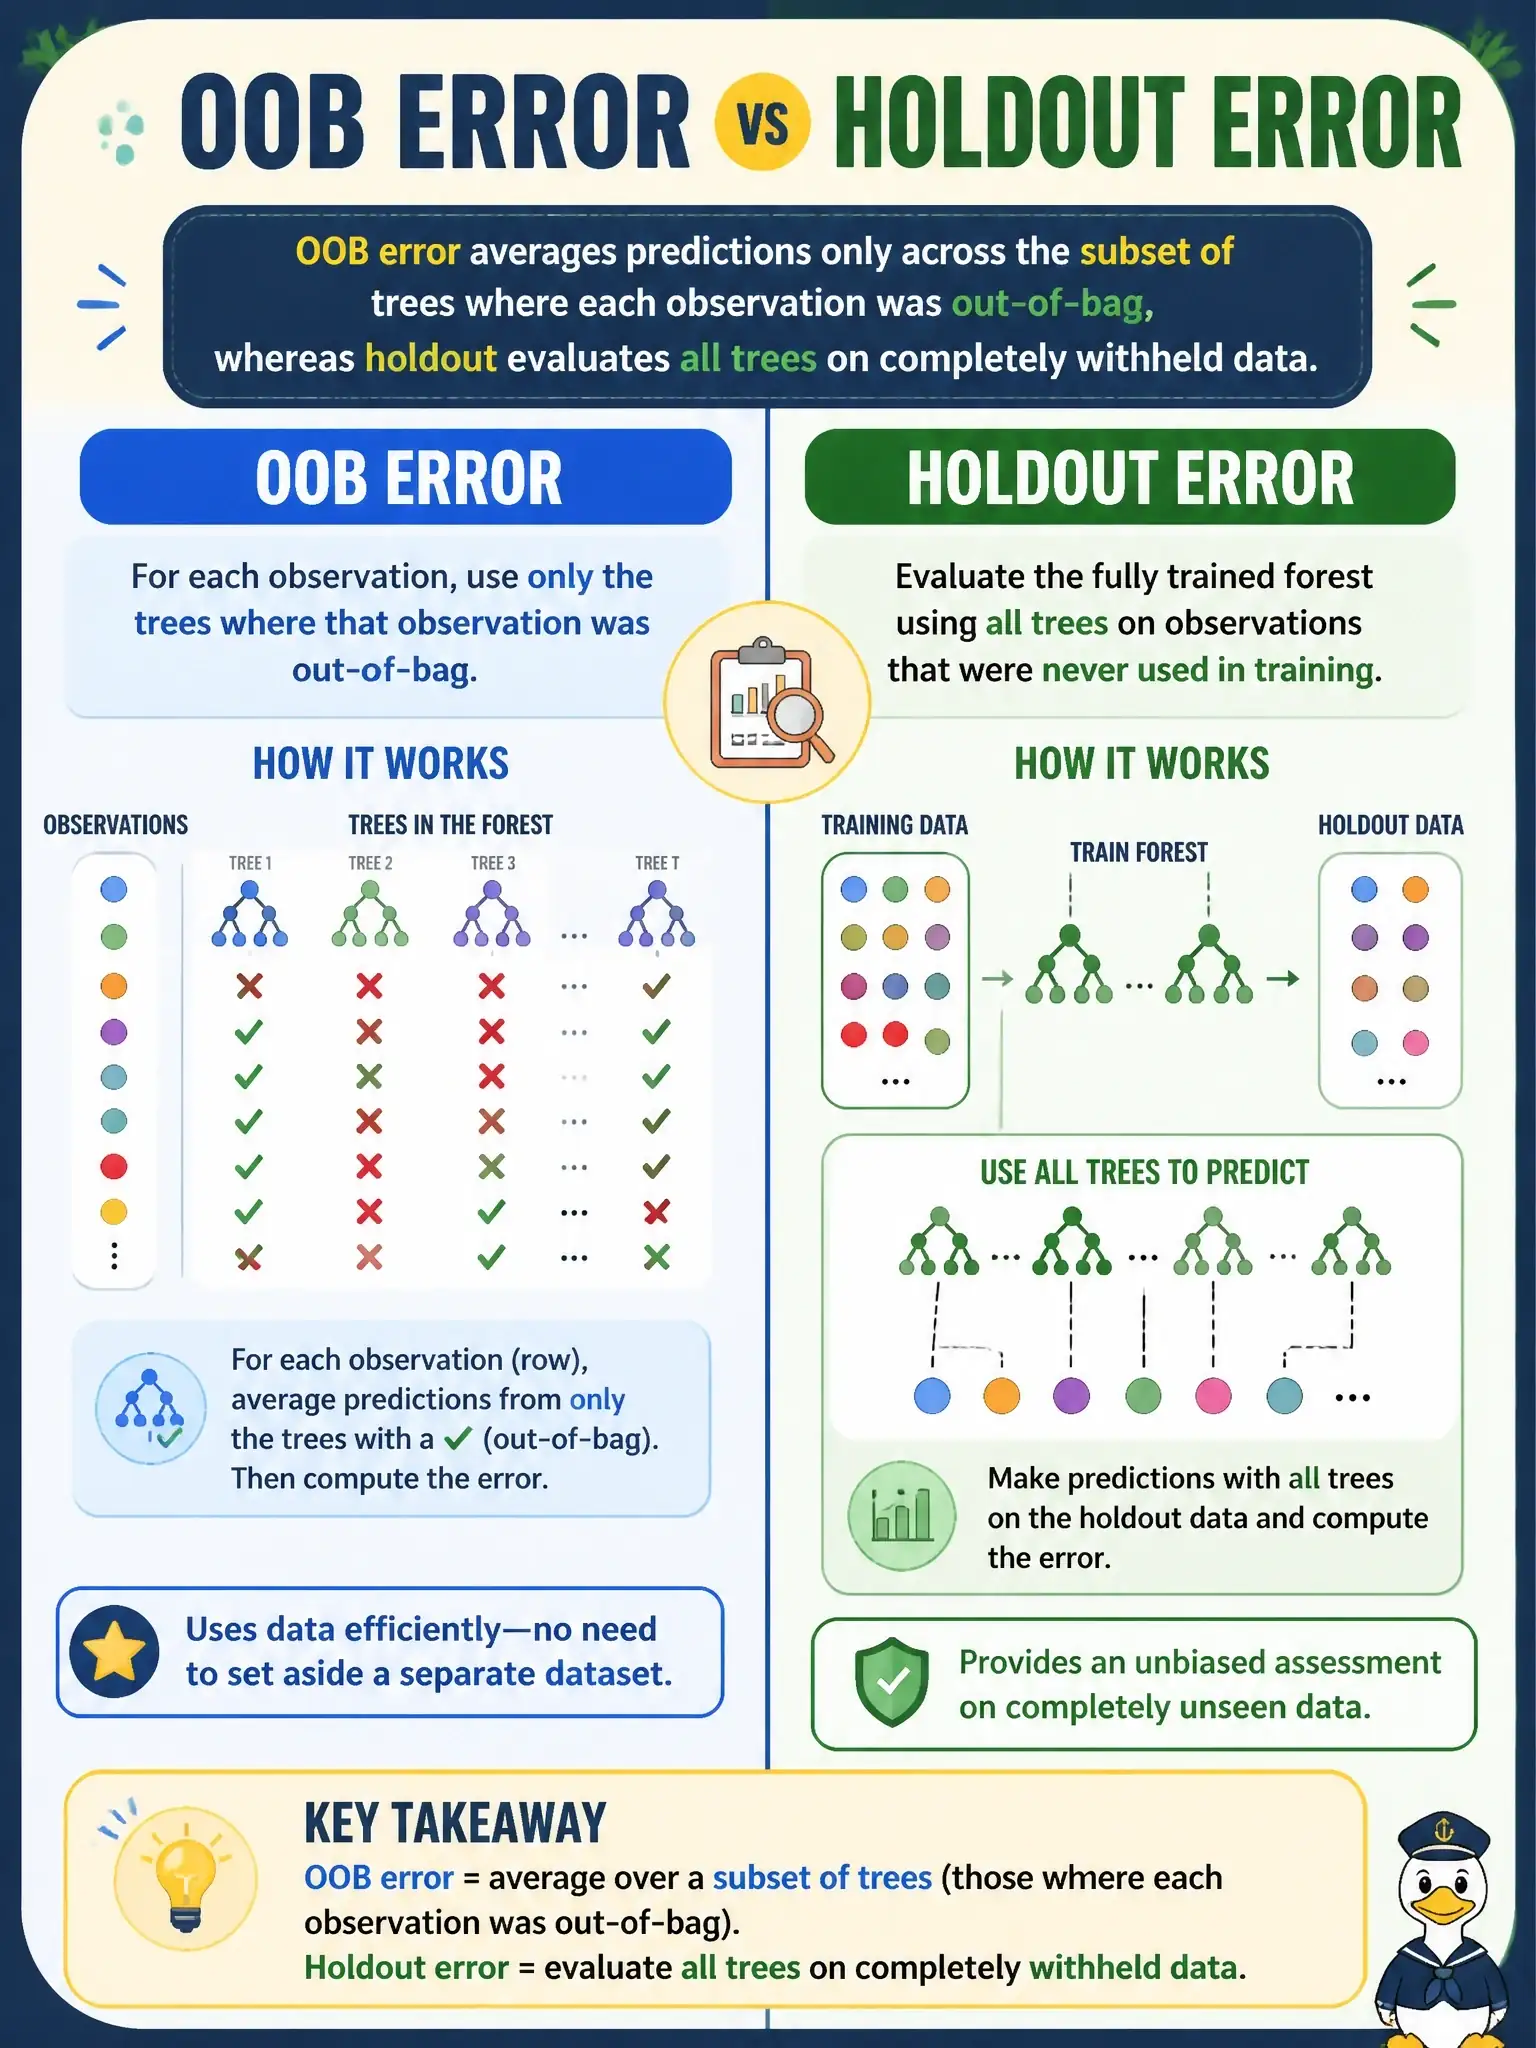
PROC HPFOREST generates an OOB error estimate as part of its default output. What distinguishes the OOB error estimate from a standard holdout validation error?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you get OOB error because each observation is tested only on the trees that didn't see it, while holdout tests every tree on data held back from training. No upfront split is needed, but the math isn't the same.
Full Explanation
The correct distinction is that OOB error averages predictions only across the subset of trees where each observation was out-of-bag, whereas holdout evaluates all trees on completely withheld data. In random forests, each observation trains about 63% of trees and validates the remaining about 37%. No data is permanently withheld from training, while a holdout set is excluded from all training. The claim that OOB error is computed only on training observations is wrong because OOB uses out-of-bag observations for each tree. The claim that OOB uses all observations for both training and error estimation misses that each observation contributes only from trees where it was out-of-bag. The claim that OOB and holdout are computed identically is wrong because OOB averages out-of-bag predictions, while holdout evaluates all trees on withheld data.