
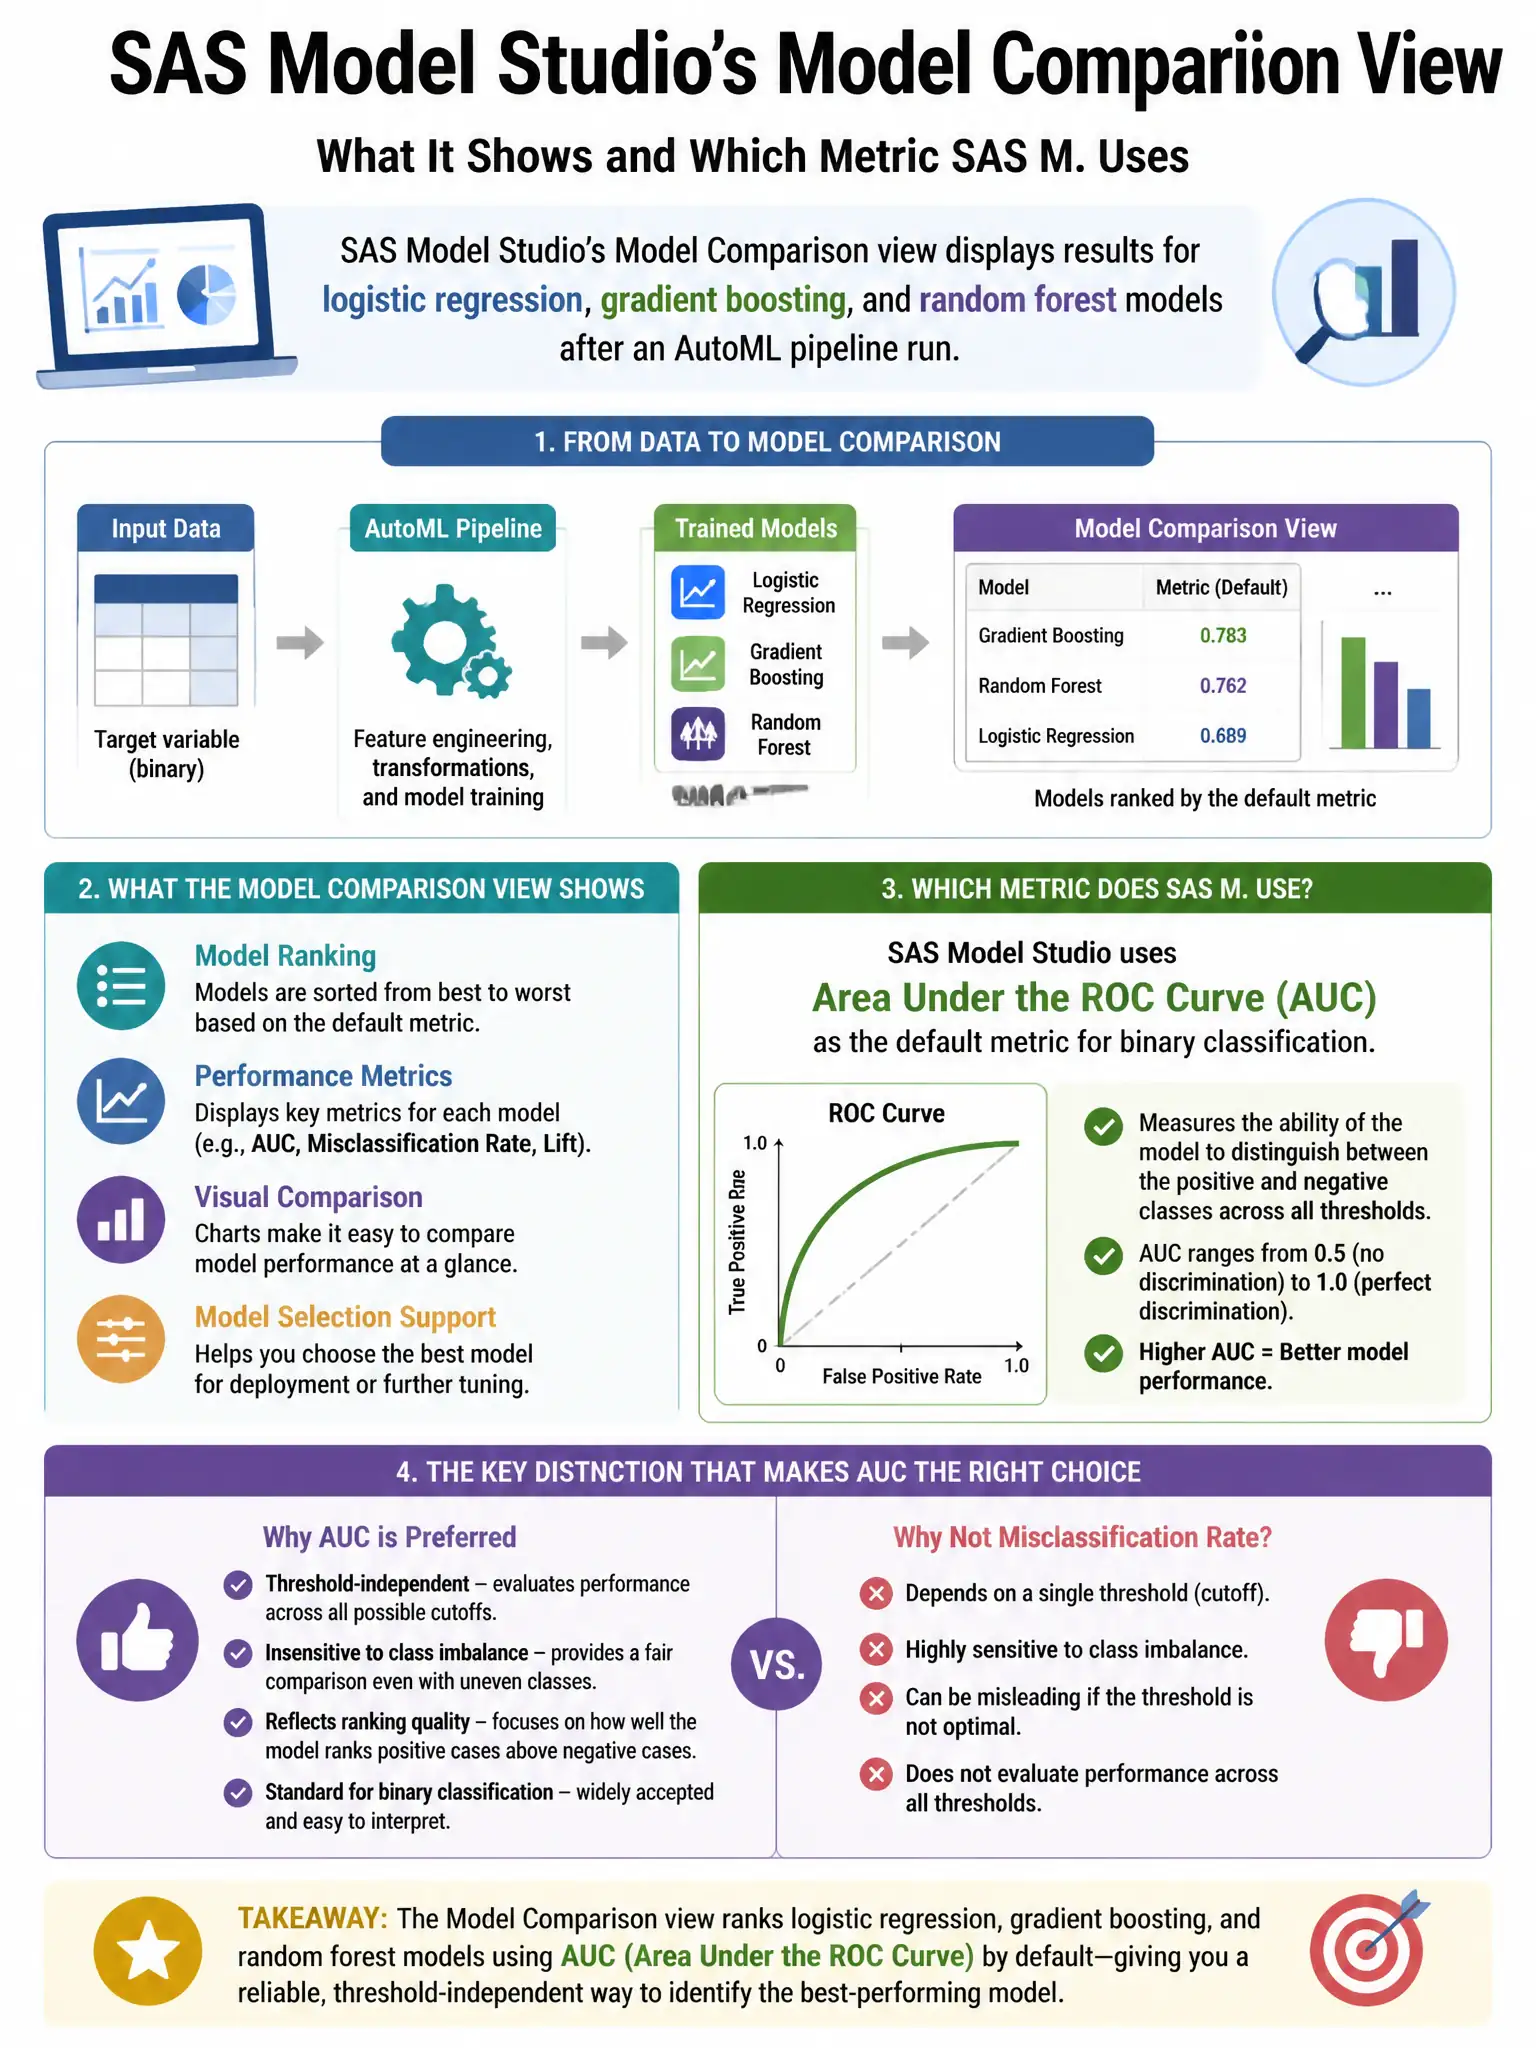
SAS Model Studio's Model Comparison view displays results for logistic regression, gradient boosting, and random forest models after an AutoML pipeline run. Which metric does SAS Model Studio use by default to rank classification models in this comparison?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — SAS Model Studio ranks classification models by misclassification rate on the validation dataset, so you're comparing how often predictions miss on held-out validation data. Training-set metrics can make an overfit model look better, and the test set is held out for final evaluation.
Full Explanation
SAS Model Studio defaults to validation-set misclassification rate as the primary ranking metric for classification pipelines in the model comparison view. Accuracy on the training dataset is wrong because training metrics favor overfitting models. KS statistic on the training dataset is wrong because training-data metrics are also biased. Gini coefficient on the test dataset is wrong because the test set is held out and not used for comparison or ranking.