
Which NLP technique maps each word to a dense vector where semantically similar words are geometrically close in the vector space?
Select an answer to reveal the explanation.
Short Explanation
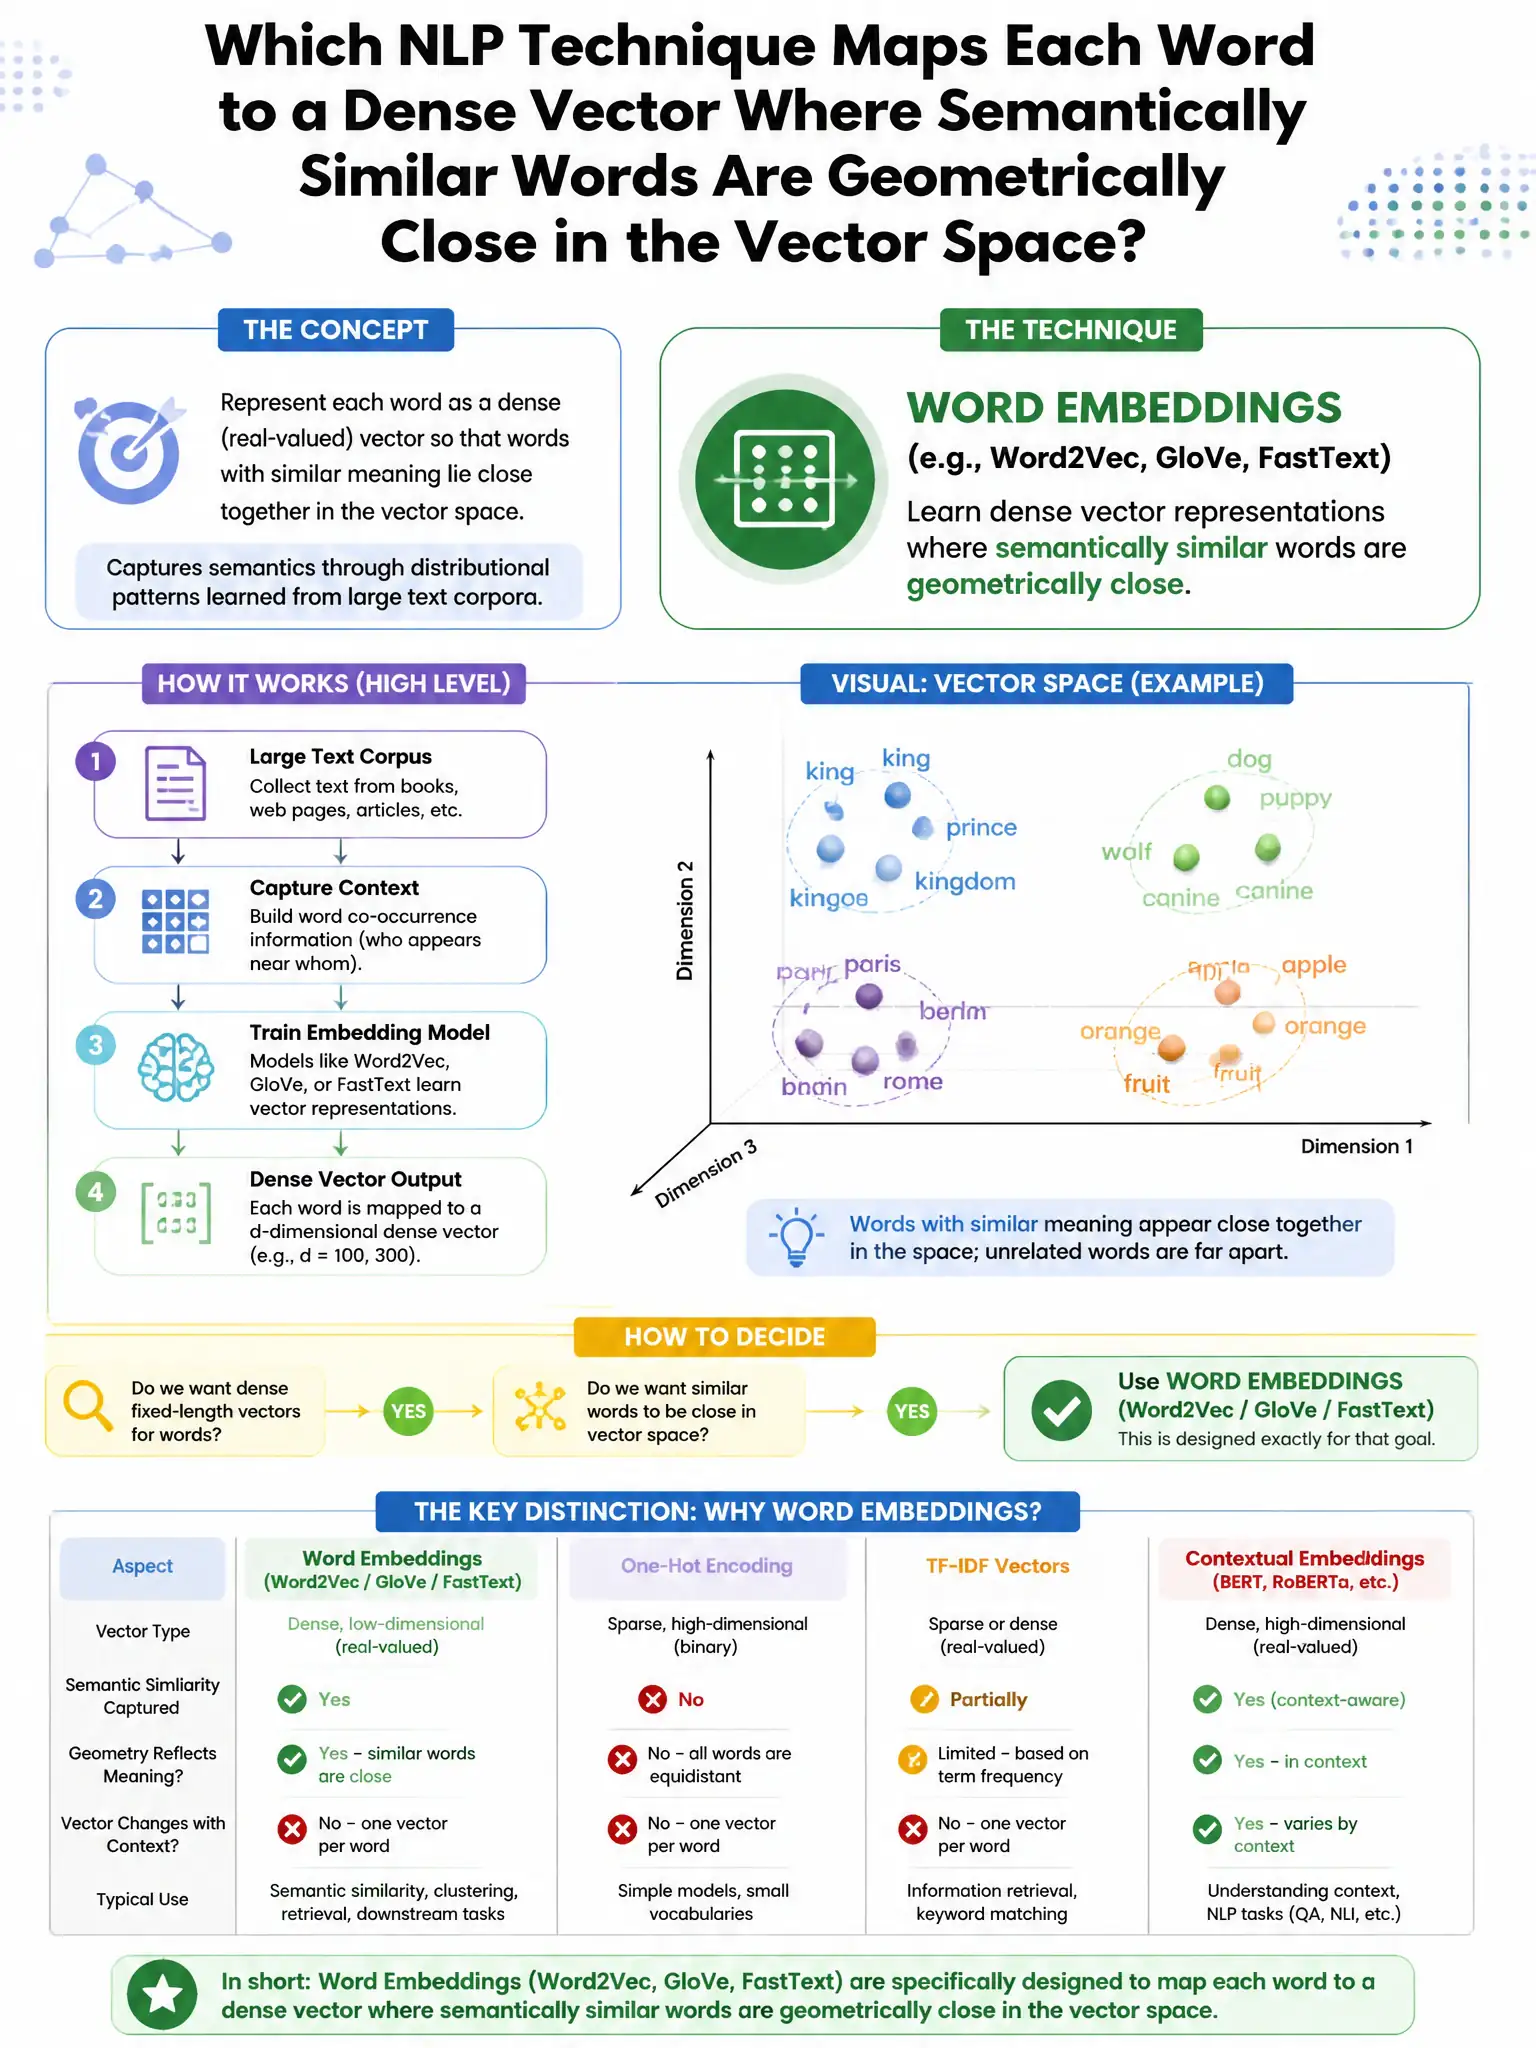
Here's the deal — word embeddings like Word2Vec and GloVe are the right choice because they learn dense, low-dimensional vectors where geometrically similar positions correspond to semantically related words. One-hot encoding is sparse and captures no semantic similarity.
Full Explanation
Word embeddings (e.g., Word2Vec, GloVe) are correct because they learn dense, low-dimensional vectors where geometrically similar positions correspond to semantically related words. One-hot encoding representing each word as a sparse binary vector is sparse and captures no semantic similarity. Bag-of-words representation counting word occurrences per document represents documents, not words, with no semantic relationships. TF-IDF weighting scaling term frequencies by inverse document frequency is a document-level term weighting scheme.