
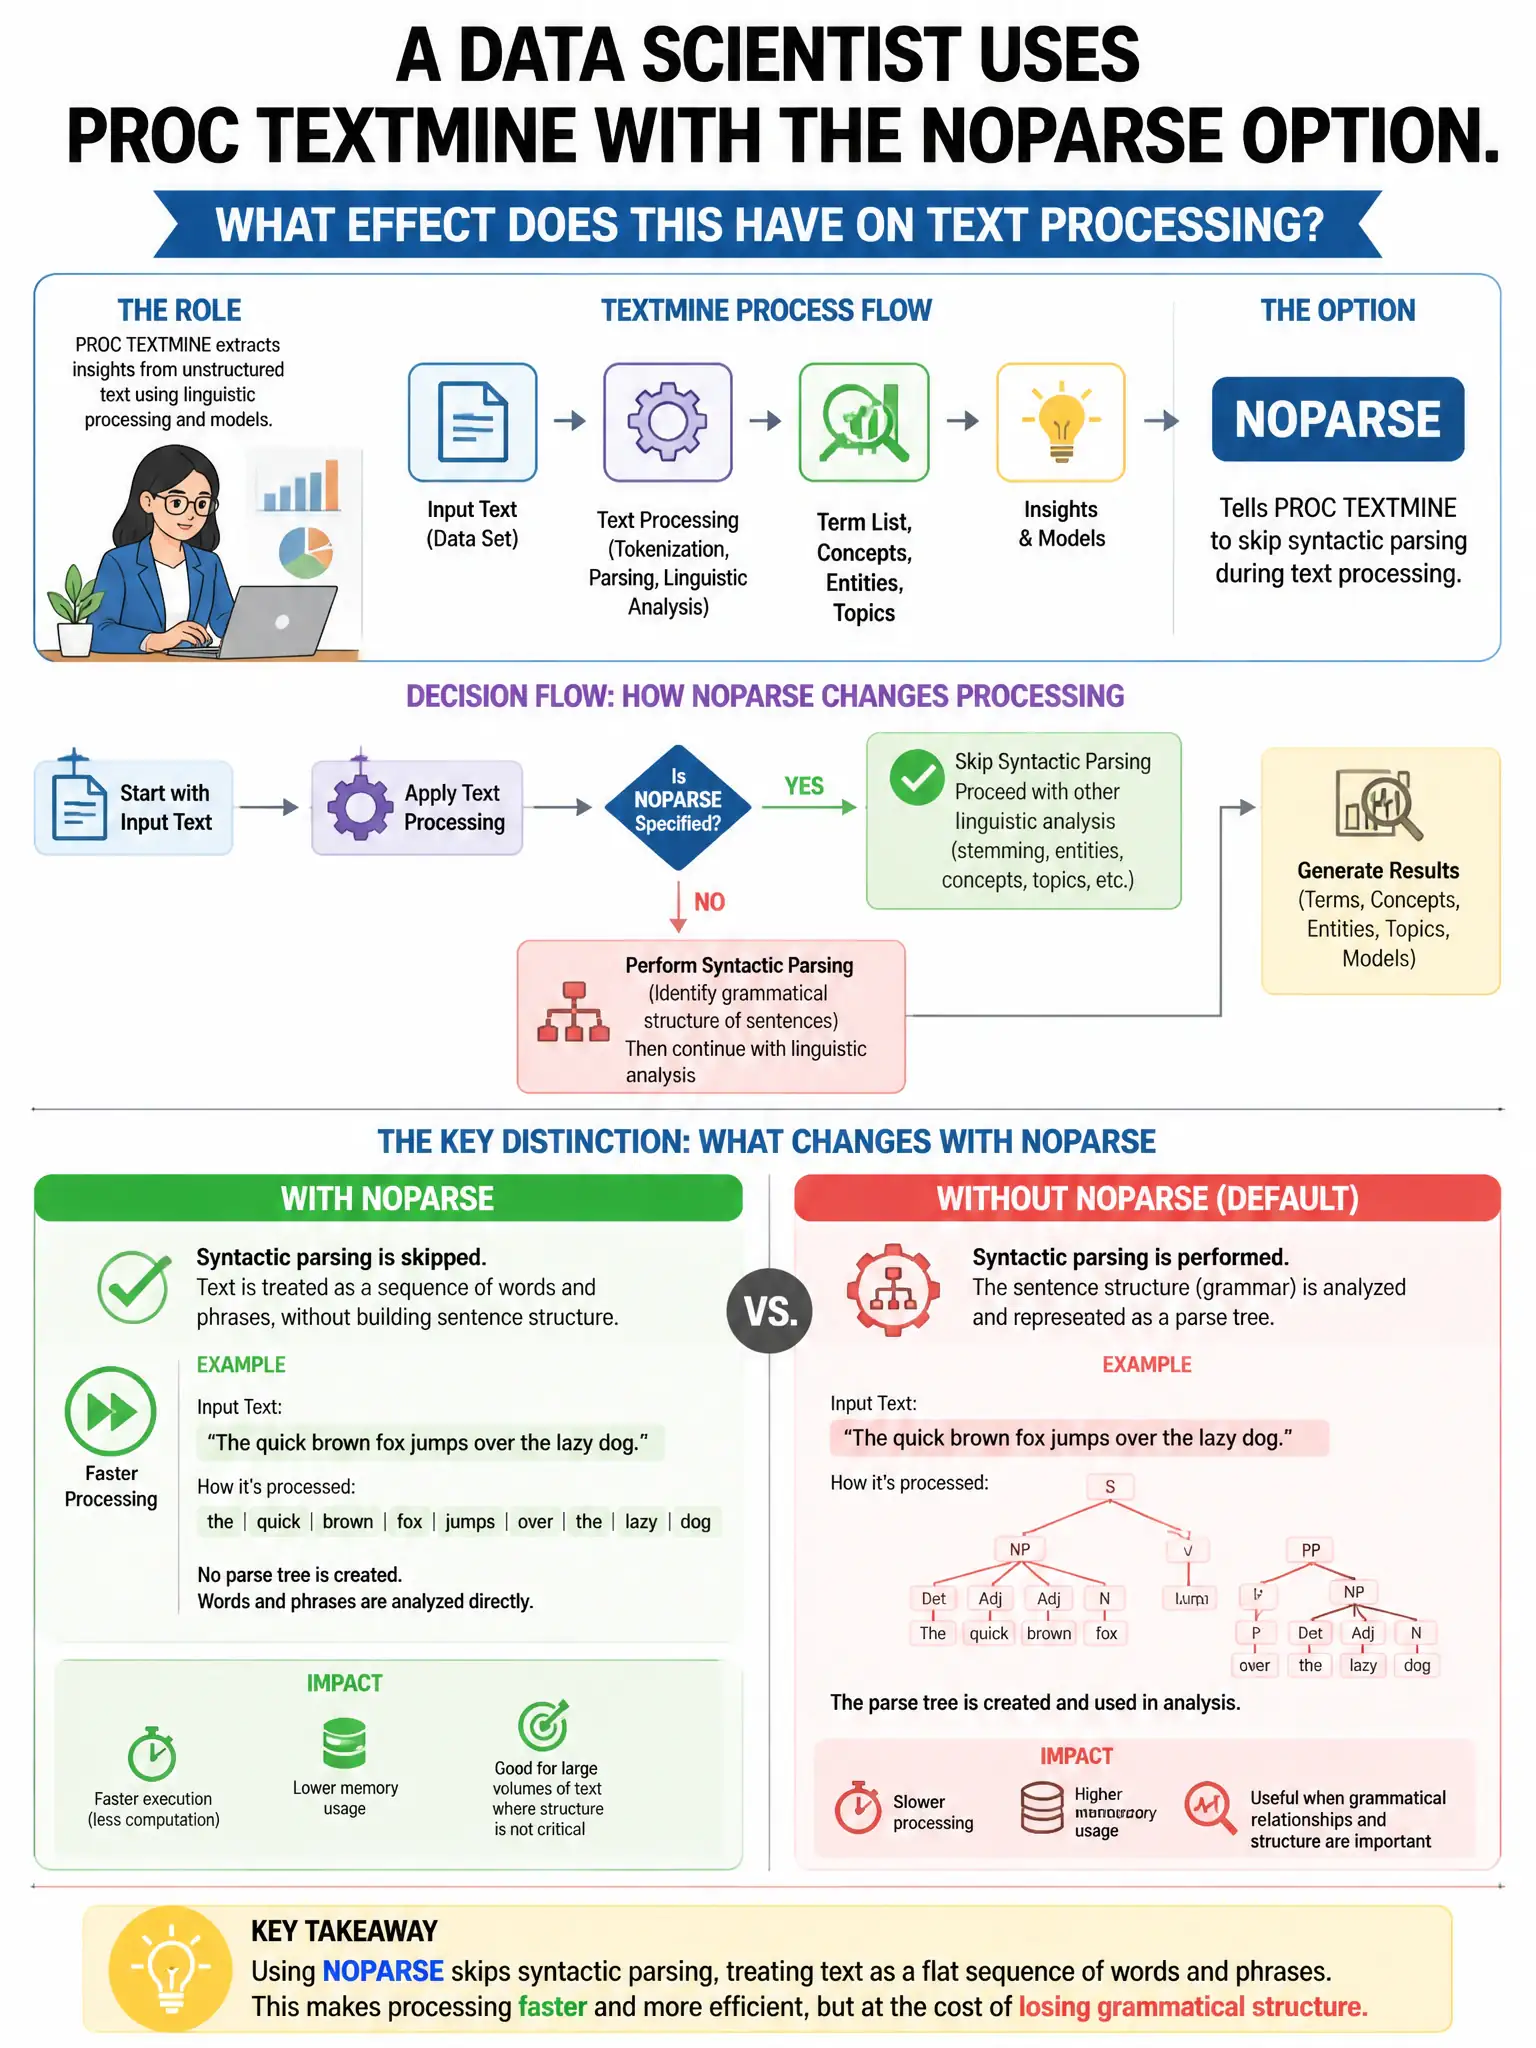
A data scientist uses PROC TEXTMINE with the NOPARSE option. What effect does this have on text processing?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — NOPARSE skips the full linguistic parsing step, like POS tagging and sentence detection, but you still get tokenization and stemming. You trade linguistic depth for faster text processing.
Full Explanation
NOPARSE skips the full linguistic parsing step, including syntactic analysis, POS tagging, and sentence detection, while still performing tokenization, term extraction, and stemming. This trades linguistic depth for processing speed. Skipping tokenization entirely is wrong because tokenization still occurs. Disabling stop word removal and stemming is wrong because those are controlled by separate options. Preventing output datasets is wrong because output datasets are still created.