
How does PROC HPFOREST handle missing values in predictor variables during training and scoring?
Select an answer to reveal the explanation.
Short Explanation
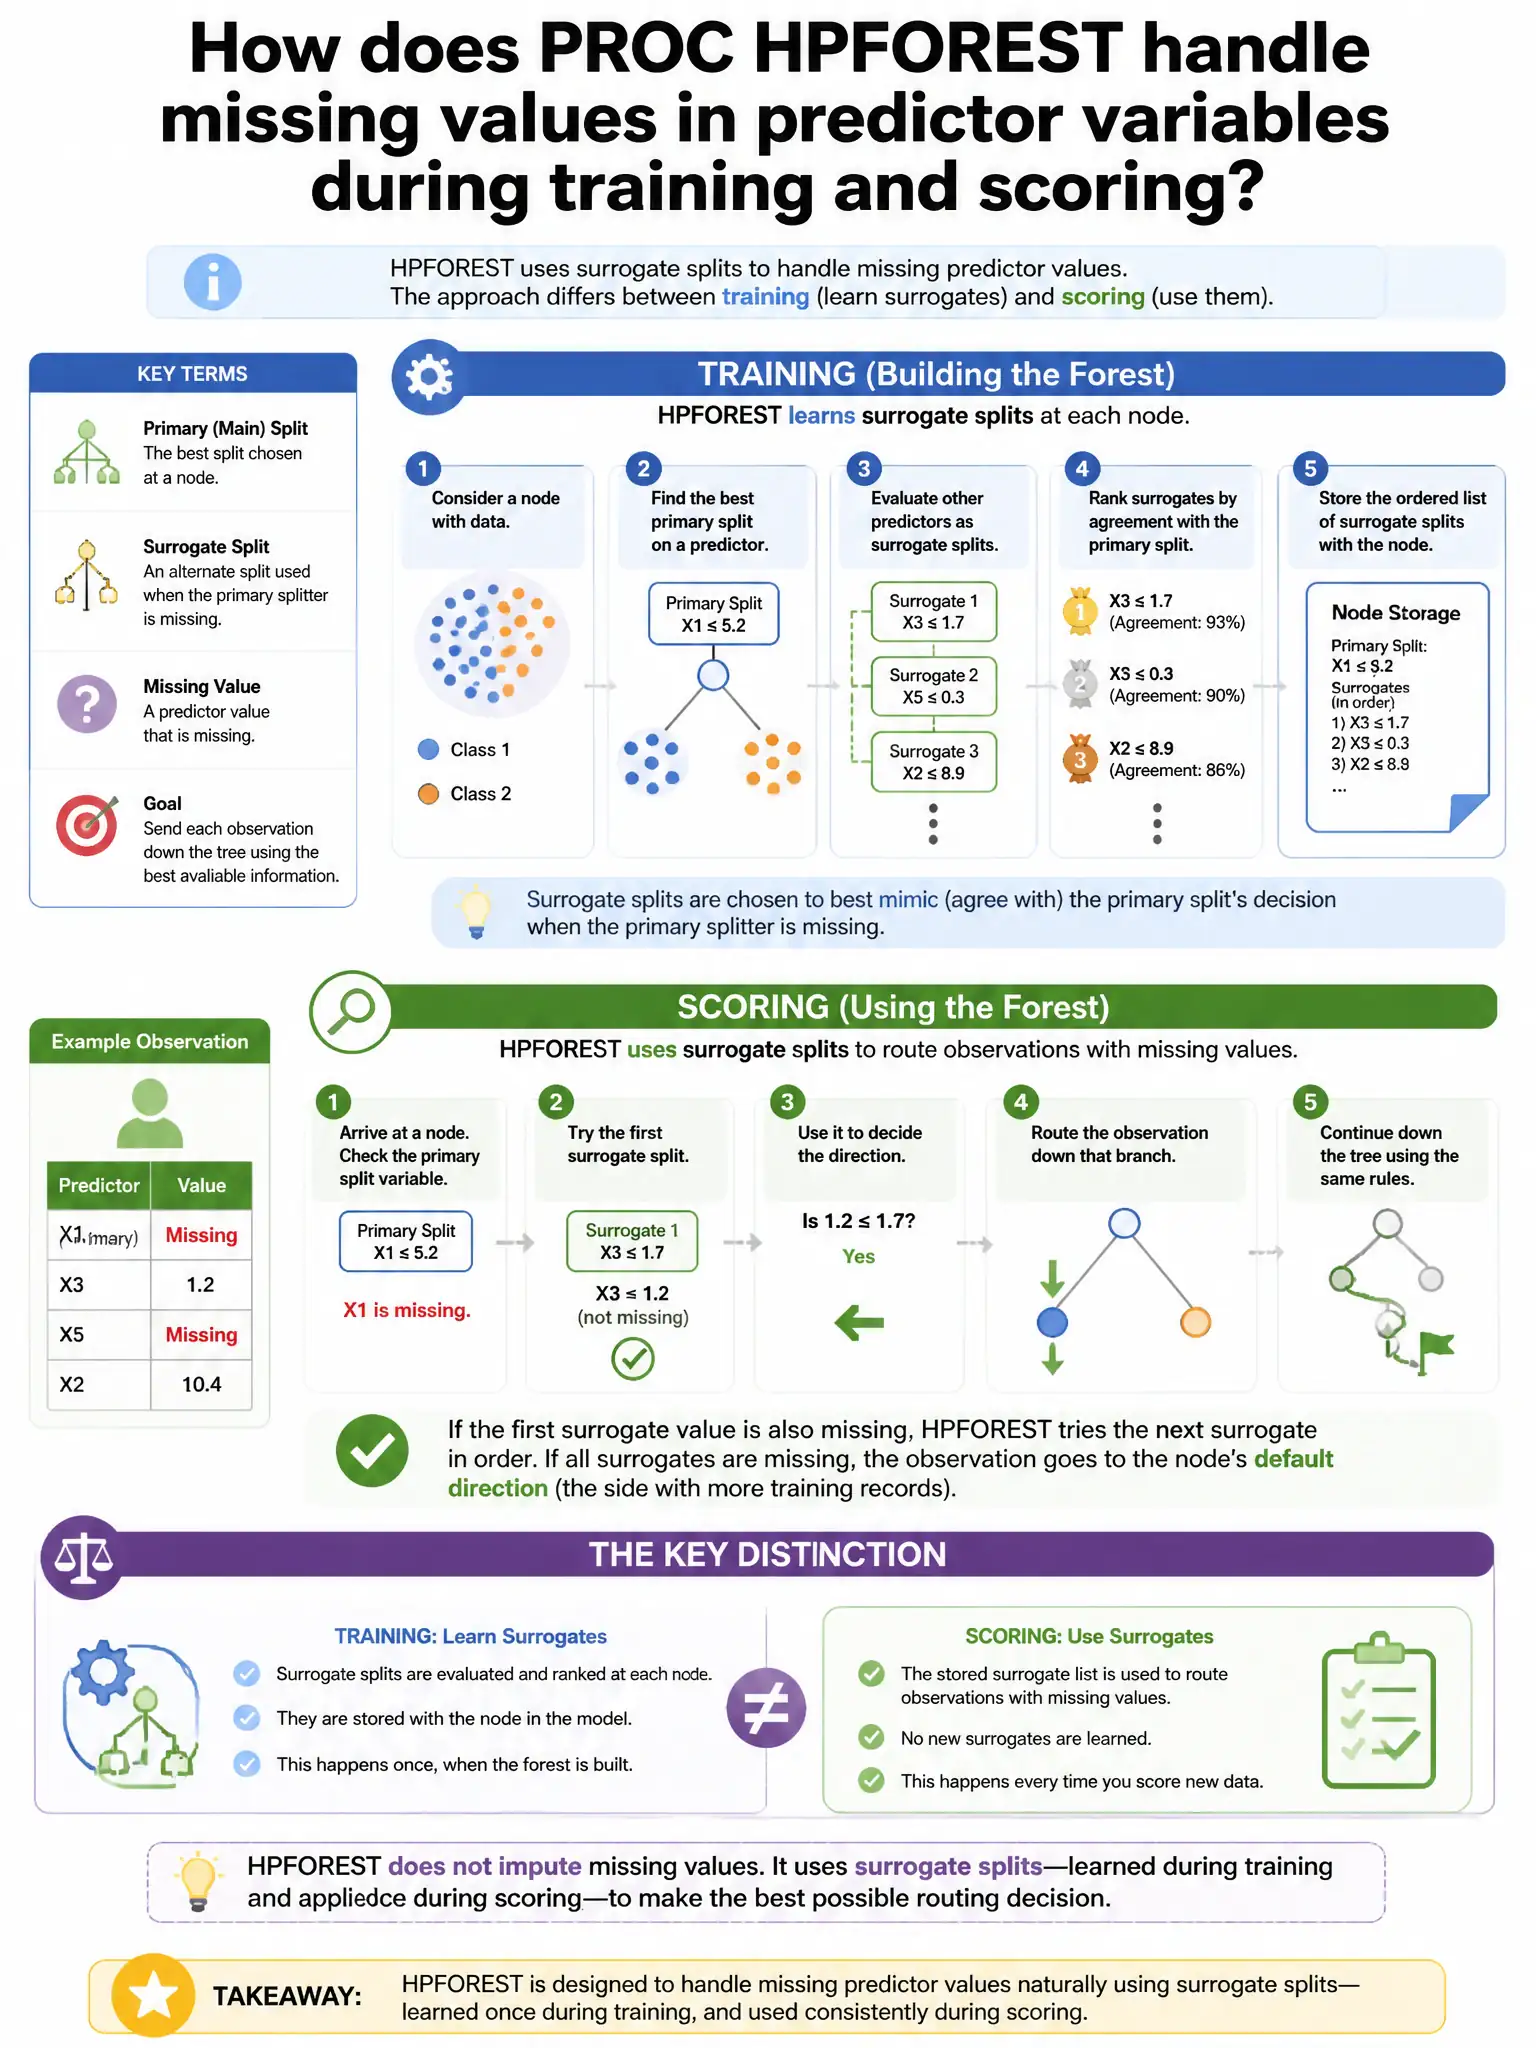
Here's the deal — PROC HPFOREST handles missing predictor values by using surrogate splits. When the primary split variable is missing, it routes the observation using the best surrogate variable, which is the one most correlated with the primary split. It does not just drop those observations.
Full Explanation
PROC HPFOREST uses surrogate splits to handle missing predictor values. When the primary split variable is missing, it routes the observation using the best surrogate variable, the predictor most correlated with the primary split. Excluding observations with any missing predictor values is wrong because missing observations are not excluded. Median imputation before tree splitting is wrong because PROC HPFOREST does not apply that strategy. Mean imputation for numeric and mode for categorical variables is wrong because PROC HPFOREST handles missing values natively via surrogate splits.