
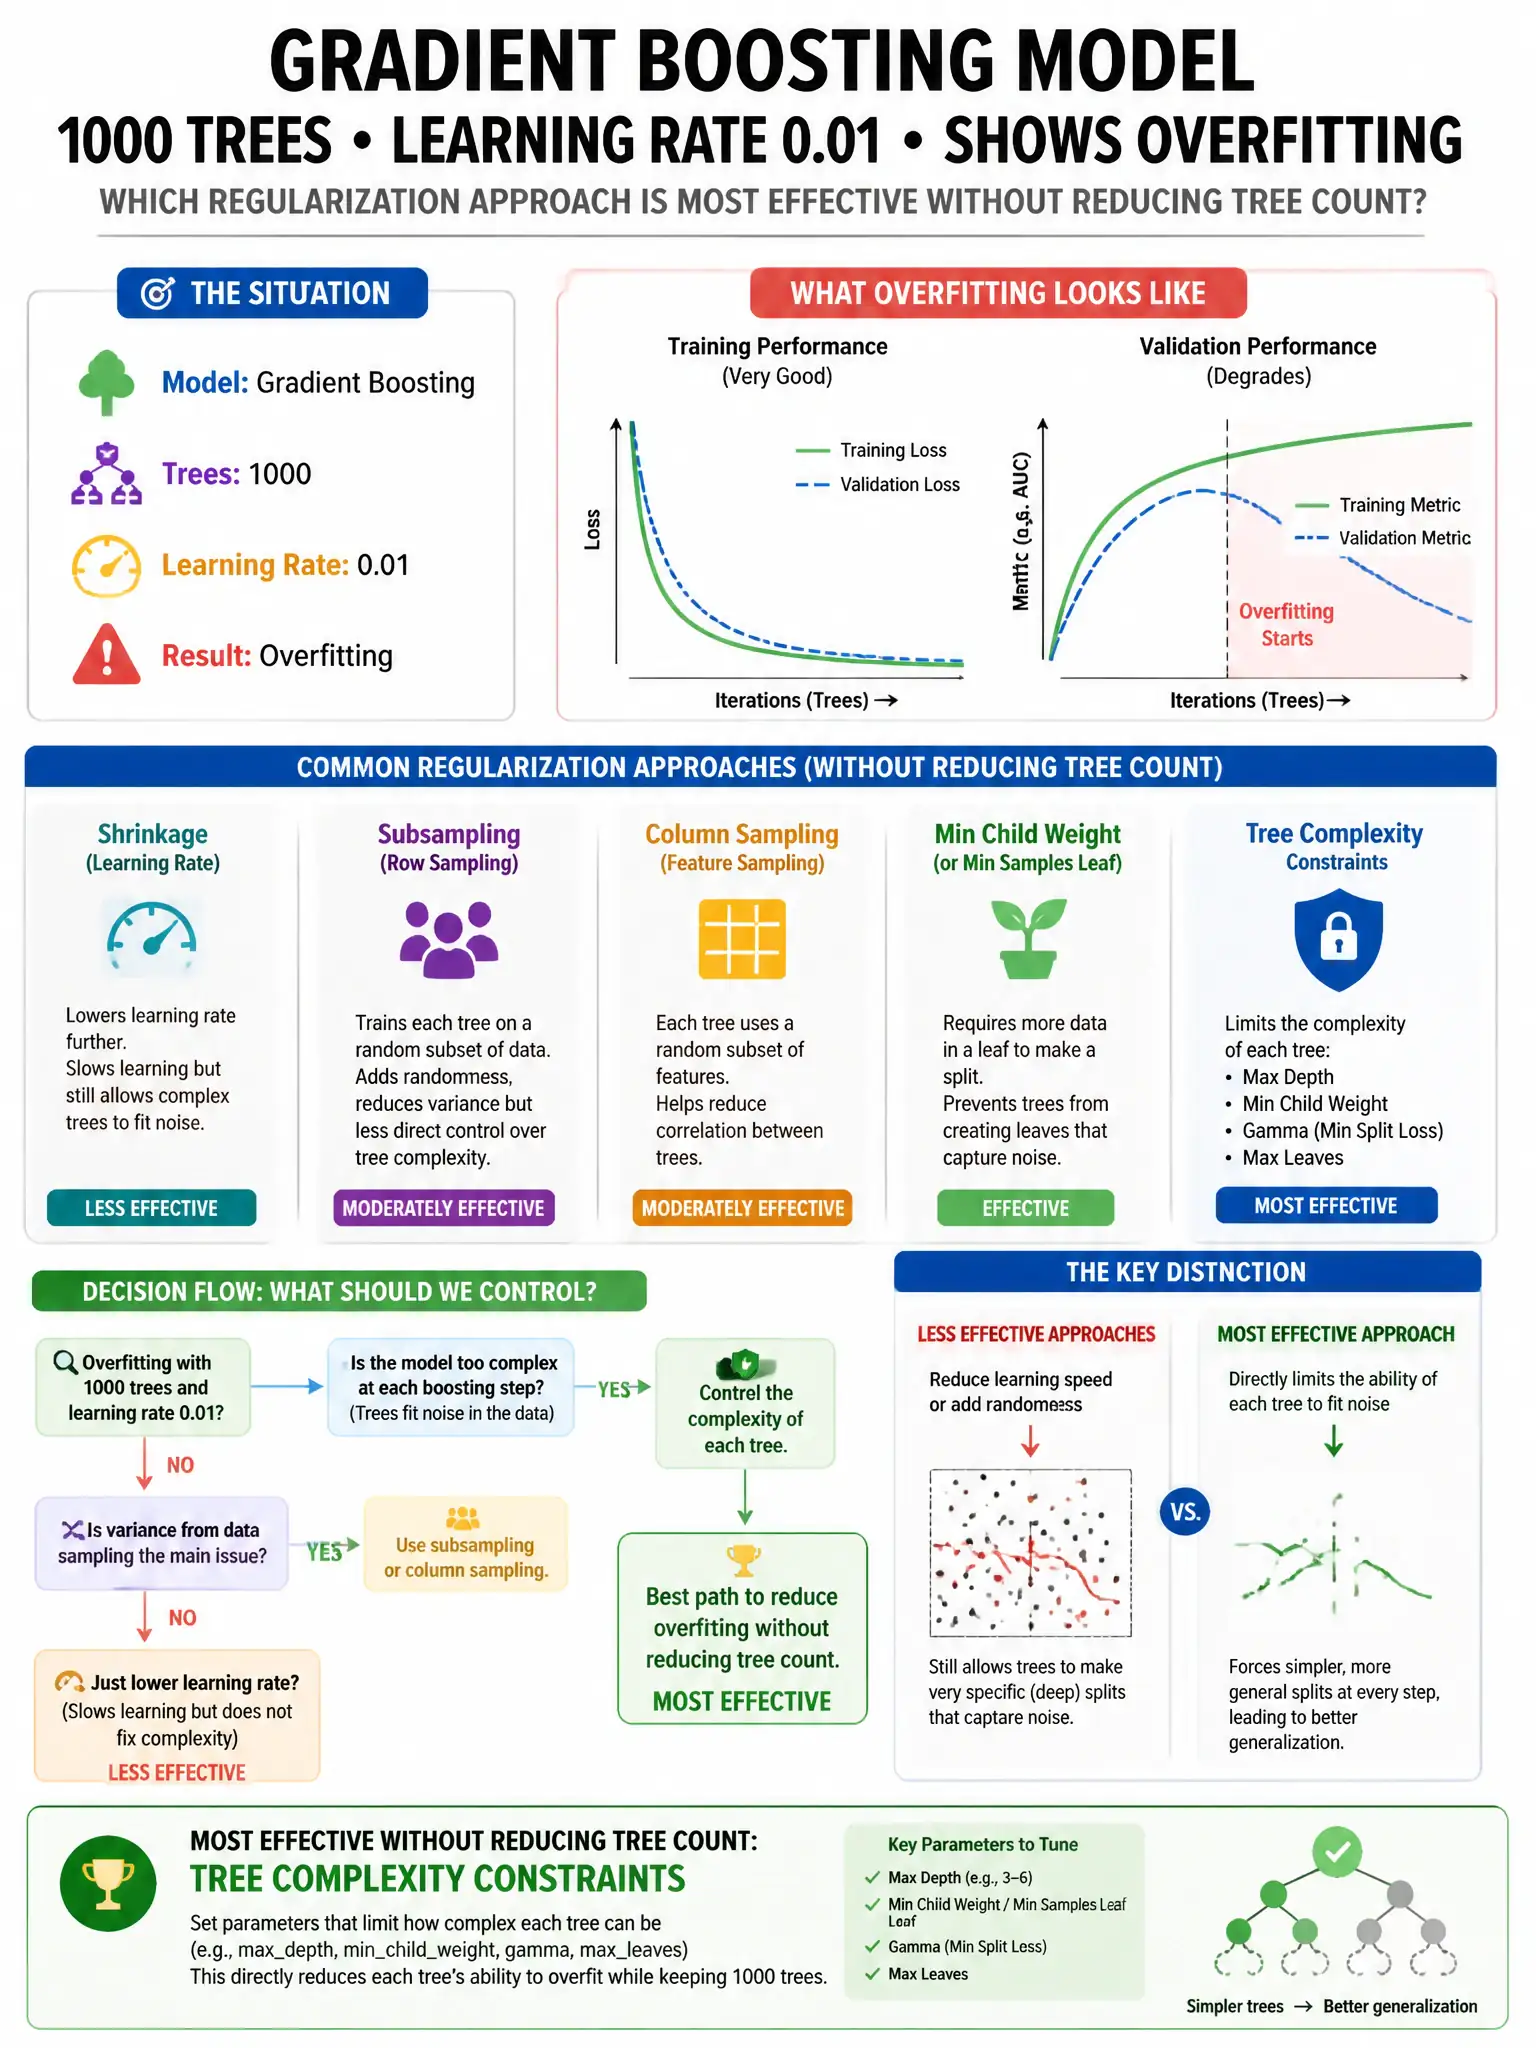
A gradient boosting model with 1000 trees and learning rate 0.01 shows overfitting. Which regularization approach is most effective without reducing tree count?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — row subsampling is the right move because it trains each tree on a random subset of observations, adding randomness that regularizes the model and cuts variance. Lowering the learning rate just slows learning and usually needs more trees to match performance.
Full Explanation
Applying row subsampling (stochastic gradient boosting) is correct because it introduces randomness by training each tree on a random subset of observations, which acts as regularization and reduces variance without reducing the number of trees. Decreasing the learning rate further to 0.001 slows learning but requires more trees for equal performance. Increasing maximum tree depth to allow more complex splits increases model complexity and worsens overfitting. Increasing trees to 2000 while keeping the learning rate the same can increase overfitting.