
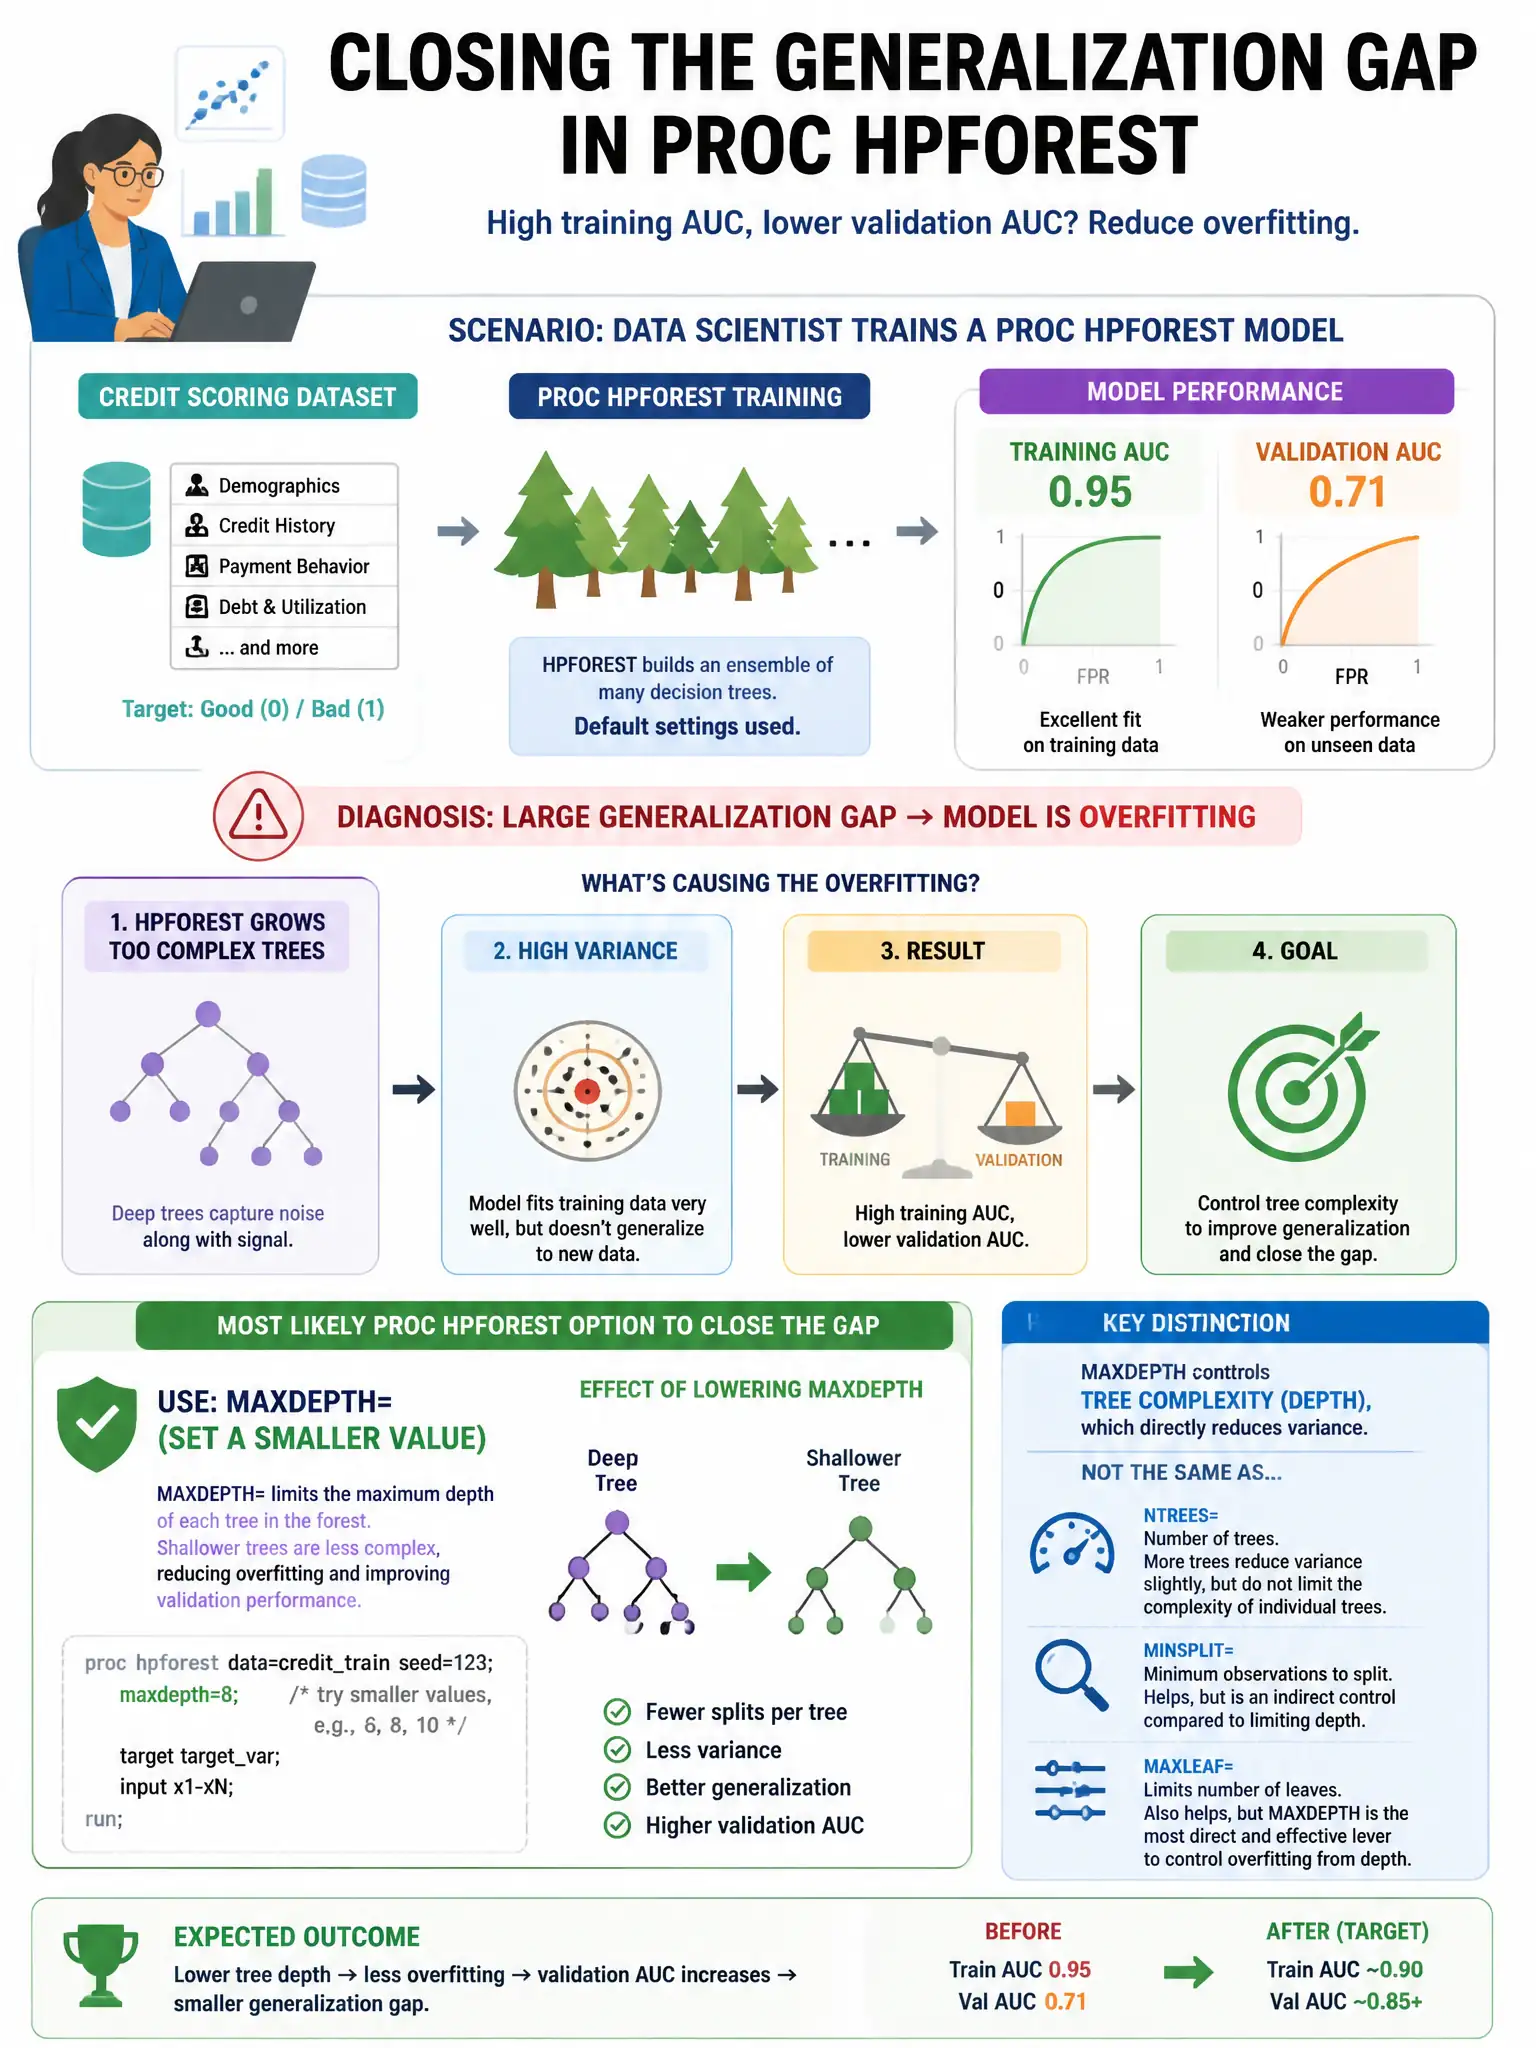
A data scientist trains a PROC HPFOREST model on a credit scoring dataset. The training AUC is 0.95 but validation AUC is 0.71. Which PROC HPFOREST option is most likely to close this gap without changing the dataset?
Select an answer to reveal the explanation.
Short Explanation
You're seeing overfitting, so you need to make each tree simpler. Decrease MAXDEPTH= to stop trees from growing too deep, and increase LEAFSIZE= to force each leaf to cover more observations. That smooths predictions and helps close the training-to-validation AUC gap.
Full Explanation
The 24-point AUC gap between training and validation indicates overfitting. Decreasing MAXDEPTH= limits how deep each tree can grow, reducing individual tree complexity, and increasing LEAFSIZE= requires a minimum number of observations per leaf, smoothing predictions. Both settings constrain individual tree complexity without changing the data. Increasing NTREES= to add more trees reduces variance, but the primary issue here is tree depth, not ensemble size. Increasing VARS_TO_TRY= to use more features at each split increases correlation between trees and reduces diversity, potentially worsening overfitting. Setting SEED= to a different value to get a different random initialization produces a different but equally overfit model.