
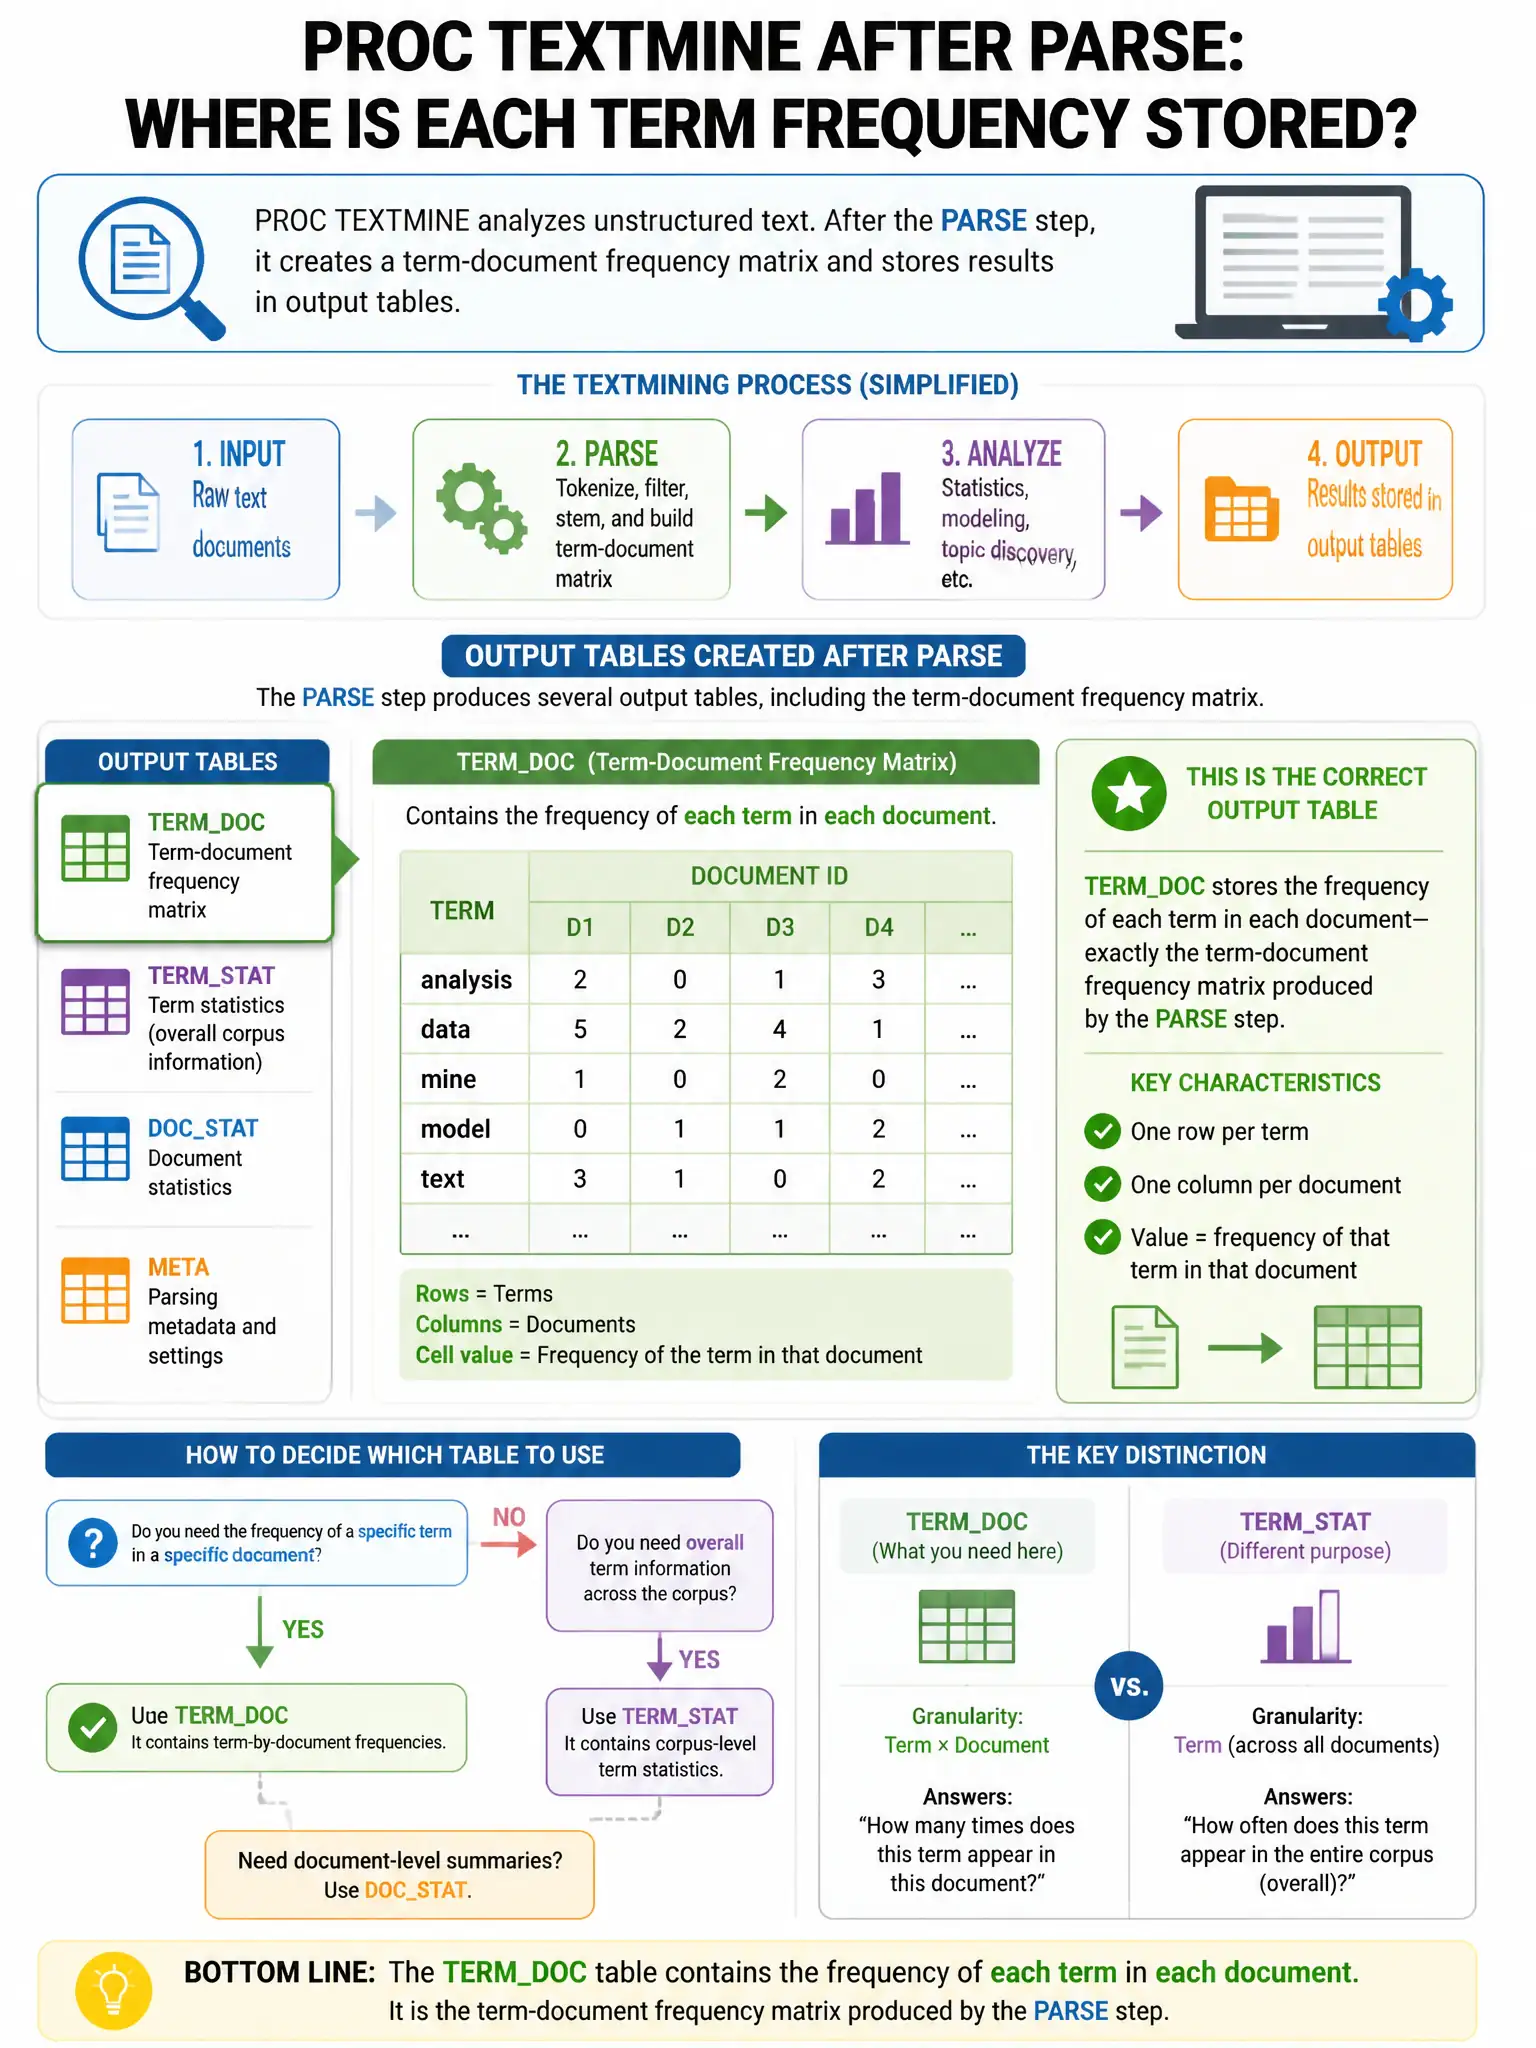
In PROC TEXTMINE, after running the PARSE step, the resulting term-document frequency matrix is stored in output tables. Which output table contains the frequency of each term in each document?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — the term-document frequency matrix lives in the OUTTERMS= dataset from the PARSE statement, because that table stores the term-document co-occurrences you need. The OUT= dataset from the PROC TEXTMINE statement is for document-level scores and metadata, not the term-by-document frequencies.
Full Explanation
The correct answer is the OUTTERMS= dataset from the PARSE statement, because that option produces a dataset containing term-document associations — specifically the frequency or weight of each term within each document, forming the sparse term-document matrix. The OUT= dataset from the PROC TEXTMINE statement is wrong because it contains document-level scores and metadata rather than term-by-document frequencies. The OUTUNIGRAMSTAT= dataset specified in the PARSE statement is wrong because it contains term-level statistics such as document frequency and total count, not the full term-document matrix. The OUTEIGEN= dataset from the SVDINIT statement is wrong because it contains SVD eigenvectors after dimensionality reduction, not the parsed term-document frequency data.