
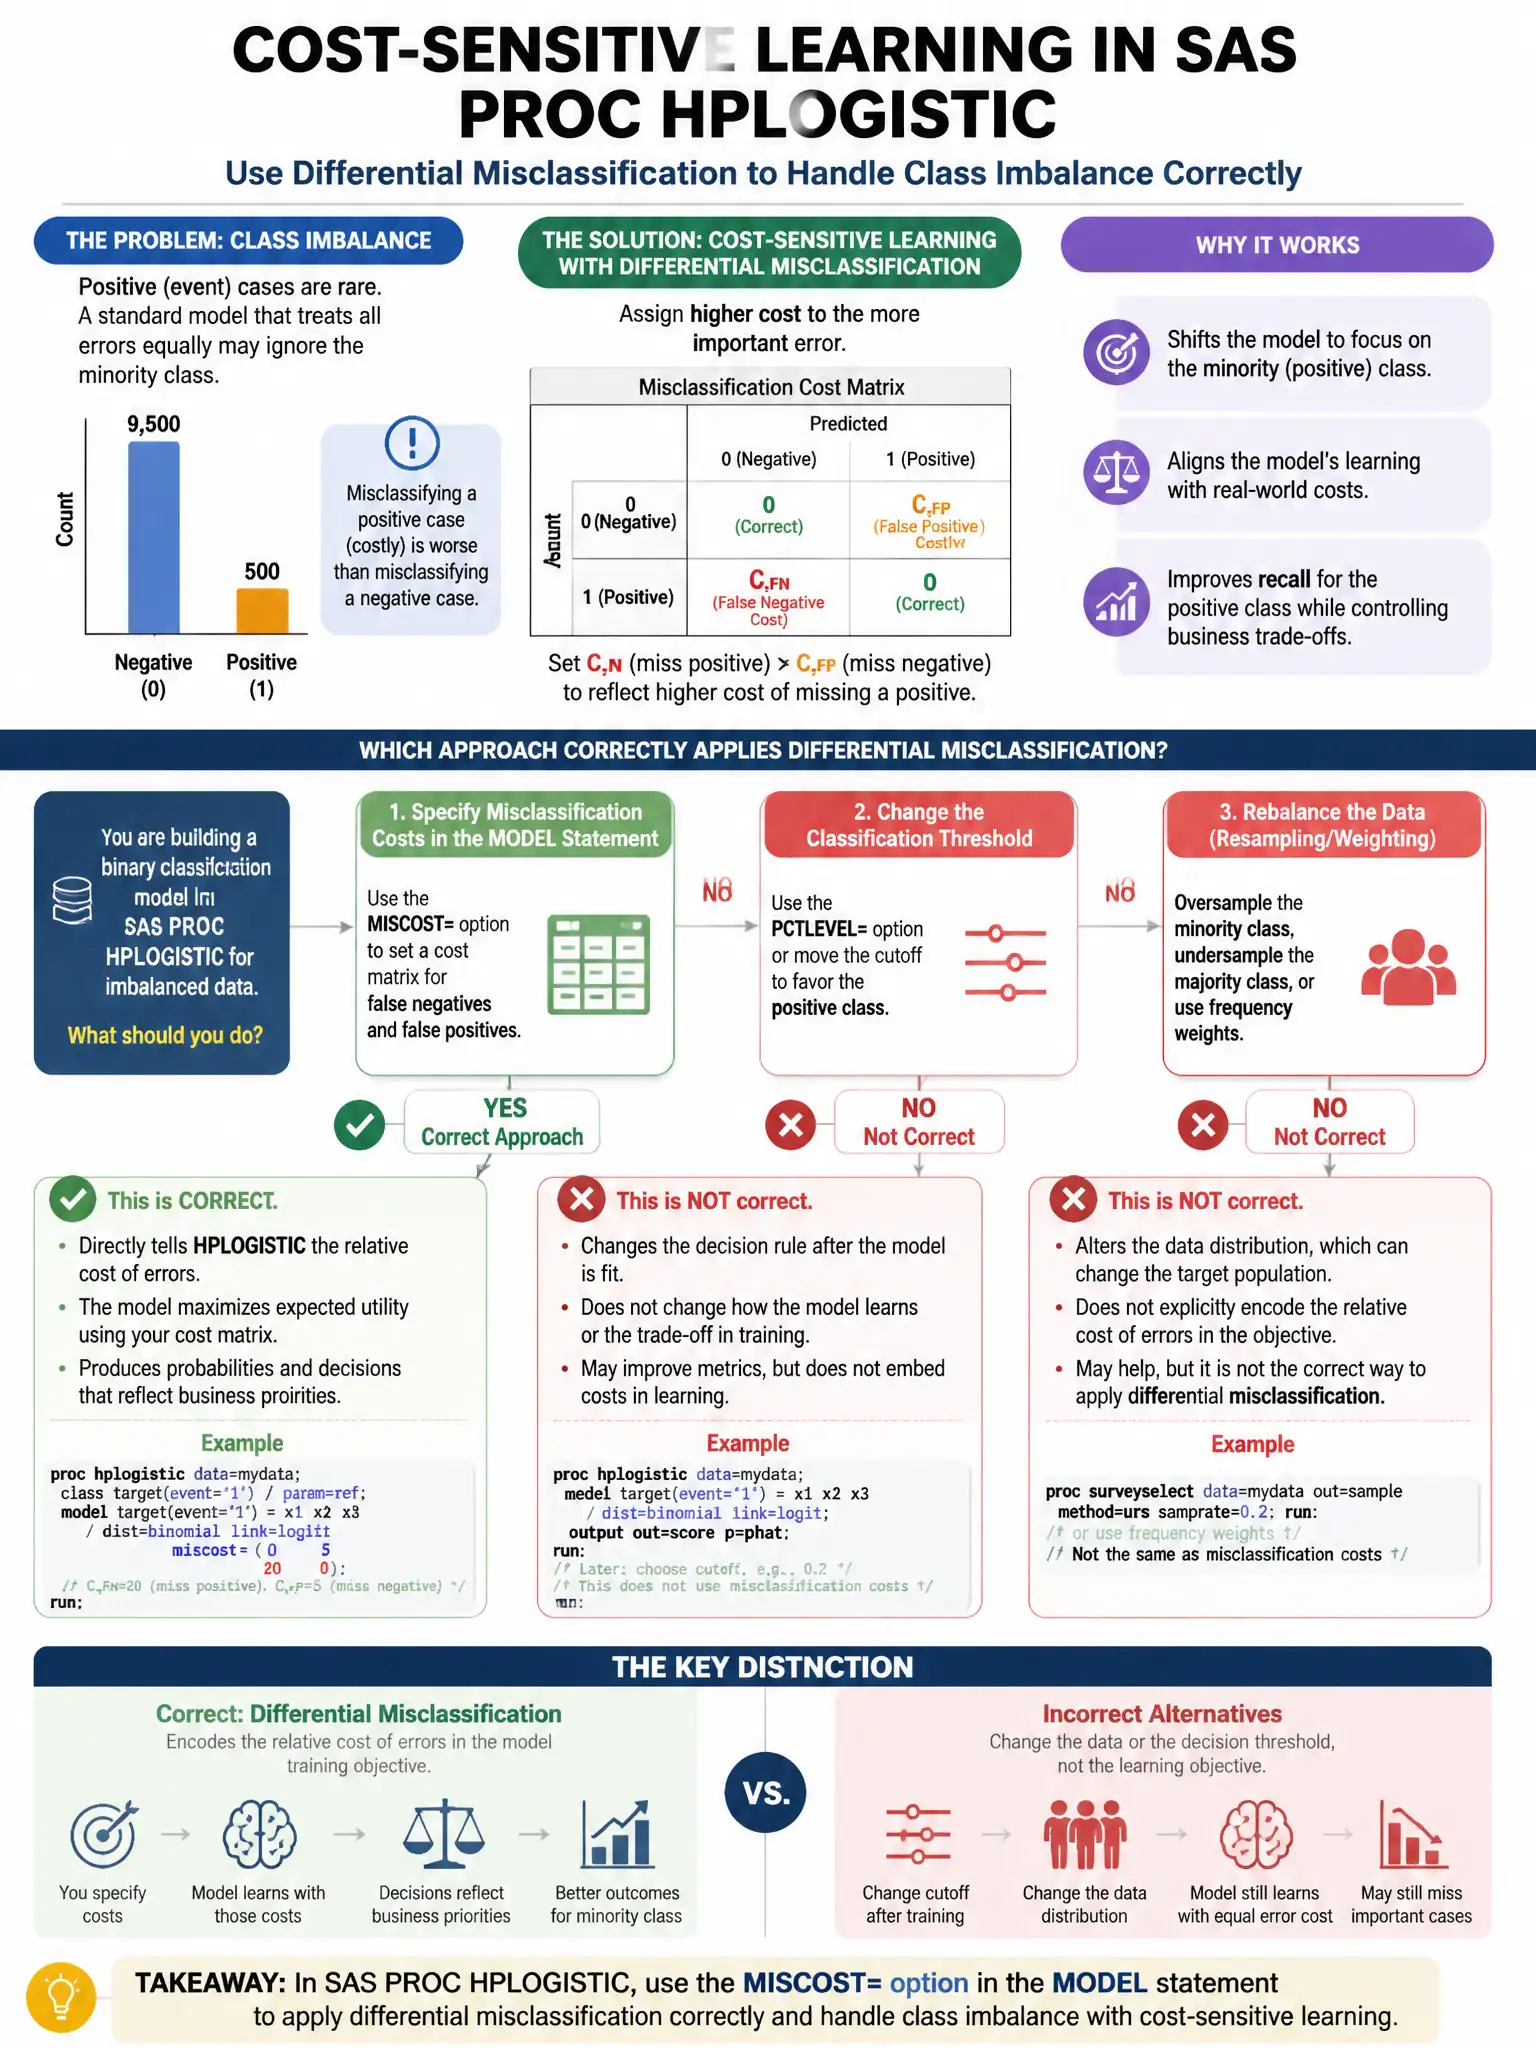
In SAS, a data scientist wants to use cost-sensitive learning to handle a class imbalance problem in PROC HPLOGISTIC. Which approach correctly applies differential misclassification costs?
Select an answer to reveal the explanation.
Short Explanation
You use the WEIGHT= statement with observation weights inversely proportional to class frequency. That upweights minority-class observations, so PROC HPLOGISTIC penalizes their misclassification more heavily. It's the supported way to apply cost-sensitive learning here.
Full Explanation
The correct approach is to use the WEIGHT= statement with observation weights inversely proportional to class frequency. PROC HPLOGISTIC supports observation-level weights, so assigning higher weights to minority-class observations, such as weight = 1/class_proportion, upweights the loss for misclassifying them and implements cost-sensitive learning. The COST= option in the MODEL statement is wrong because PROC HPLOGISTIC has no such option. The CLASS statement with BALANCE= for automatic resampling is wrong because PROC HPLOGISTIC has no BALANCE= option. The PRIOR= option is wrong because it adjusts posterior probability thresholds, not misclassification costs.