
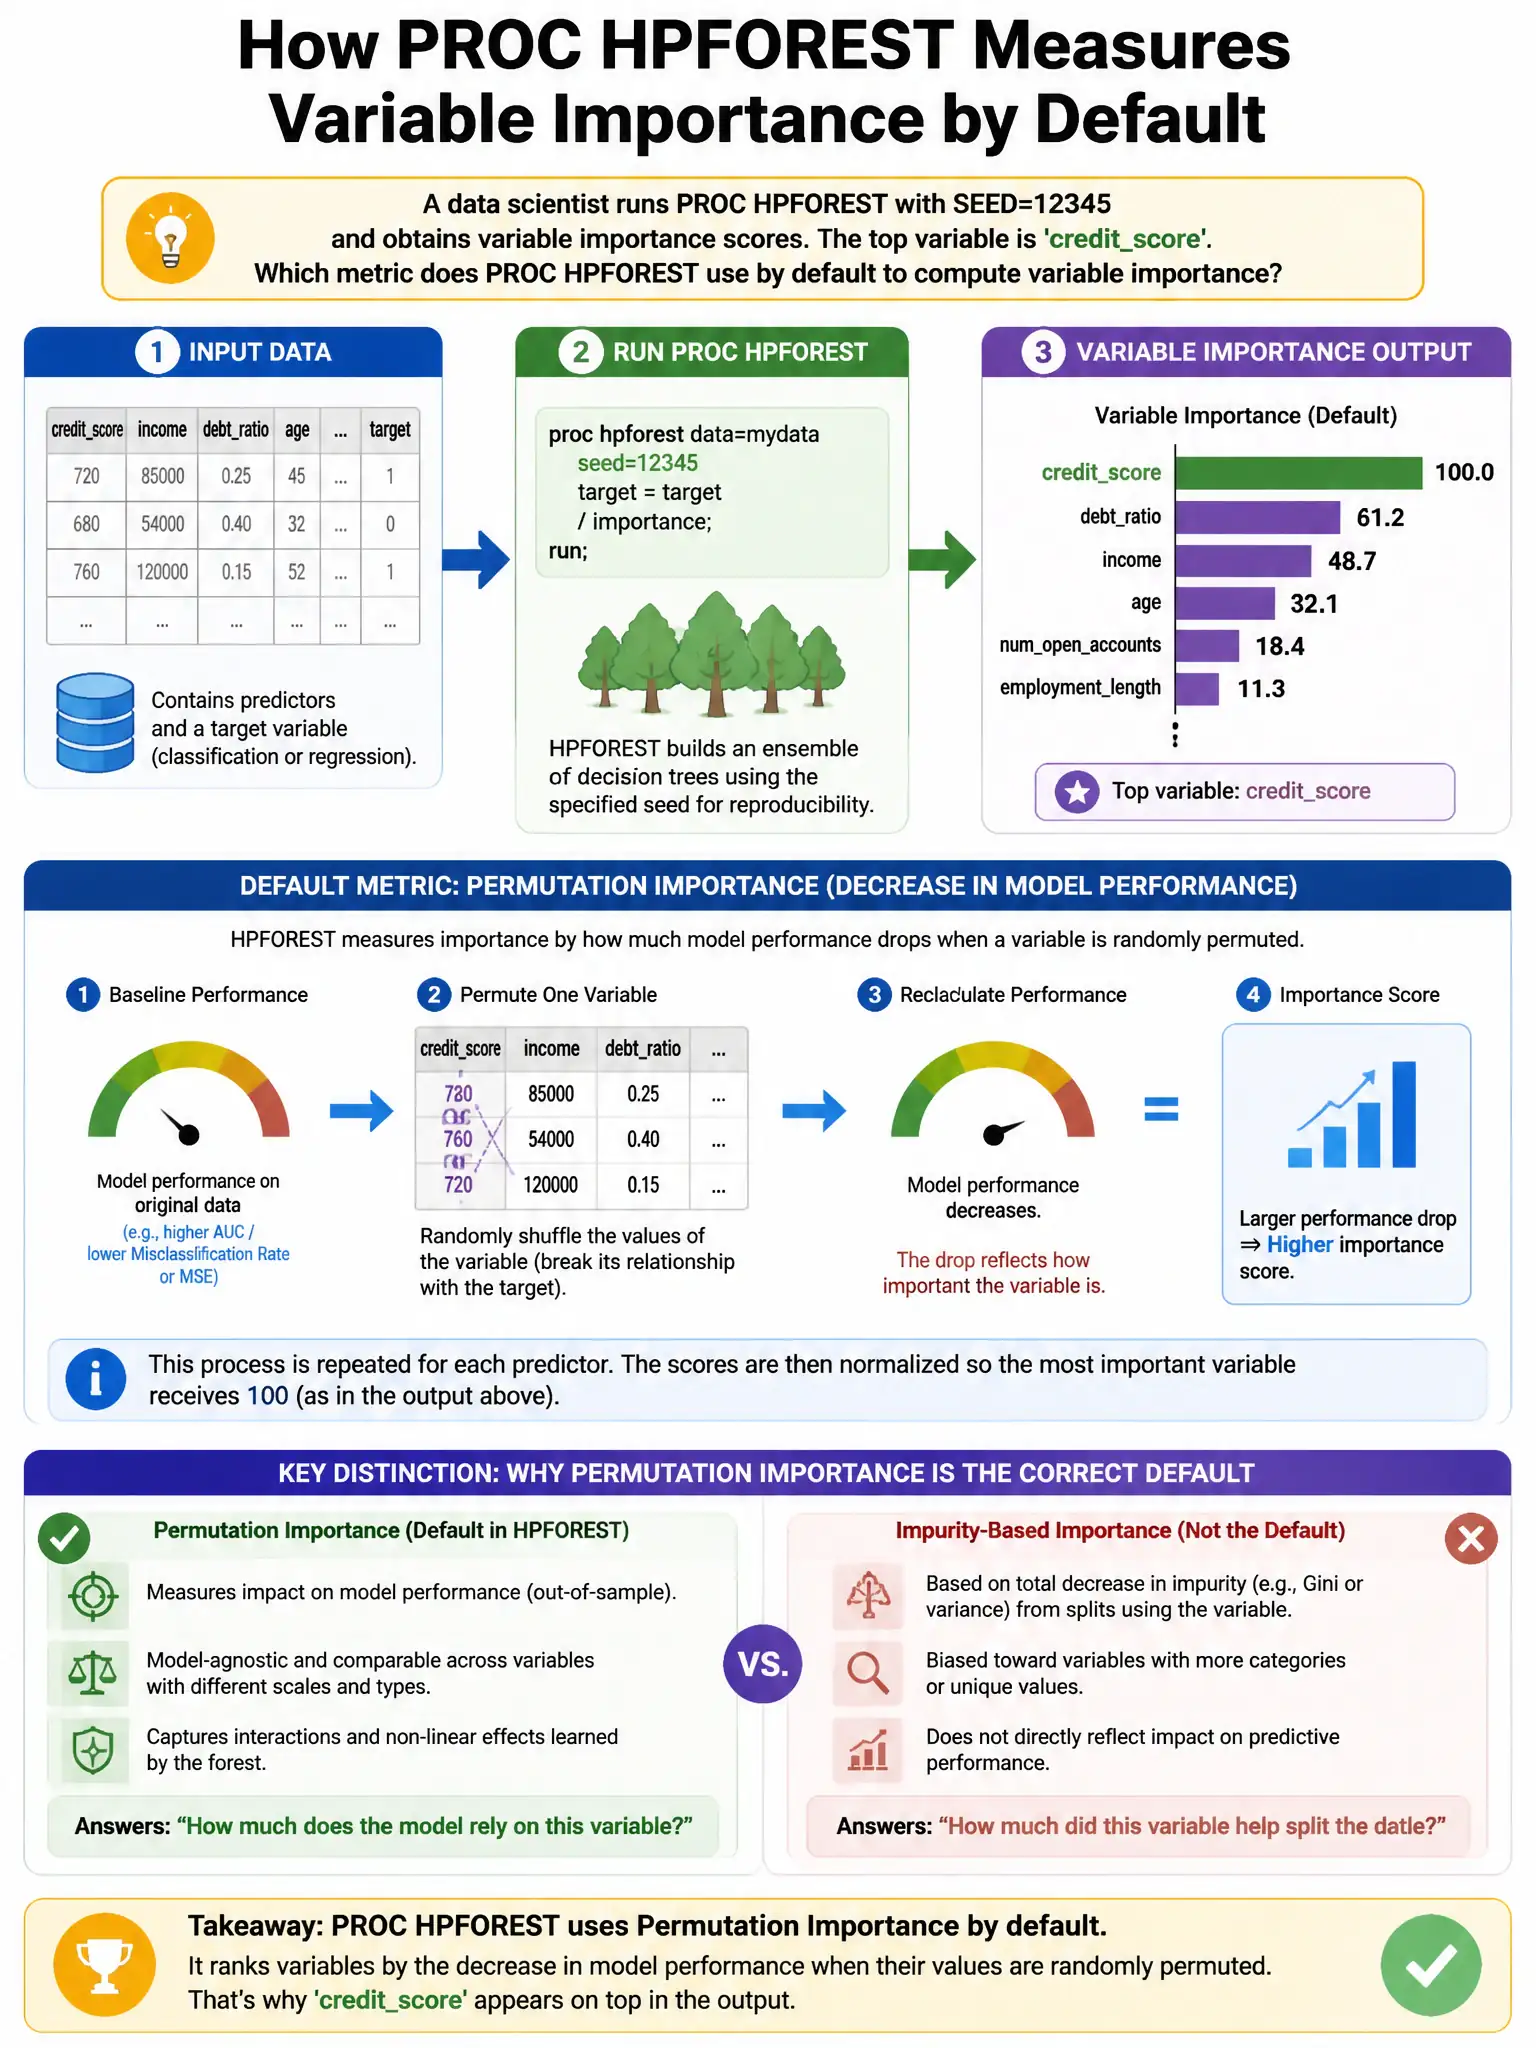
A data scientist runs PROC HPFOREST with SEED=12345 and obtains variable importance scores. The top variable is 'credit_score'. Which metric does PROC HPFOREST use by default to compute variable importance?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — PROC HPFOREST ranks variables by the average decrease in the splitting criterion, like Gini impurity for classification, across all trees. That's why the Gini impurity decrease averaged across all trees is the right metric. Permutation importance, Pearson correlation, and LASSO coefficients aren't the default HPFOREST importance measure.
Full Explanation
PROC HPFOREST computes variable importance as the average total decrease in the splitting criterion (Gini impurity for classification or variance reduction for regression) attributable to each variable across all trees. Therefore, the Gini impurity decrease averaged across all trees is the correct default metric. The mean decrease in accuracy (permutation importance) across all trees is not the default in PROC HPFOREST, though it is computed by some implementations such as scikit-learn. The Pearson correlation with the target variable is a bivariate statistic, not a tree-based importance measure. The coefficient magnitude from an embedded LASSO within each tree is wrong because PROC HPFOREST does not embed LASSO.