
Which cross-validation strategy is most appropriate when the dataset contains a strong time dependency, such as stock price data?
Select an answer to reveal the explanation.
Short Explanation
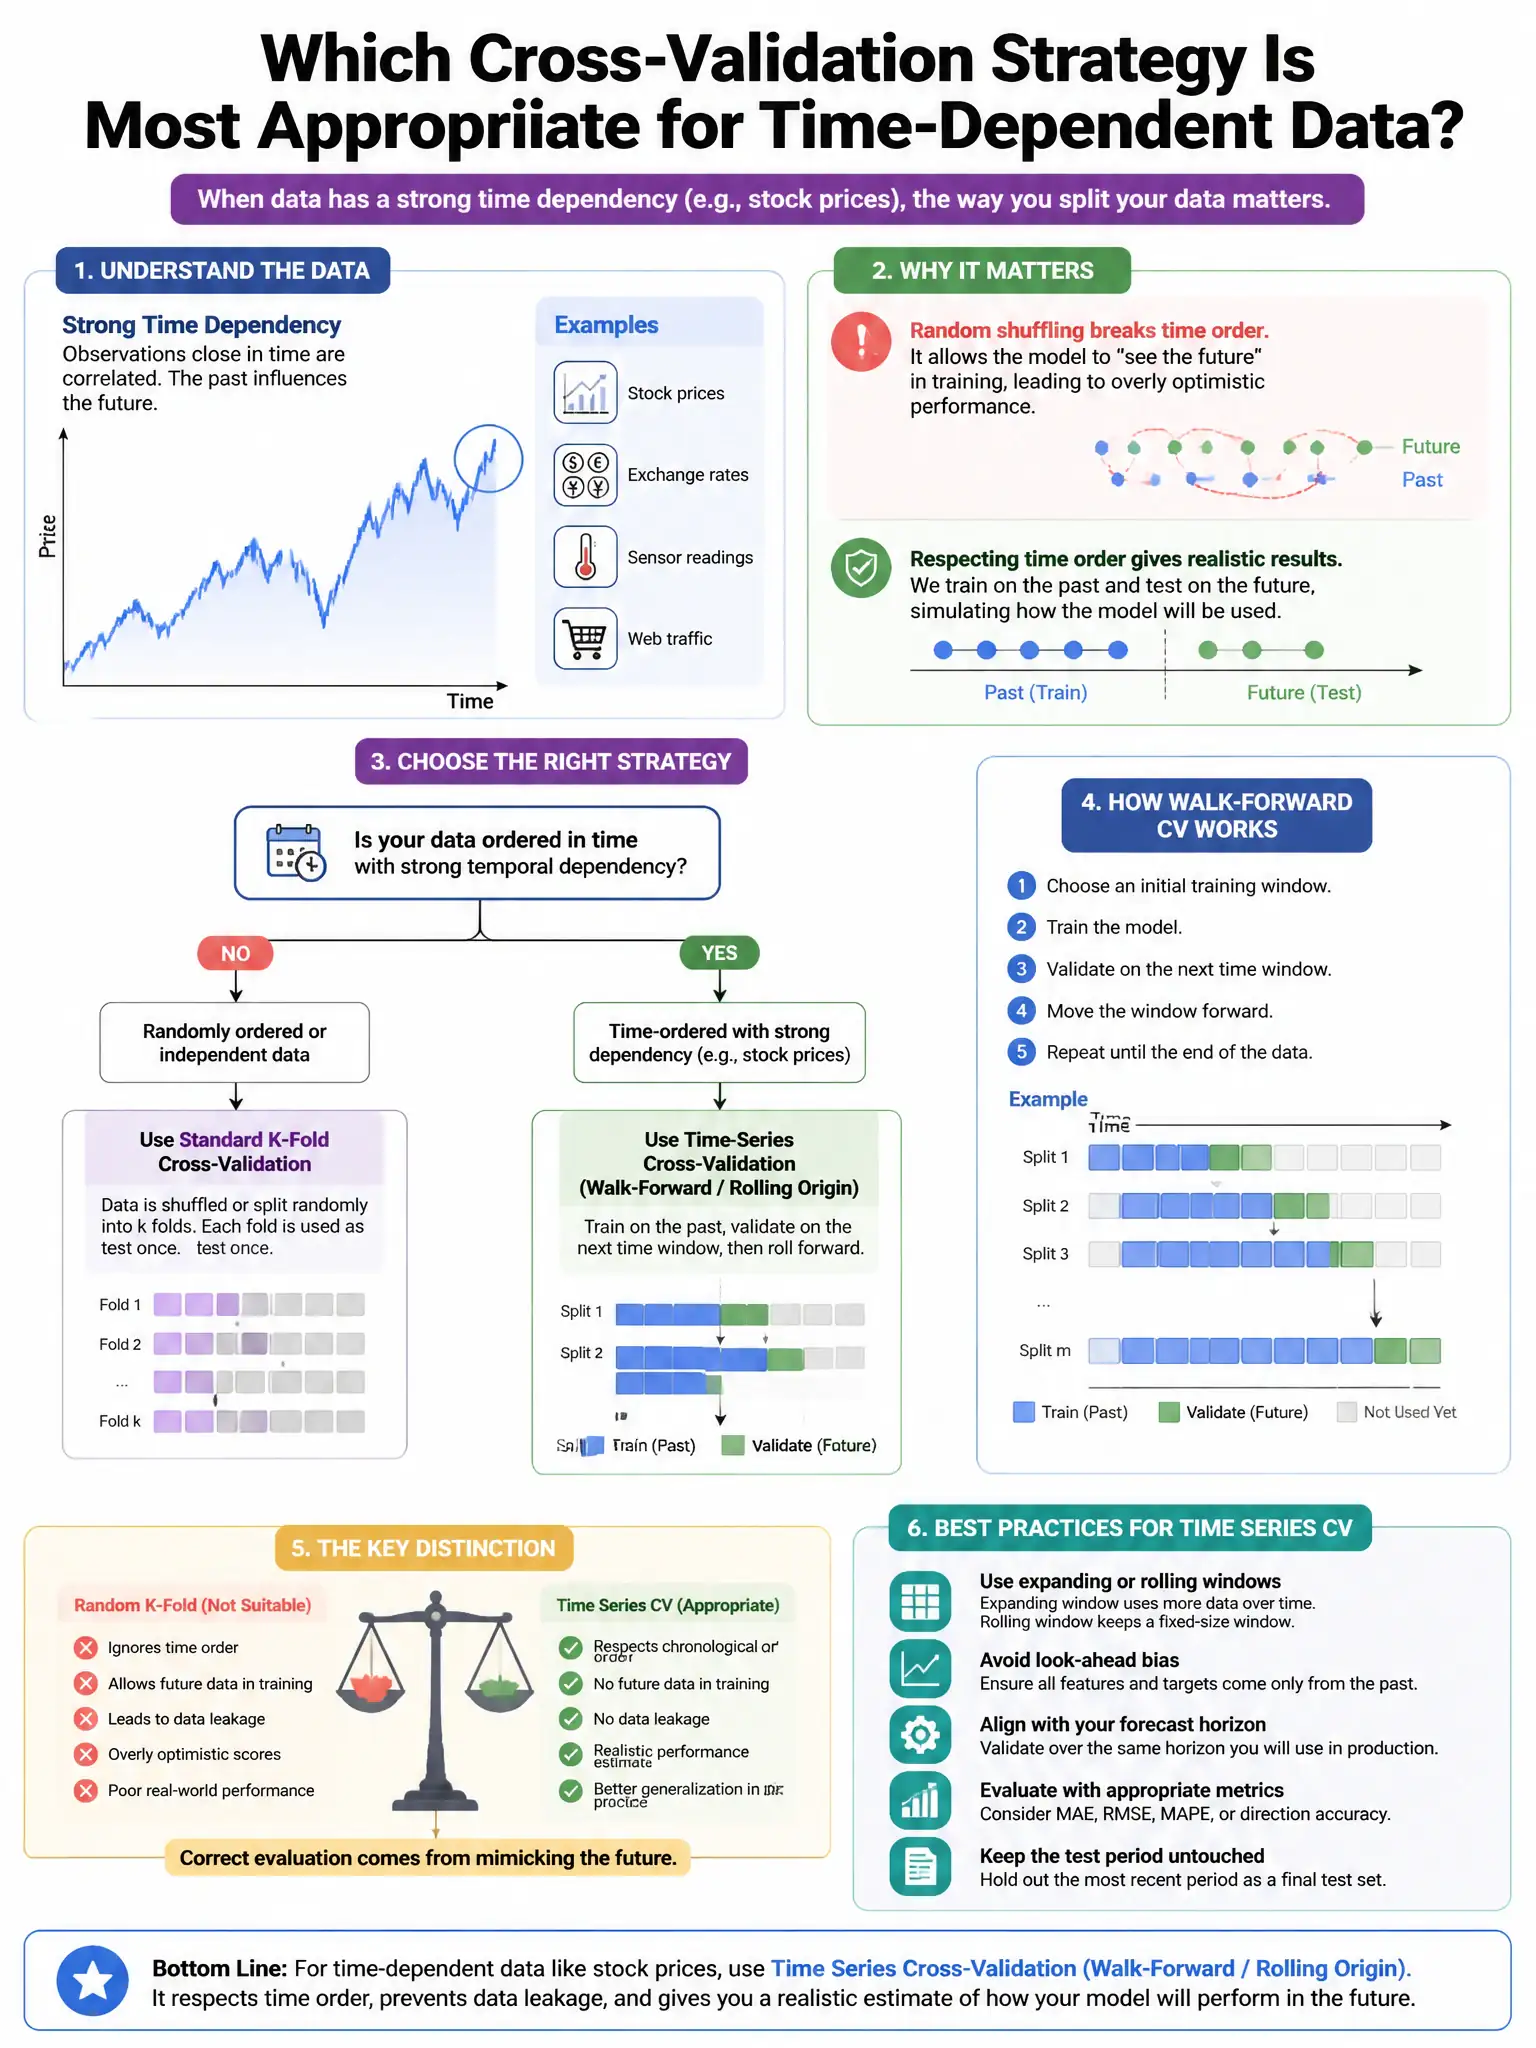
Here's the deal — when your data has a strong time dependency, you need time-series walk-forward (rolling window) cross-validation because the training window always precedes the validation window. That keeps future data from leaking into your training set.
Full Explanation
Time-series walk-forward (rolling window) cross-validation is correct because it ensures that future data never leaks into the training set; the training window always precedes the validation window. Stratified k-fold cross-validation is wrong because it shuffles observations, allowing future data to appear in training. Leave-one-out cross-validation is wrong for the same data-leakage reason. Shuffle-split cross-validation is wrong because shuffling destroys temporal ordering and causes look-ahead bias.