
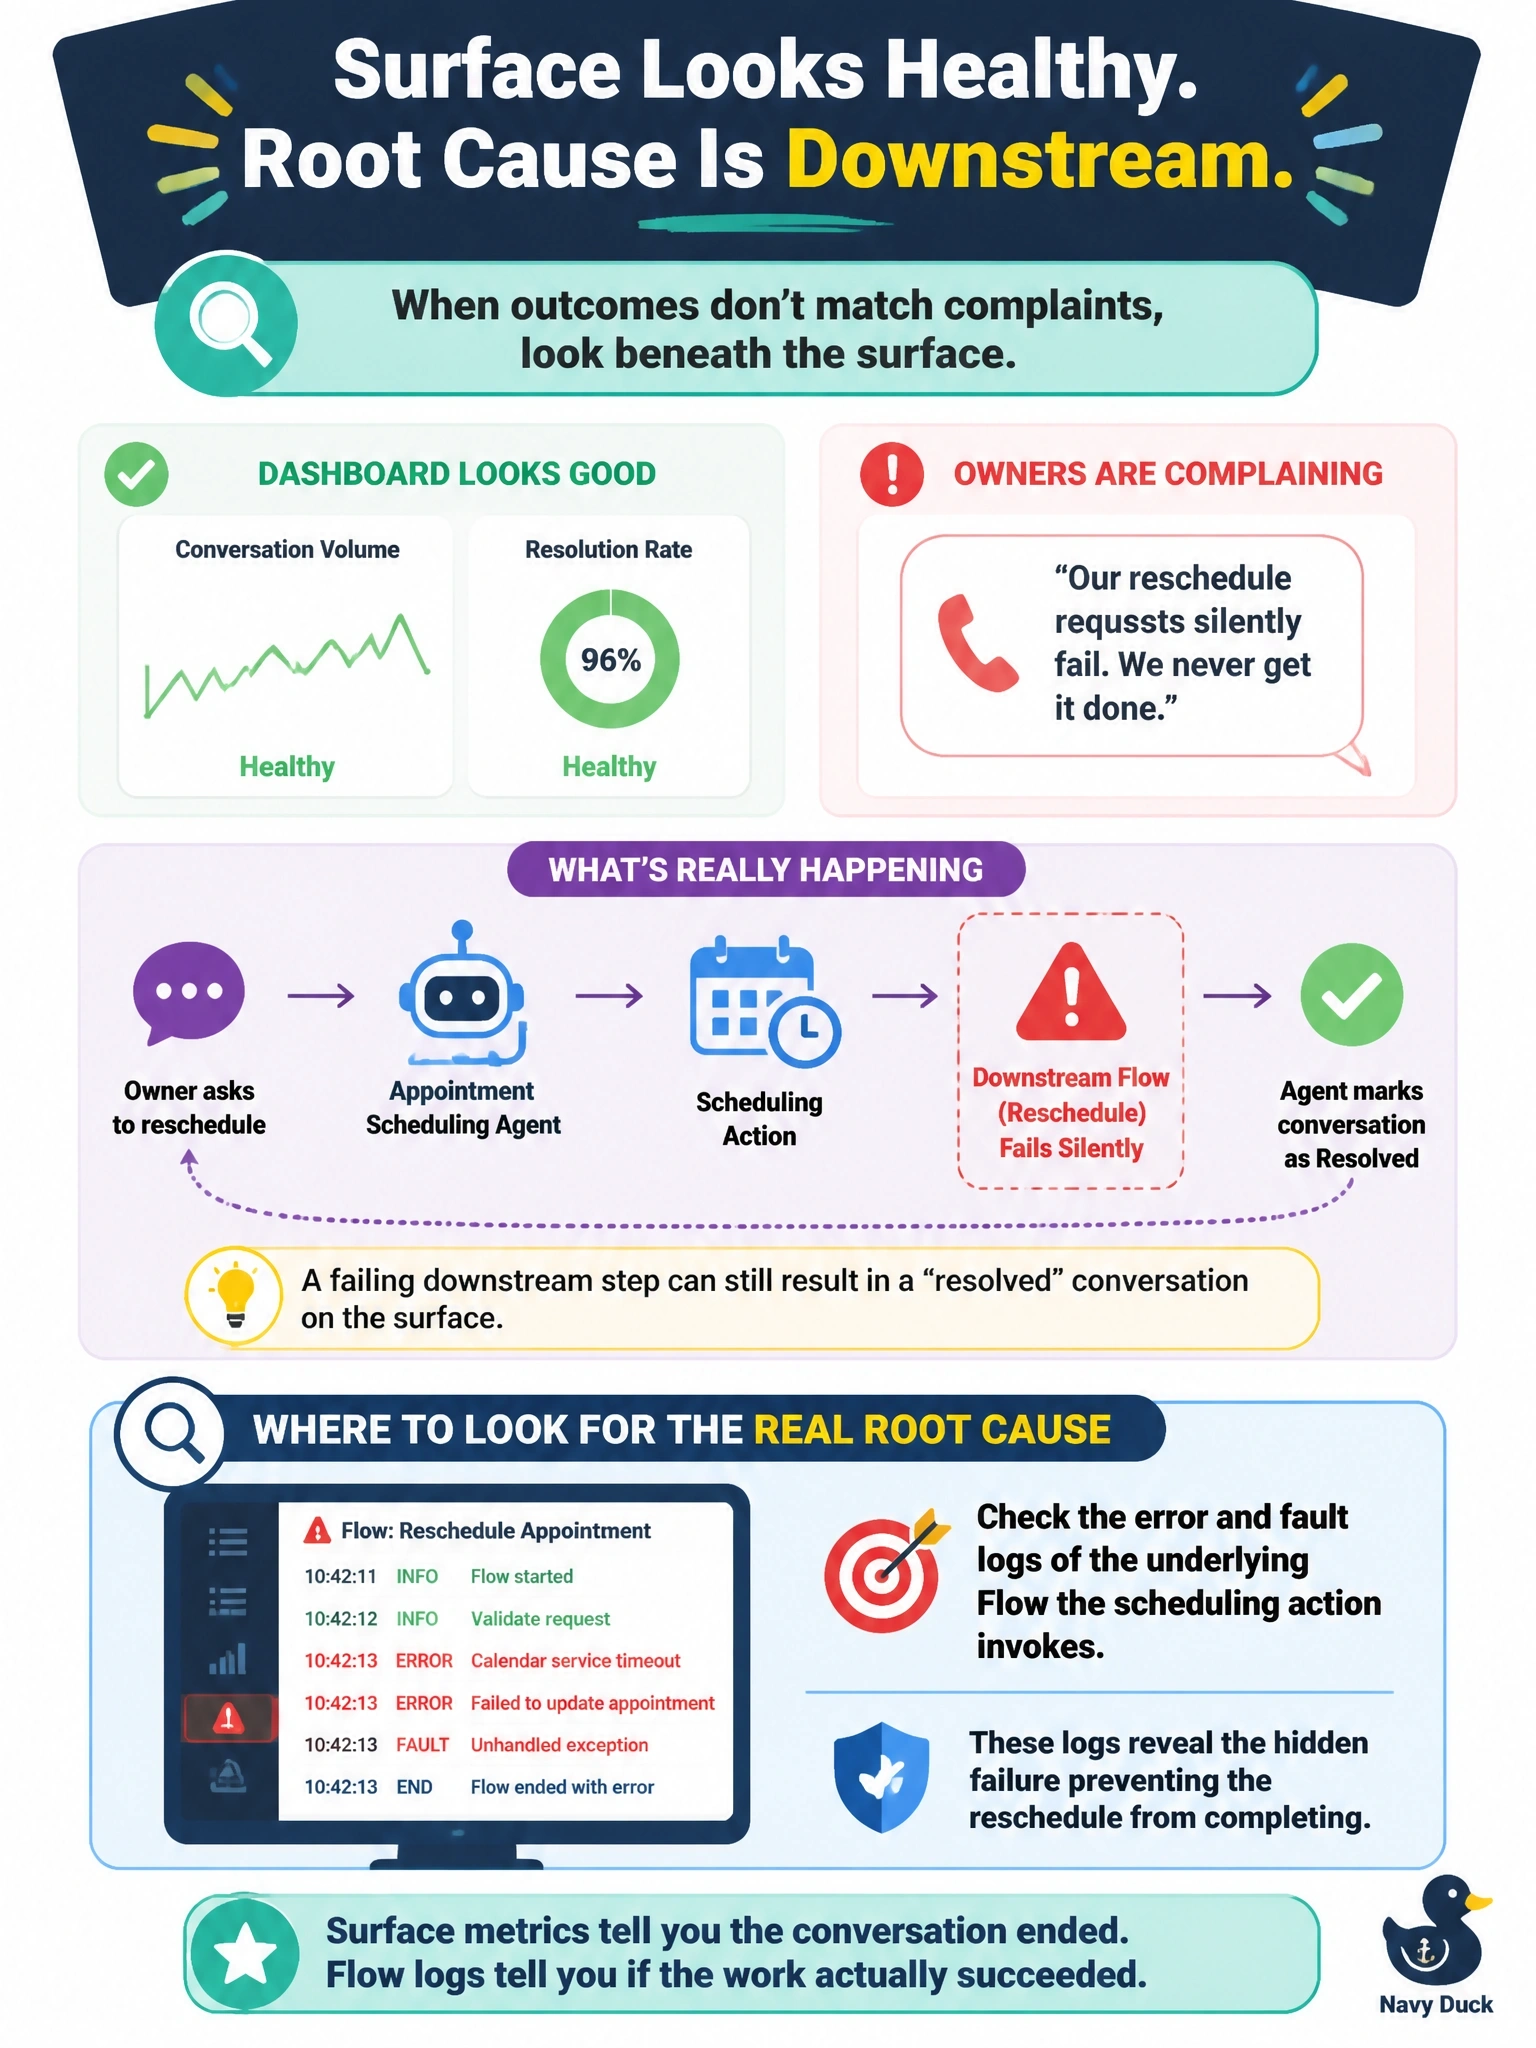
Cobblestone Veterinary Alliance's adoption dashboard shows the appointment-scheduling agent's conversation volume and resolution rate looking healthy, yet owners are calling the front desk to complain that reschedule requests silently fail. Where should the specialist look to find the actual root cause?
Select an answer to reveal the explanation.
Short Explanation
A pretty adoption dashboard only tells you conversations happened, not that the action underneath actually succeeded. When the two disagree, go look at the Flow's own error logs, that's where a silent failure actually leaves a trace.
Full Explanation
Adoption metrics like conversation volume and a topic-level resolution rate describe how the agent-level conversation was scored, but they do not guarantee that every downstream action genuinely succeeded; if the scheduling agent action invokes a Flow that errors out silently, the agent may still log the interaction as resolved from its own perspective while the actual appointment change never took effect. The specialist needs to dig into the Flow's own error and fault logs to find that kind of downstream failure, since that is where the actual system-level fault gets recorded. A wrong classification description would misroute the conversation to the wrong topic entirely, which is a different, earlier-stage failure and not one that produces a healthy-looking resolution metric with a silently broken action underneath. The Einstein Trust Layer audit trail is about data masking, toxicity scoring, and grounding transparency, not about tracking whether a Flow-backed action executed successfully, so it would not surface this problem. Scheduling data lives in structured CRM records, not the Data Library, which houses unstructured content like PDFs and knowledge articles for grounding, so a refresh-schedule check is irrelevant to a scheduling action failure.