
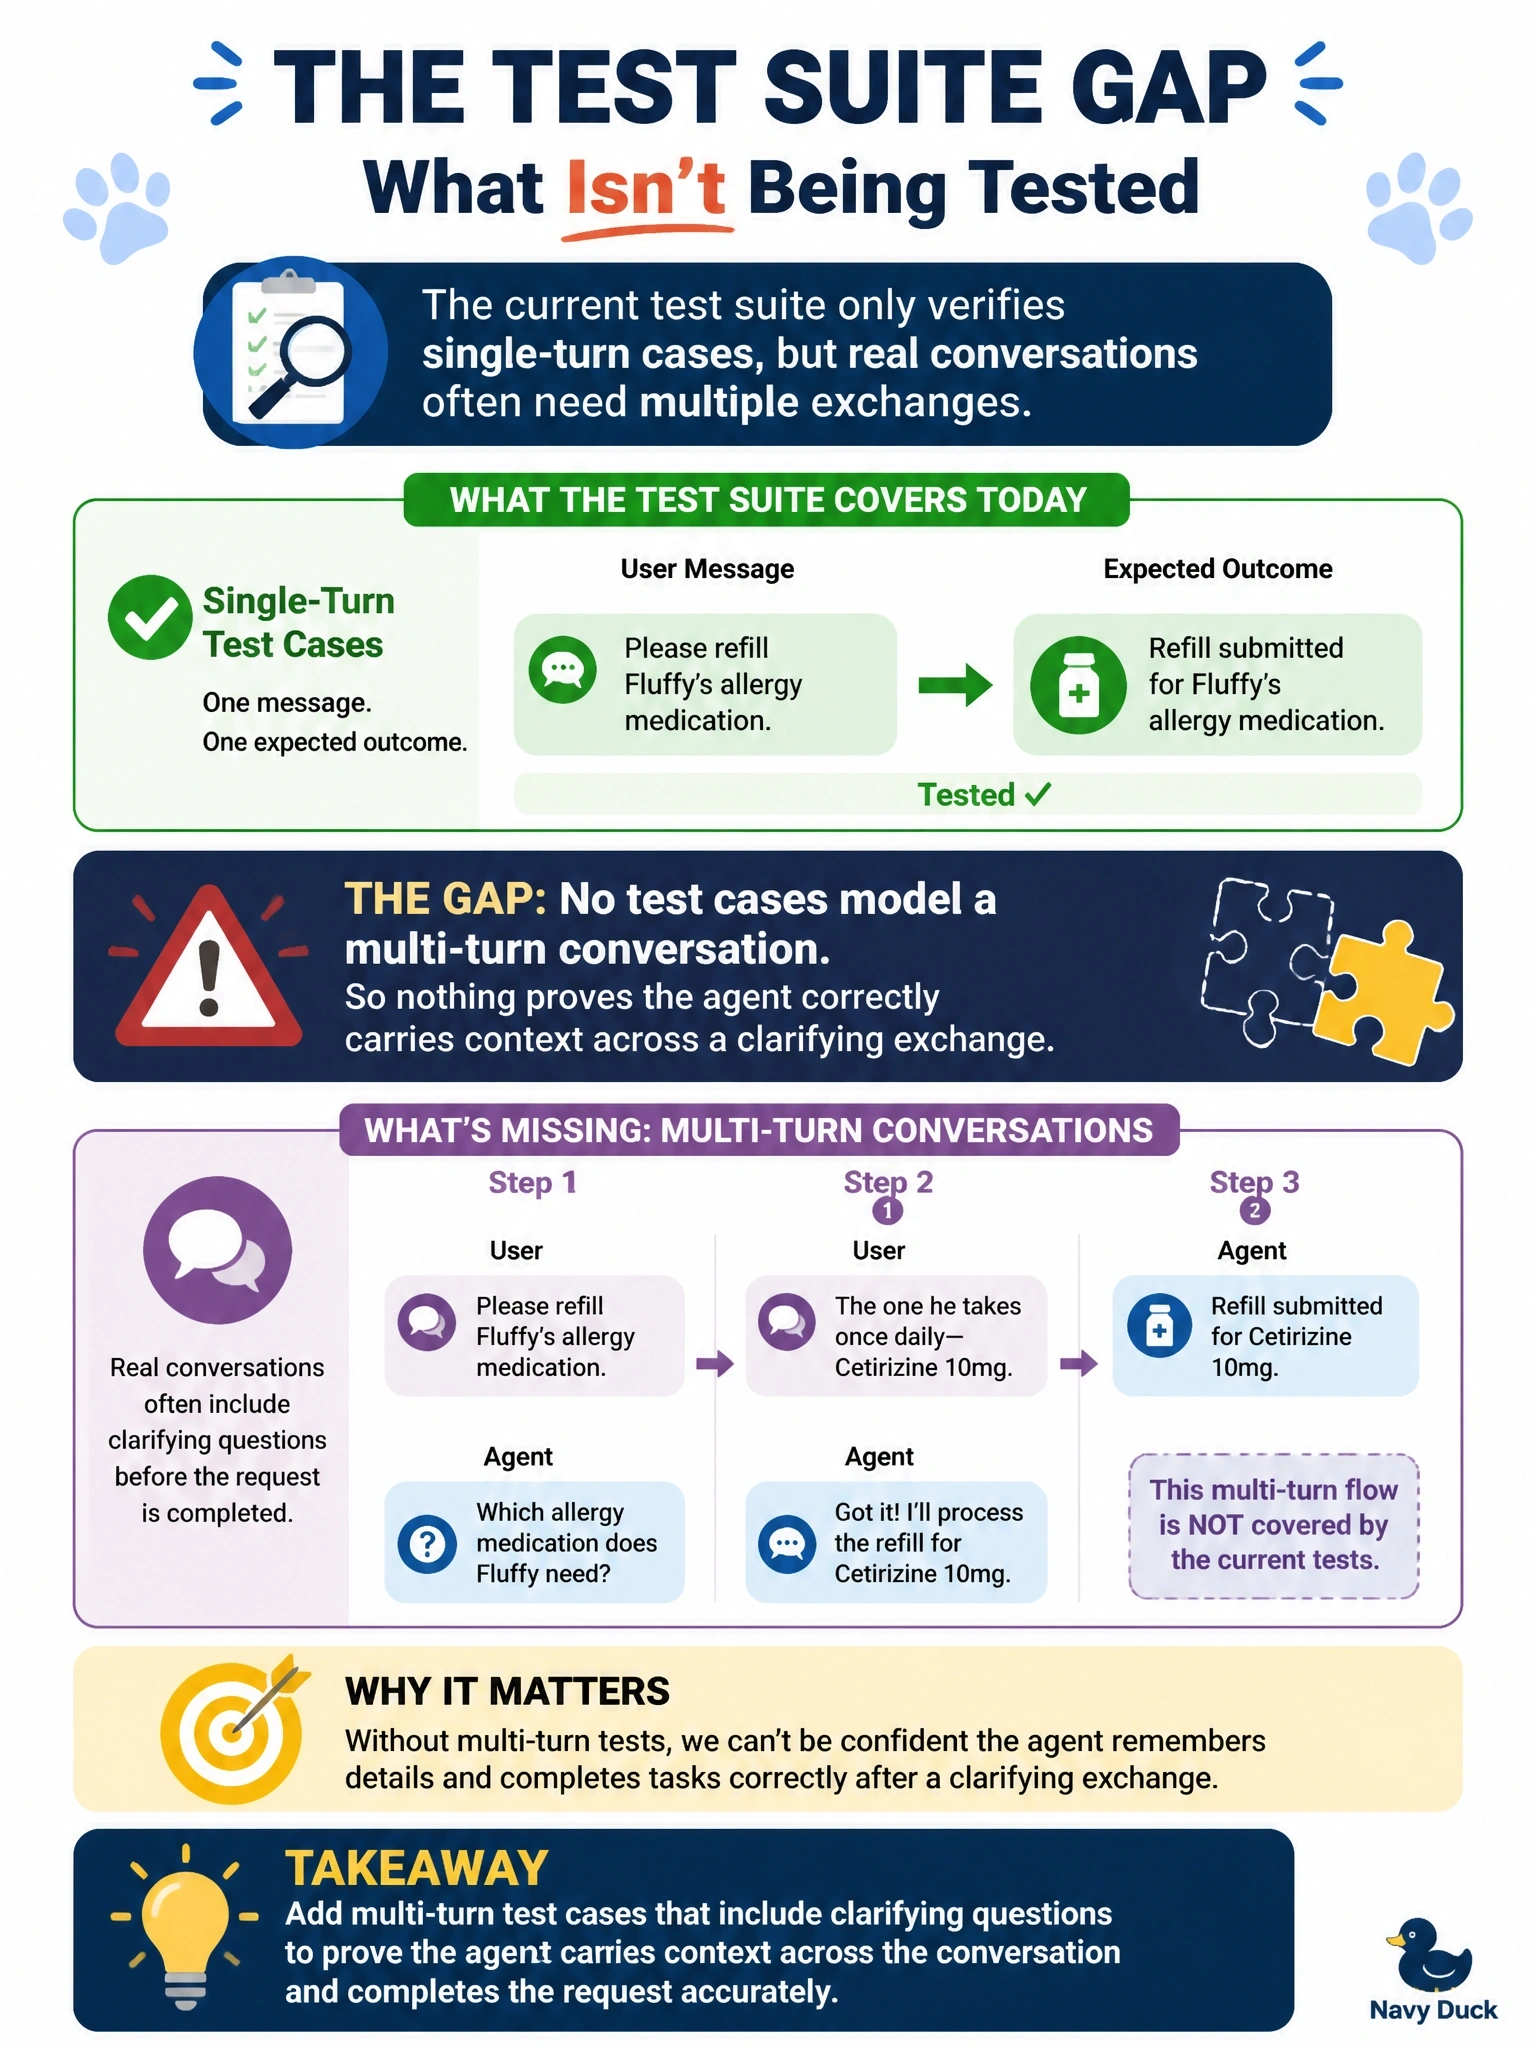
Alderwick Veterinary Group's Testing Center suite only contains single-turn test cases, each a single utterance with a single expected outcome. Its live agent, however, routinely handles follow-up clarifying questions before completing a refill request. What gap does this expose in the test suite?
Select an answer to reveal the explanation.
Short Explanation
A single-turn test only checks that the agent answers one line correctly, it says nothing about whether the agent remembers what the owner just told it. If the real agent asks a clarifying question and then acts on the answer, your test suite needs to rehearse that same back-and-forth.
Full Explanation
Real pet-owner conversations often are not one utterance and done: the agent may need to ask which pet, confirm a date, or clarify a dosage before it can complete a refill request, and each of those turns depends on context carried from the one before it. A test suite built entirely from single-turn cases never exercises that context-carrying behavior, so a regression in how the agent tracks conversation state could pass every existing test while still breaking in production. Adding too many test cases is not the described problem, and batch-run speed is a minor operational concern, not a correctness gap, so that option misdiagnoses the issue. The gap has nothing to do with Multi-Agent Interoperability, which concerns agents handing work to other agents or external systems, not a single agent clarifying within one conversation. And nothing here suggests Testing Center is incapable of evaluating the refill topic; the existing single-turn cases pass fine, which is exactly the misleading confidence the specialist needs to catch. The fix is to author multi-turn test cases that walk through the clarifying exchange and assert the final outcome is still correct after context has been carried across turns.