
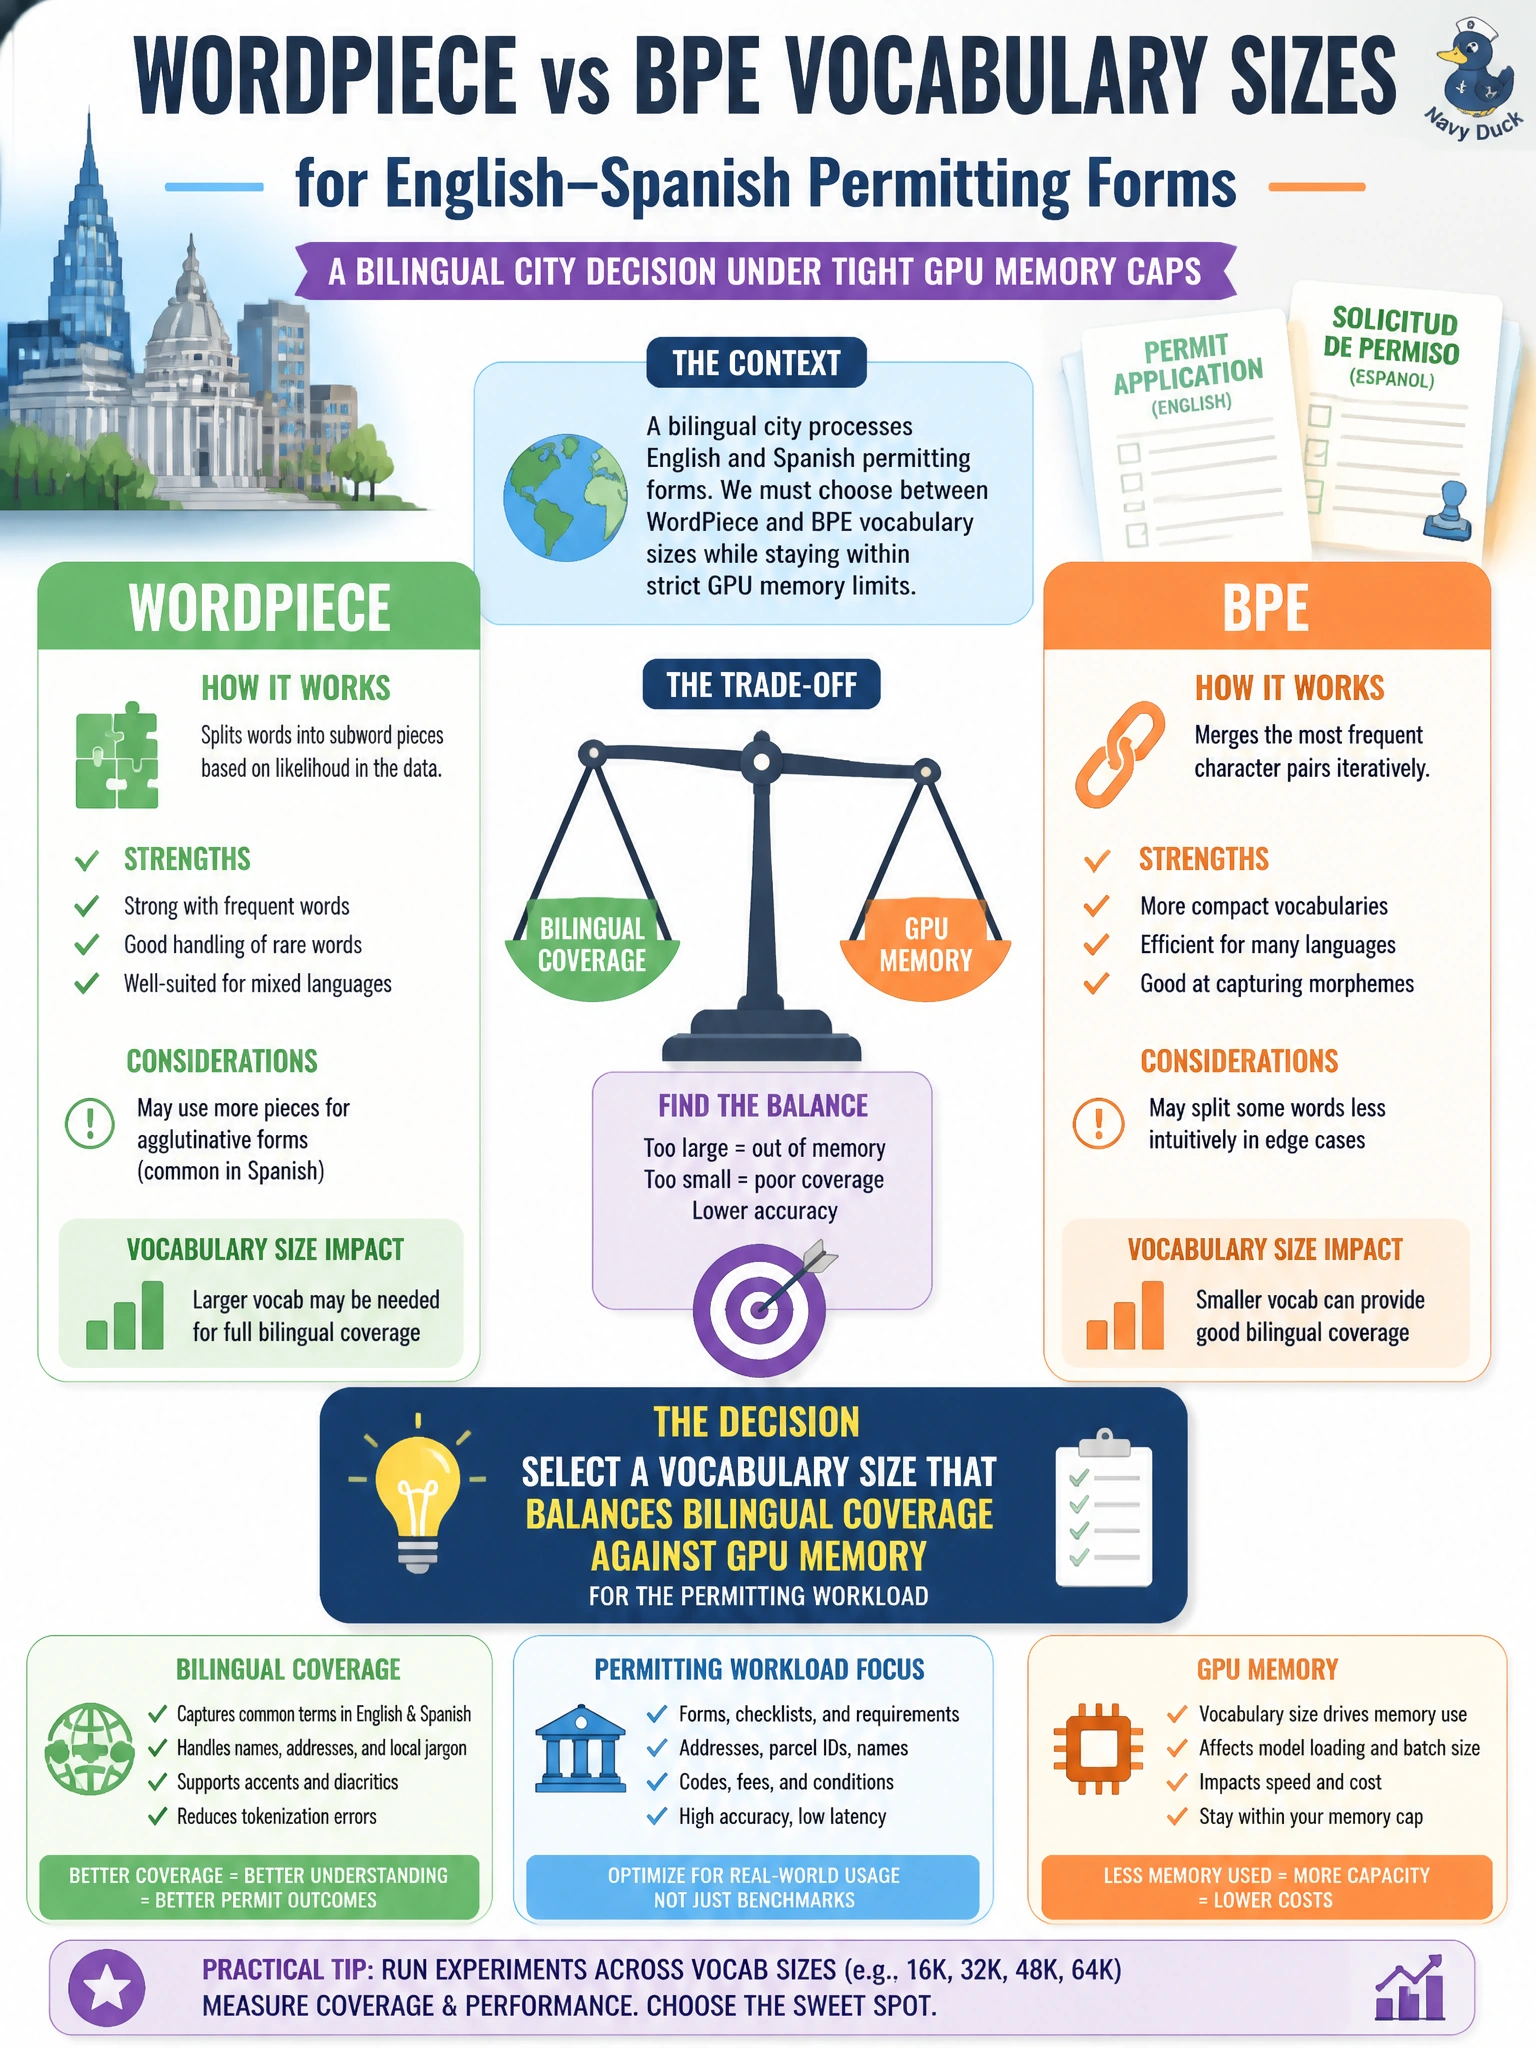
A bilingual city must choose WordPiece versus BPE vocabulary sizes for English–Spanish permitting forms under tight GPU memory caps. What trade-off should lead the decision?
Select an answer to reveal the explanation.
Short Explanation
Bigger bilingual vocab helps English and Spanish permits—until the GPU runs out of room. Size the WordPiece or BPE vocab for coverage without blowing the memory budget.
Full Explanation
Bilingual English–Spanish permitting forms force a vocabulary-size trade-off: WordPiece or BPE vocabularies that are too small over-segment Spanish morphology and permit jargon, raising fertility and hurting representation quality, while vocabularies that are too large inflate embedding-table memory and can exceed tight municipal GPU caps. The correct decision is to select a vocabulary size that balances bilingual coverage against GPU memory for the permitting workload—measure piece counts on real permit text in both languages and embedding footprint on the target device, then pick the smallest vocab that keeps fertility acceptable. Always picking the largest possible vocab because bilingual cities supposedly never hit memory limits ignores hardware reality; city-hall fine-tune and inference boxes often share GPUs with other services, and embedding rows scale linearly with vocab size. Using a 10-token vocab so every permit word becomes many pieces regardless of language maximizes fragmentation, destroys usable subword structure, and wastes sequence length on both English and Spanish. Ignoring vocabulary size and only changing the learning rate for Spanish rows confuses optimization hyperparameters with tokenization capacity: LR cannot restore missing bilingual merges or reduce OOM from oversized embedding tables. Exam caveat: WordPiece versus BPE differ in merge rules, but both still require an explicit vocab-size versus memory trade-off under bilingual civic loads—algorithm choice does not remove the constraint. Operational check: report mean tokens per permit field for EN and ES, peak embedding+model memory on the intended GPU, and choose the vocab point where coverage gains flatten while memory stays under the municipal allocation.