
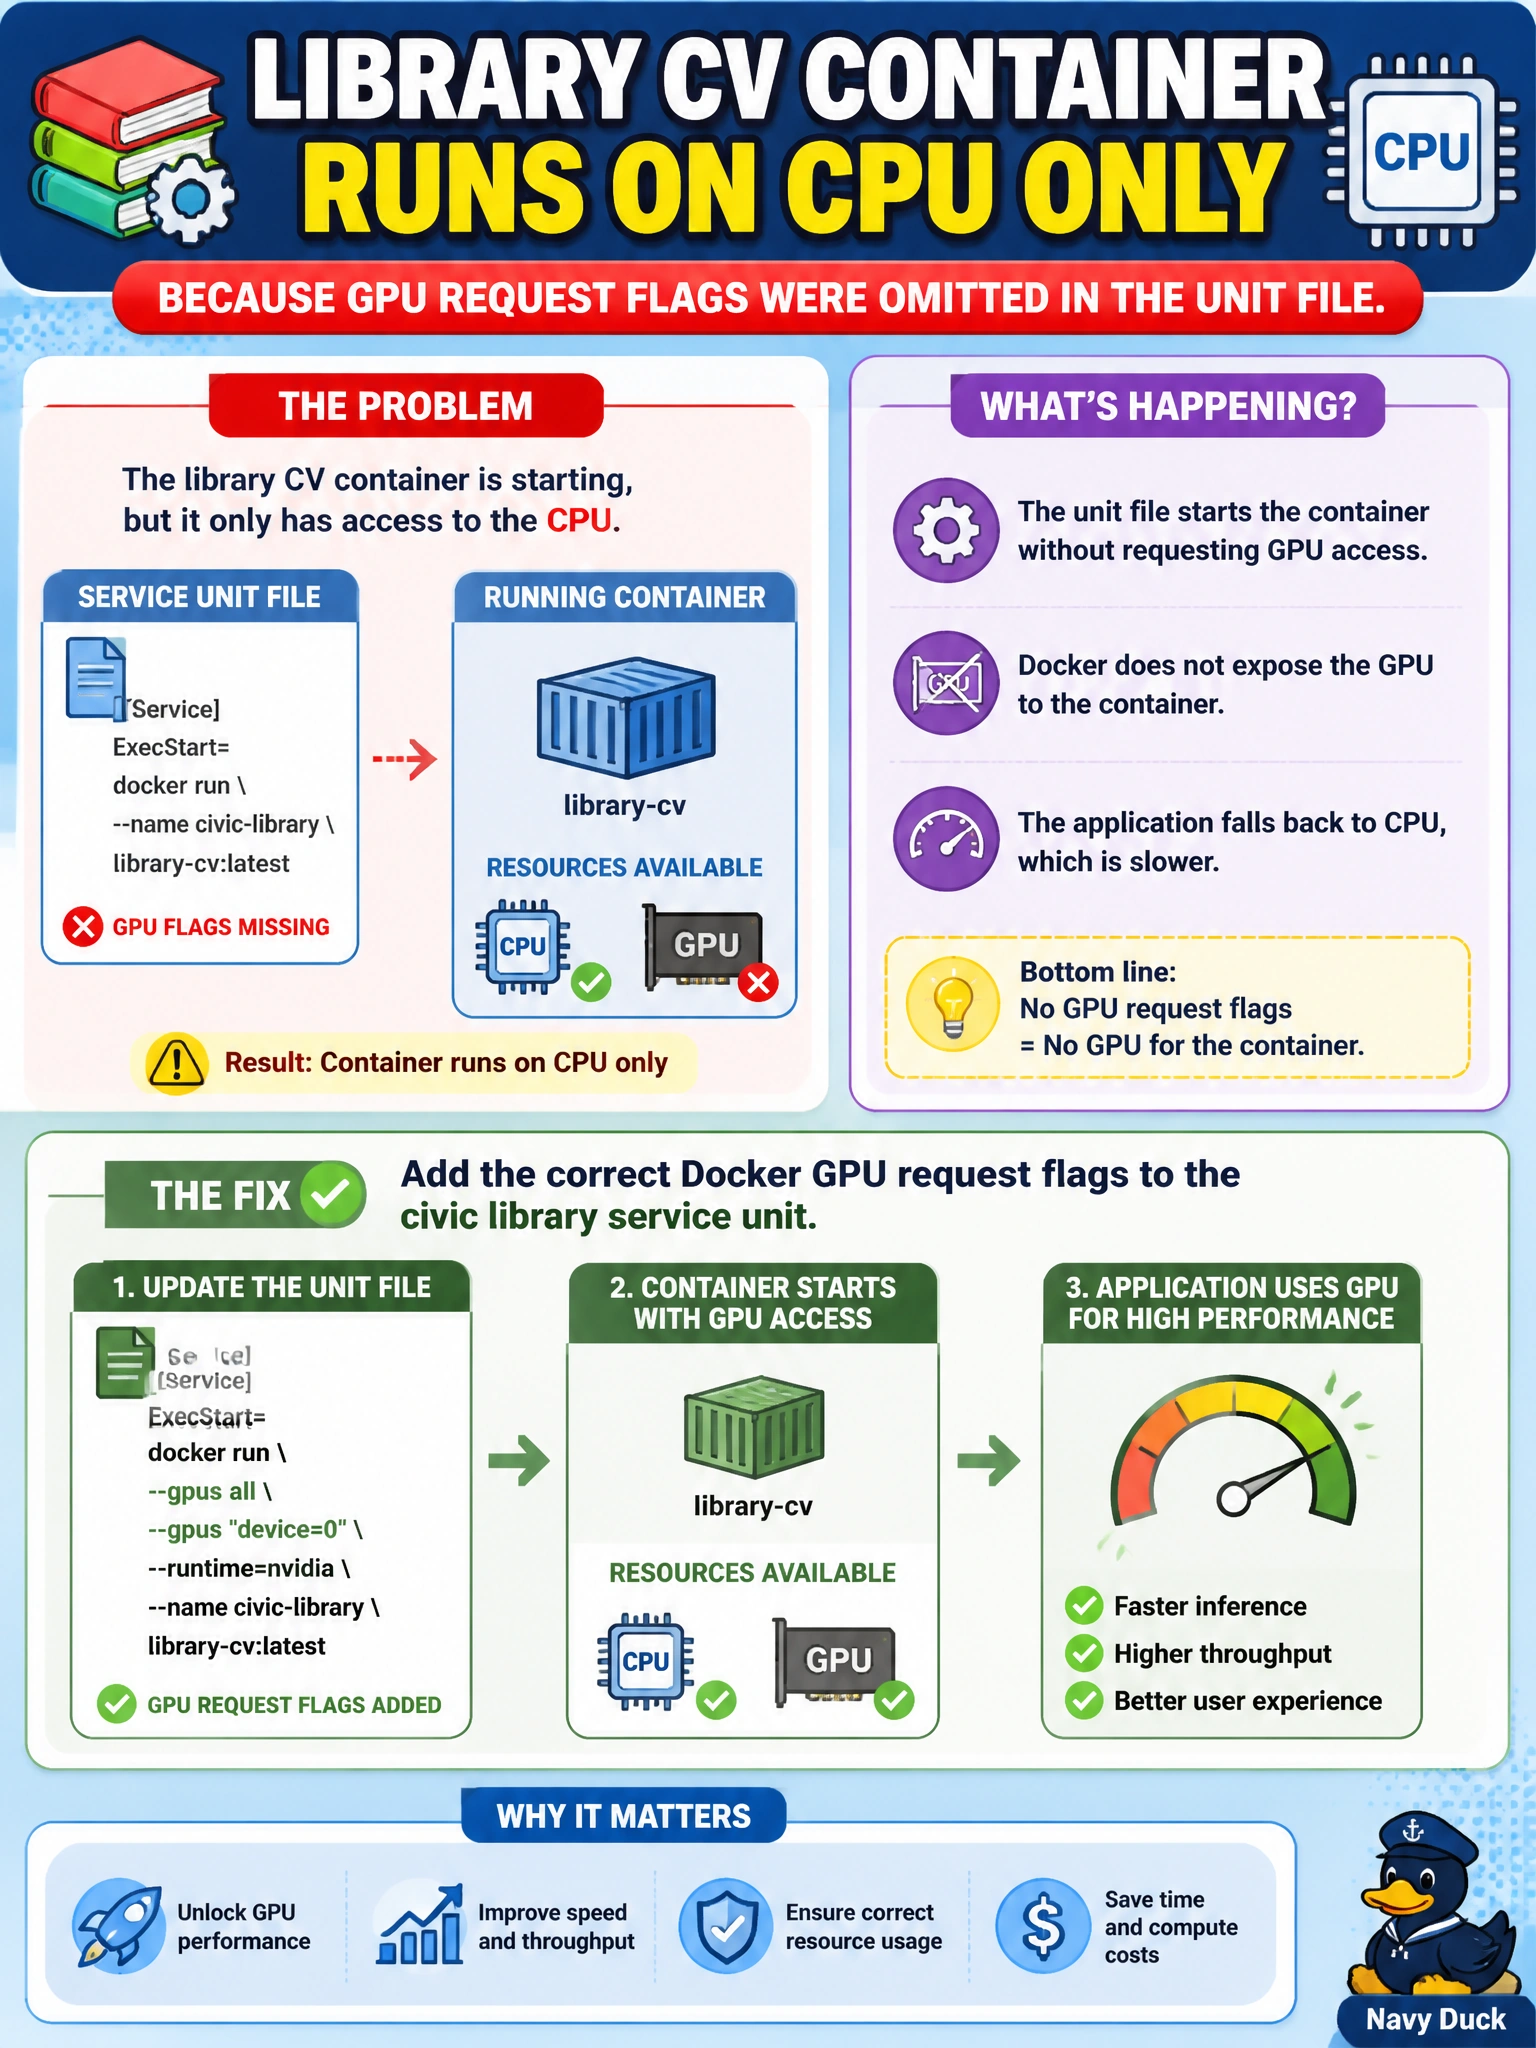
Library CV container runs on CPU only because GPU request flags were omitted in the unit file. What fix fits?
Select an answer to reveal the explanation.
Short Explanation
CPU-only library CV usually means the unit forgot to ask for a GPU—check the request flags like checking you ordered the right ticket. Renaming the container will not conjure devices.
Full Explanation
Library computer-vision containers that run on CPU only after GPU request flags were omitted from the unit file are fixed by adding the correct Docker GPU request flags to the civic library service unit. Systemd (or equivalent) units that launch docker run / compose must explicitly request GPUs—via --gpus, device requests, or the site's nvidia runtime flags—so the runtime mounts device nodes and libraries. Once the unit asks for accelerators, the CV workload can use the GPUs already present on the library nodes.
Buying more CPUs and abandoning GPU acceleration permanently fails by concept: it treats a missing request flag as a capacity planning decision and throws away the hardware the city already purchased for CV. Uninstalling the NVIDIA driver so CPU-only stays the default fails worse: it converts a unit-file omission into a host-wide GPU outage for every municipal service on that node. Renaming the container so Kubernetes invents GPU access fails because names do not allocate devices; without requests/limits (or Docker GPU flags), orchestrators will not conjure NVIDIA devices.
Exam caveat: unit-file GPU flags and Kubernetes device plugin requests are related ideas but not identical knobs. The stem is about a Docker service unit omitting GPU request flags—answer that layer. Also note that correct flags still require a healthy driver and NVIDIA Container Toolkit; flags alone cannot fix a broken toolkit, but here the stem points at omission.
Operational check: edit the library service unit to include the approved GPU request syntax, reload systemd, restart the service, and confirm nvidia-smi or a CUDA probe inside the container sees devices. Watch CV inference latency/throughput return to GPU baselines and commit the unit drop-in to the municipal image so the next sync does not strip the flags.