
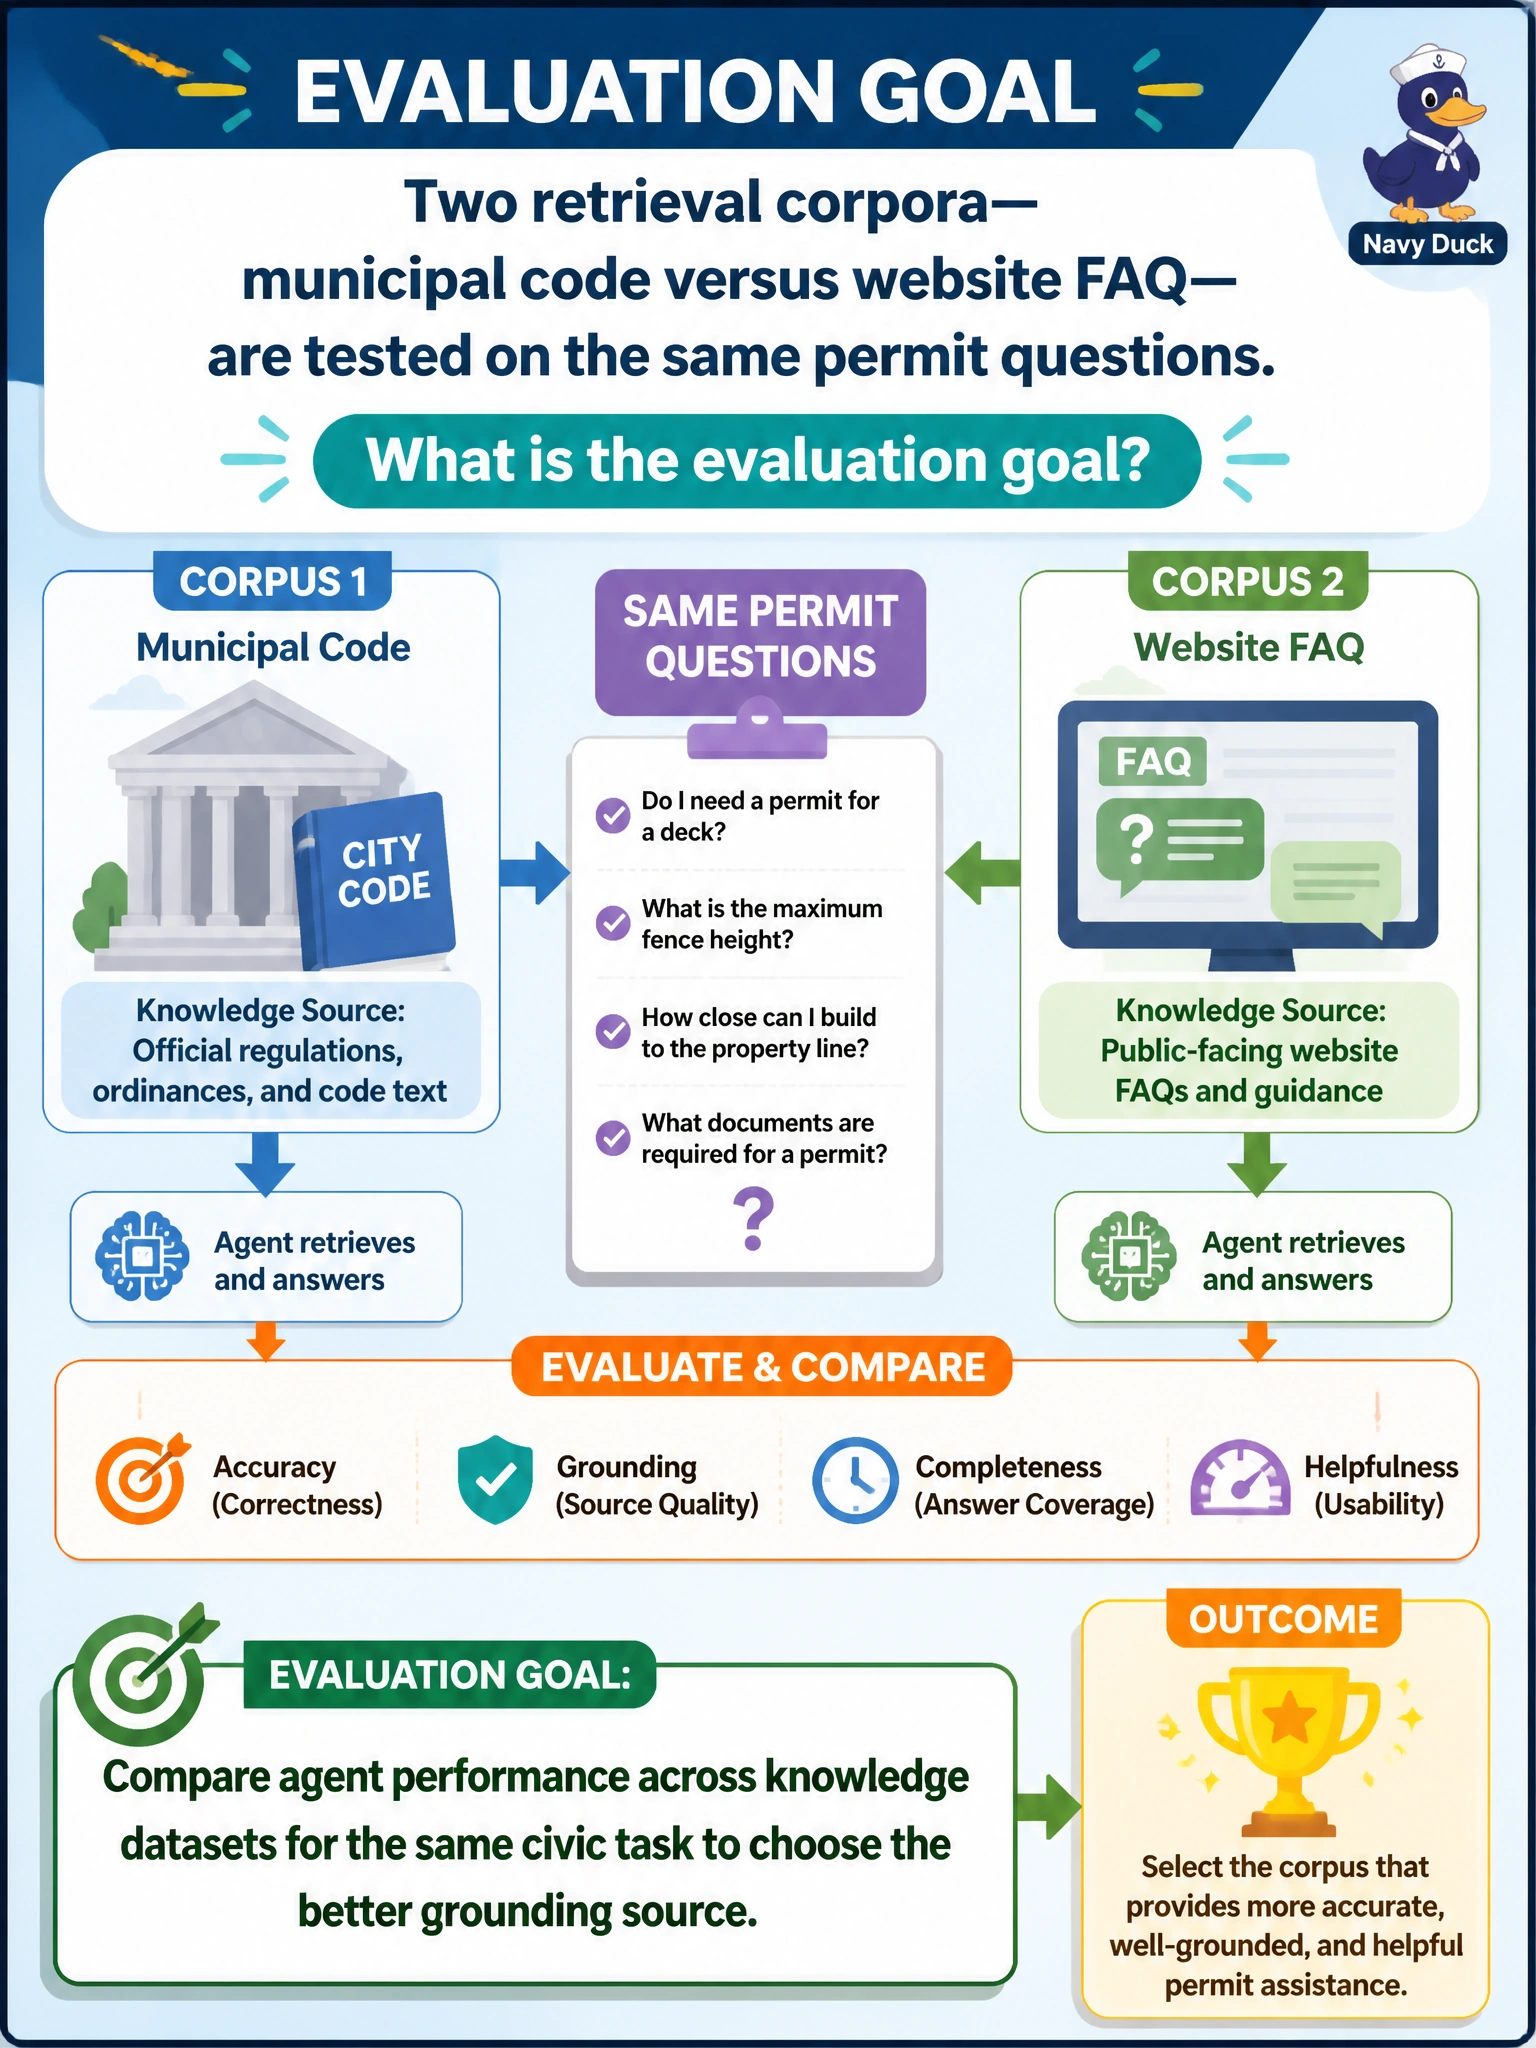
Two retrieval corpora—municipal code versus website FAQ—are tested on the same permit questions. What is the evaluation goal?
Select an answer to reveal the explanation.
Short Explanation
You’re testing two shelves against the same permit questions to see which one better grounds the agent. That’s a direct comparison of knowledge datasets—not proof that FAQs override code or a contest about screenshots.
Full Explanation
Testing the municipal code and website FAQ on the same permit questions compares agent performance across knowledge datasets for the same civic task, helping you choose the better grounding source. Holding the task fixed shows how the source affects accuracy, citations, and refusal behavior. Proving that website FAQs always legally override the municipal code is not an evaluation goal: a test cannot establish that legal rule, and code is typically authoritative over informal FAQ wording when they conflict. Letting each team evaluate its own corpus on a different question set avoids a direct comparison, so it cannot provide sound evidence for choosing between the sources. Measuring only how colorful FAQ pages look in screenshots says nothing about grounded permit accuracy. Exam caveat: when the sources conflict, score against the authority of record—usually municipal code—and treat an FAQ-based answer that contradicts code as a failure. Practical check: run the identical permit questions with each corpus, compare accuracy and conflict handling, then select or weight the better grounding source and document precedence rules for production RAG.