
The same agent scores high on trash-pickup FAQs but fails on complex variance petitions. What evaluation insight should teams take?
Select an answer to reveal the explanation.
Short Explanation
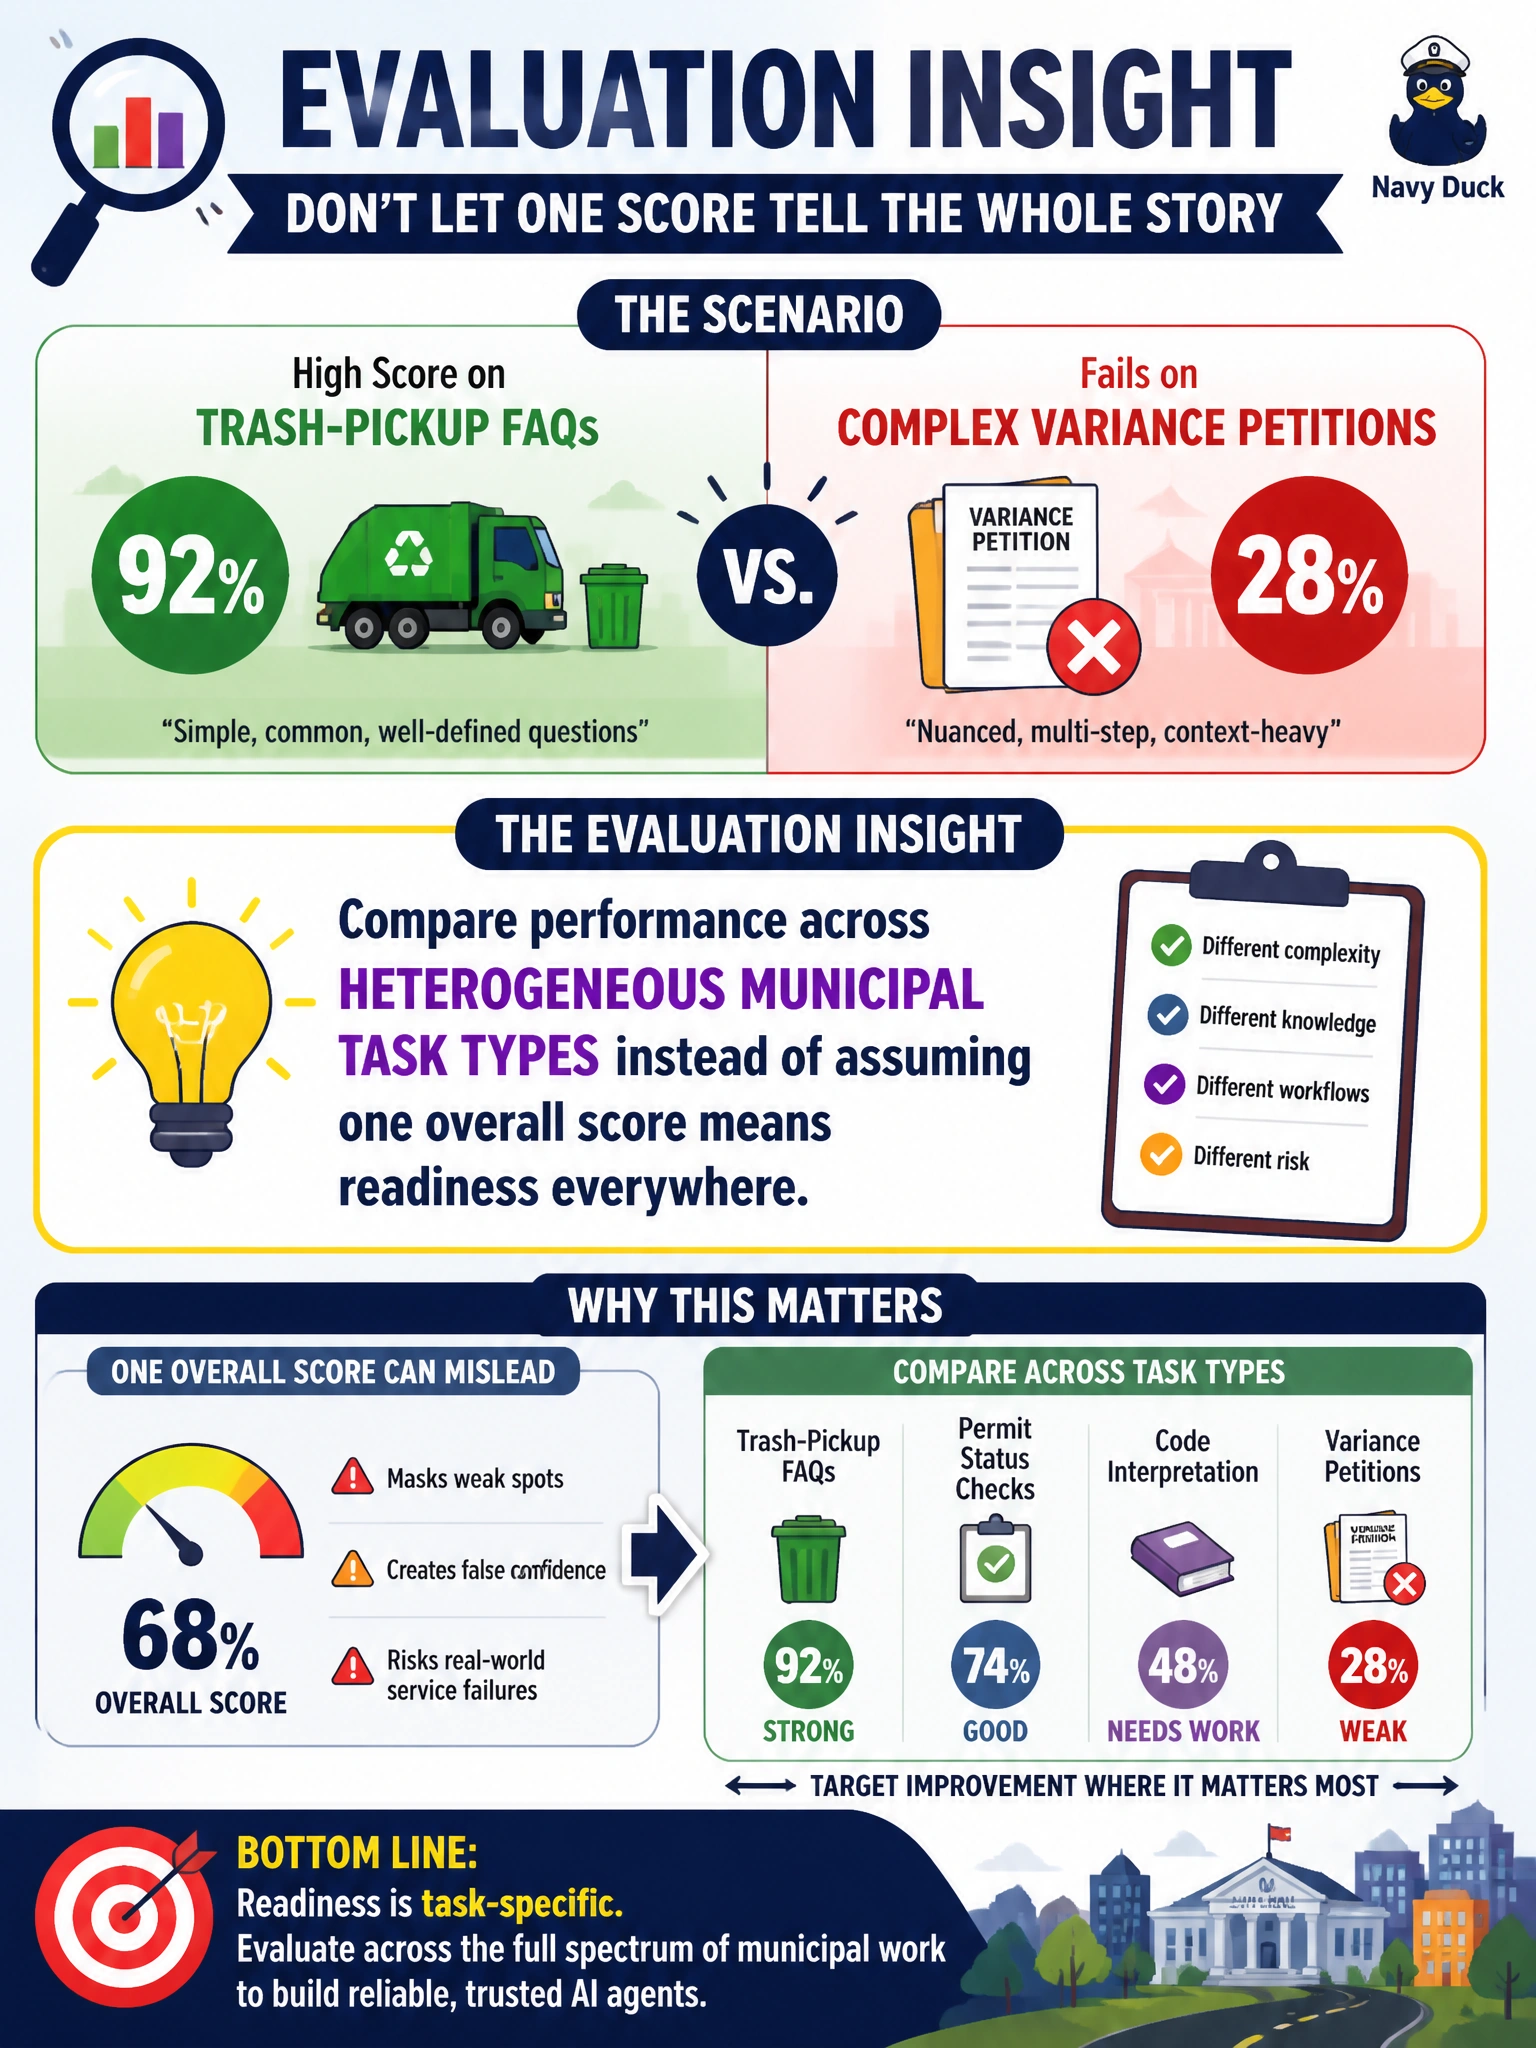
Aceing “when is trash day?” doesn’t mean the bot can handle a variance petition. Compare scores across task types so you see the gap. Hiding the hard failures is how you get surprised in production.
Full Explanation
When the same agent scores high on trash-pickup FAQs but fails on complex variance petitions, teams should compare performance across heterogeneous municipal task types instead of assuming one overall score means readiness everywhere. Cross-task evaluation reveals specialization gaps: FAQ success does not transfer to multi-step petition workflows with evidence, deadlines, and discretionary criteria. Civic readiness is task-conditional; publishing a single blended score can mask petition failure while celebrating trash-day fluency.
Declaring the agent production-ready for all city services based on FAQ success alone over-generalizes from the easy slice. Stopping evaluation of variance petitions because they are harder than FAQs abandons the harder civic workload residents still need. Averaging only the FAQ score into the public dashboard and hiding petition failures is metric laundering that misleads leadership.
Exam caveat: report and gate by task family (FAQ versus petitions versus triage, etc.), with separate readiness criteria per municipal service class. Operational check: maintain stratified scorecards for trash FAQs and variance petitions, require petition metrics to meet thresholds before enabling that skill in production, and refuse “overall green” status when petition slices remain red.