
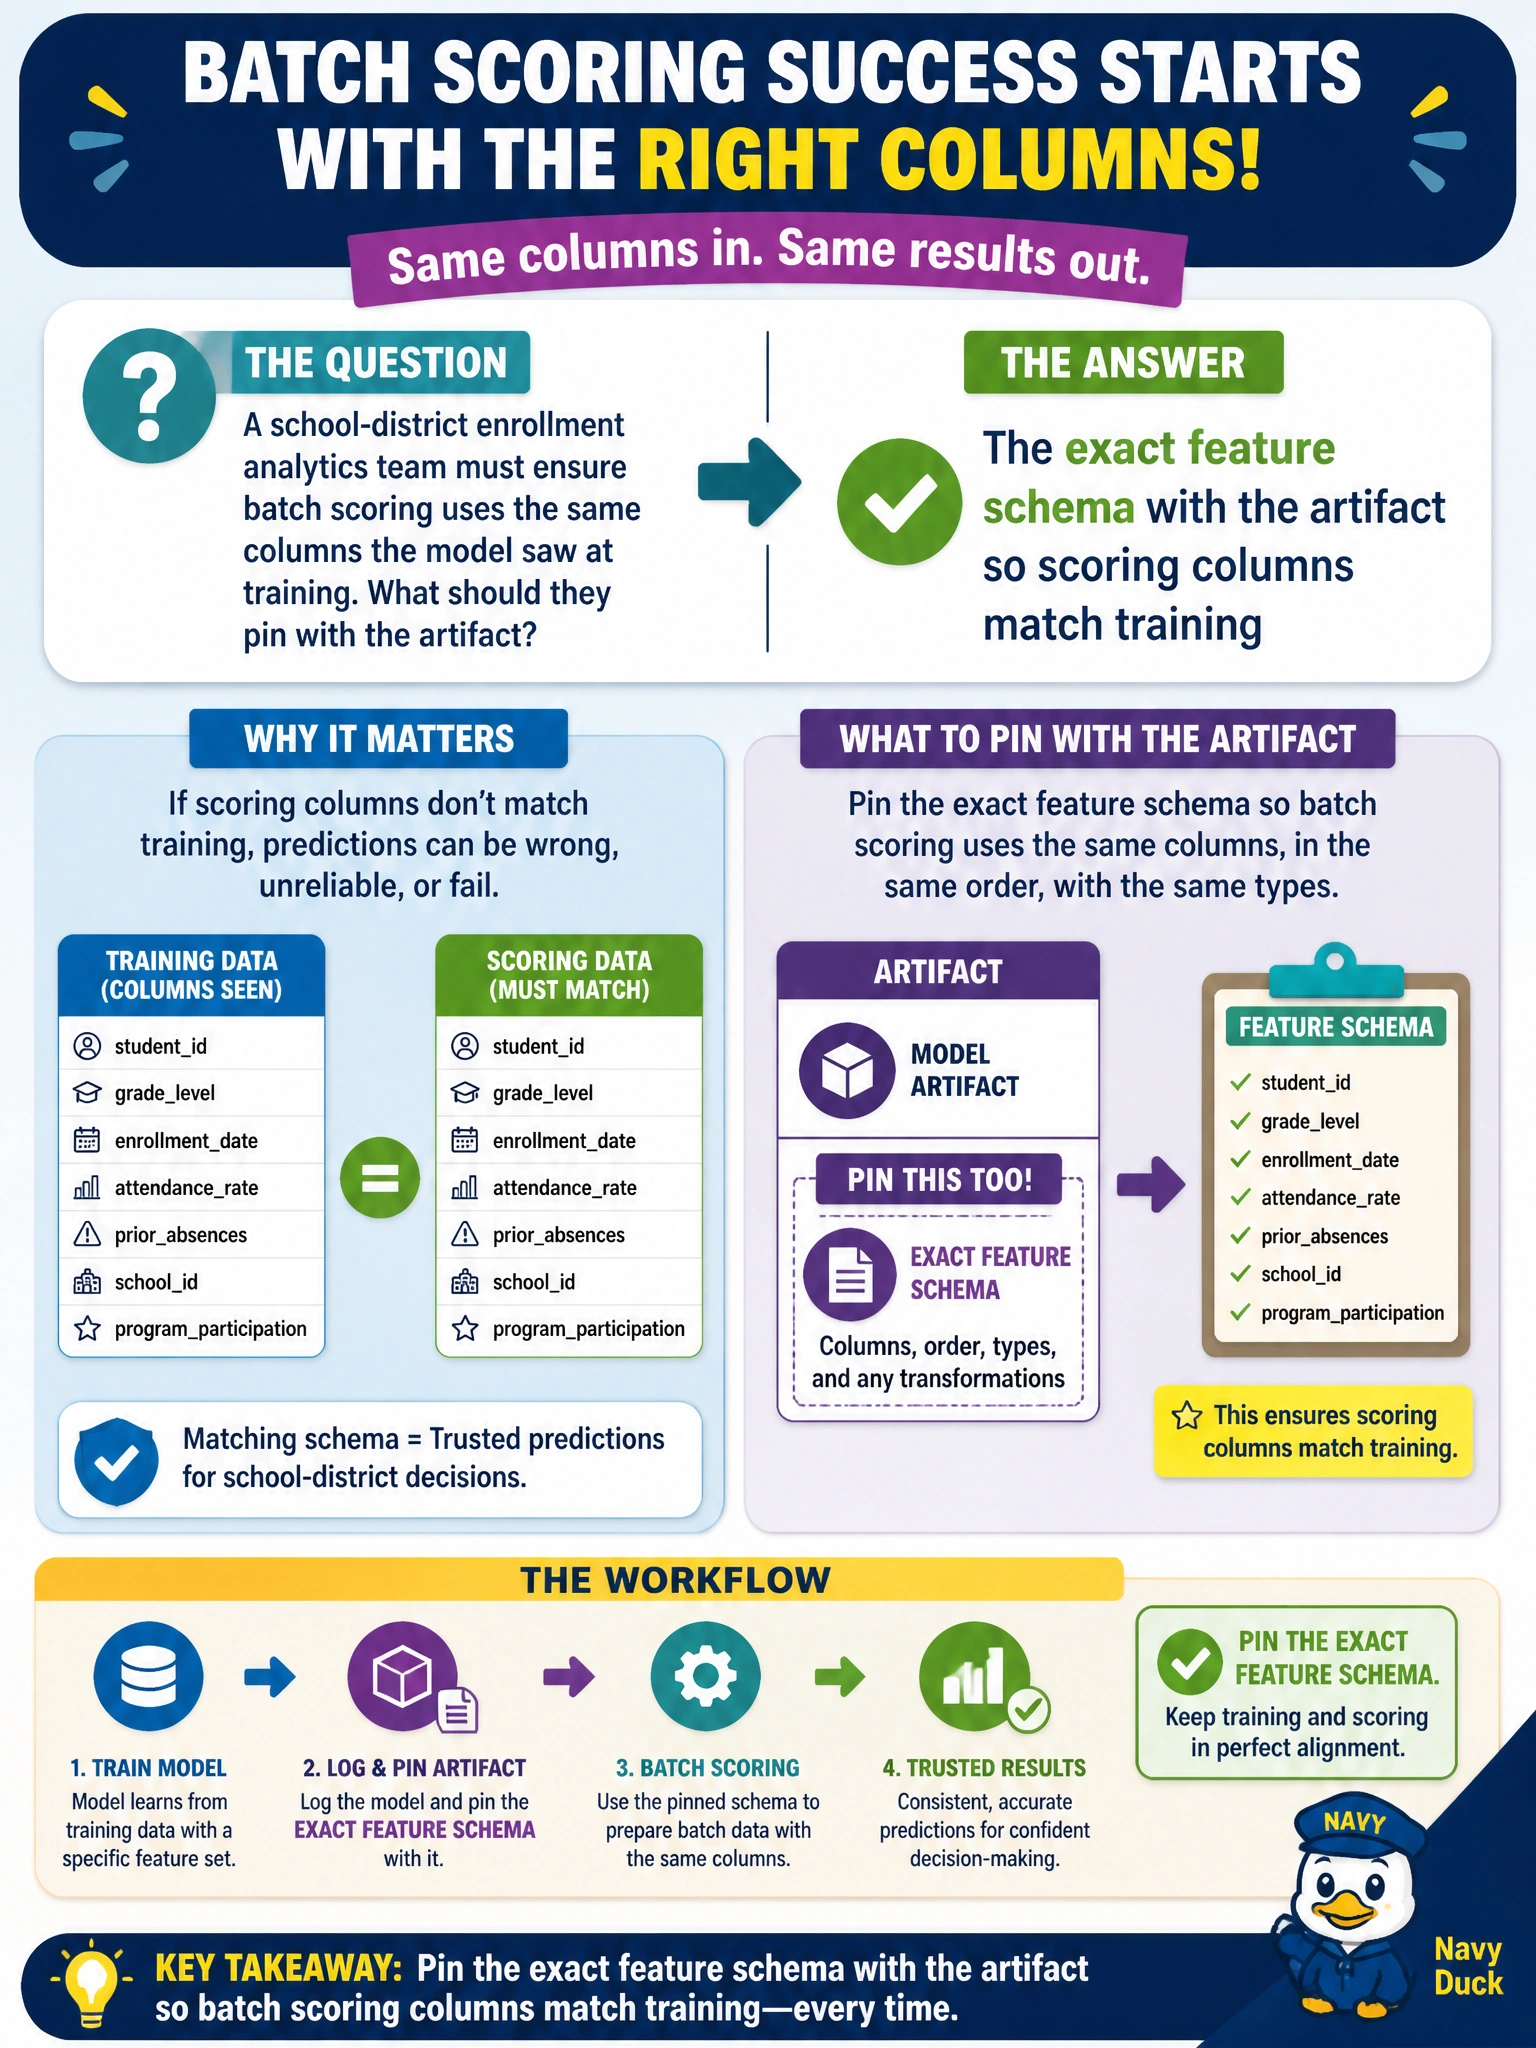
A school-district enrollment analytics team must ensure batch scoring uses the same columns the model saw at training. What should they pin with the artifact?
Select an answer to reveal the explanation.
Short Explanation
Pin the feature schema to the artifact like a packing list—scoring columns have to match what training used.
Full Explanation
A school-district enrollment analytics team that must ensure batch scoring uses the same columns the model saw at training should pin the exact feature schema with the artifact. Train/serve skew often appears as missing columns, reordered fields, renamed codes, or dtype changes between the training frame and the scoring extract. Coupling the schema (names, order, types, and encodings) to the model artifact is the associate control that keeps enrollment scores valid.
Pinning only the school mascot logo file fails by concept: branding assets do not define feature columns. Pinning only the superintendent's calendar invite fails because meeting metadata is unrelated to scoring schema. Using only a randomly shuffled column order at score time fails by deliberately breaking alignment with training and inviting silent wrong-feature assignment.
Exam caveat: schema pinning is specifically about preventing train/serve skew—not about storing unrelated district memorabilia with the model.
Operational check: serialize the training feature schema beside the enrollment artifact, validate the weekly scoring extract against that schema before predict, and fail the batch job loudly on column mismatch rather than scoring with a silent reshape.