
An infrastructure architect is designing a resource scheduling policy for a cluster of GPUs that runs both large-scale deep learning model training jobs and real-time user inference APIs. What is the most operationally efficient strategy for allocating resources between these two workloads?
Select an answer to reveal the explanation.
Short Explanation
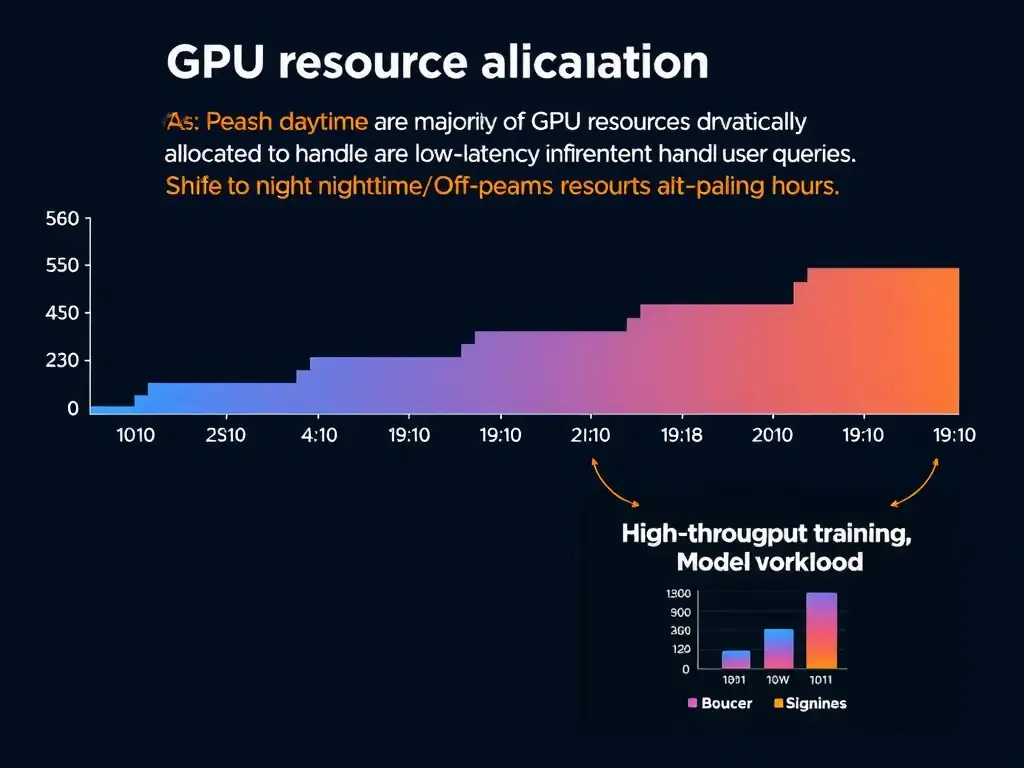
You can't let training hog every GPU while users wait. Keep inference on low-latency GPUs during peak traffic, then run training off-peak when the cluster has spare capacity. That keeps users fast and GPUs busy.
Full Explanation
Deep learning training and inference have fundamentally different performance profiles and SLAs. Training workloads are computationally heavy, throughput-oriented, and process massive datasets over hours, days, or weeks. They are typically run in batches and do not have strict real-time latency constraints, making them excellent candidates for scheduling during off-peak hours when general compute demand is low. Inference workloads are latency-sensitive and demand high availability. When a user requests a prediction, the model must process the query and respond in milliseconds. Because user traffic fluctuates throughout the day, the infrastructure must scale or dedicate resources to handle peak loads without introducing latency bottlenecks. The most efficient cluster resource management strategy combines these requirements: dedicate low-latency GPU infrastructure for inference tasks to handle peak user traffic, while scheduling resource-intensive training jobs to utilize maximum cluster capacity during off-peak hours. By reserving low-latency, highly available nodes for inference during peak hours and dynamically shifting resource allocations, or using job schedulers like Kubernetes/Slurm, to run large training runs during off-peak hours, organizations maximize GPU utilization and minimize costs. The equal-partition approach is inefficient because training and inference have highly asymmetric resource needs; equal partitioning leads to idle inference resources during low-traffic hours and starved training pipelines. The training-only-then-transition approach is unrealistic because enterprise models require continuous training, updating, and fine-tuning, and you cannot shut down inference services to train a new model. The approach that assigns all high-speed interconnects and premium GPUs to inference pipelines while reserving legacy hardware exclusively for model training is incorrect because training actually requires the fastest available hardware and high-speed interconnects, like InfiniBand or NVLink, to coordinate weights across GPUs, whereas single-instance inference can often be run on smaller, mid-range GPUs or split-GPU profiles such as MIG.