
You're explaining the difference between training and inference phases to a stakeholder unfamiliar with deep learning workflows. How do these phases differ architecturally?
Select an answer to reveal the explanation.
Short Explanation
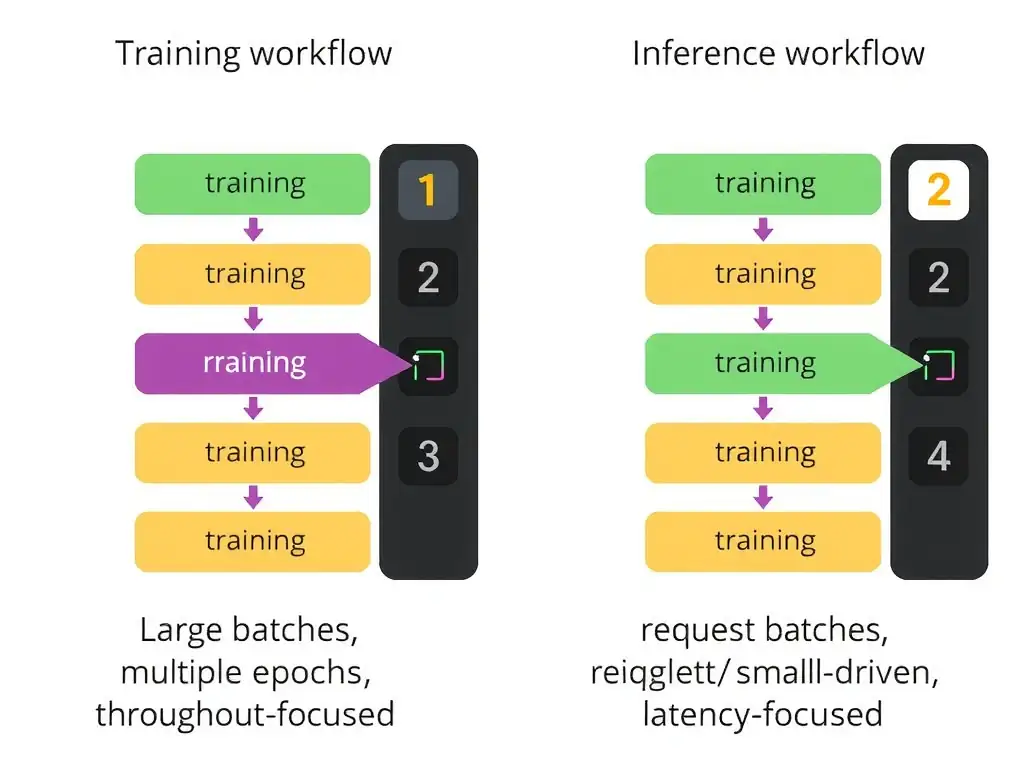
Training is about chewing through huge datasets to build the model, while inference is about answering requests fast. You're optimizing for throughput in training and latency in inference, so the architectures aren't the same.
Full Explanation
Training and inference have different architectural requirements. The correct distinction is that training optimizes for handling large datasets to build the model, while inference focuses on low-latency processing for real-time predictions. During training, you process terabytes of data, do forward passes, compute loss, backpropagate gradients, and update weights. Throughput is king: how much data can you process per unit time? You want large batch sizes, high GPU utilization, and efficient distributed training. During inference, you have a trained model and make predictions. A customer query arrives, you feed it through the model, and return the prediction. Latency matters: how fast can you respond? You might use a smaller batch size, sometimes one, and tolerate lower throughput if it means lower latency. They can share infrastructure, such as H100 clusters, but tradeoffs exist. If you optimize only for training throughput, inference latency may rise. If you optimize for inference latency, training may slow. Large organizations often separate infrastructure: training clusters optimized for throughput, inference clusters optimized for latency. The question tests whether you understand these workload differences. The claim that both require equally large datasets and high-performance computing resources is wrong because inference consumes incoming requests, not the full training corpus. The claim that training focuses on real-time predictions while inference processes vast datasets offline is wrong because it reverses the roles. The claim that both are latency-sensitive and must deliver real-time results is wrong because training is throughput-oriented and can tolerate longer runtimes.