
An MLOps engineer is designing an automated retraining pipeline for a predictive maintenance model. The goal is to ensure the model always incorporates the latest sensor readings while preventing unnecessary computation and hardware strain. Which orchestration strategy best meets these requirements?
Select an answer to reveal the explanation.
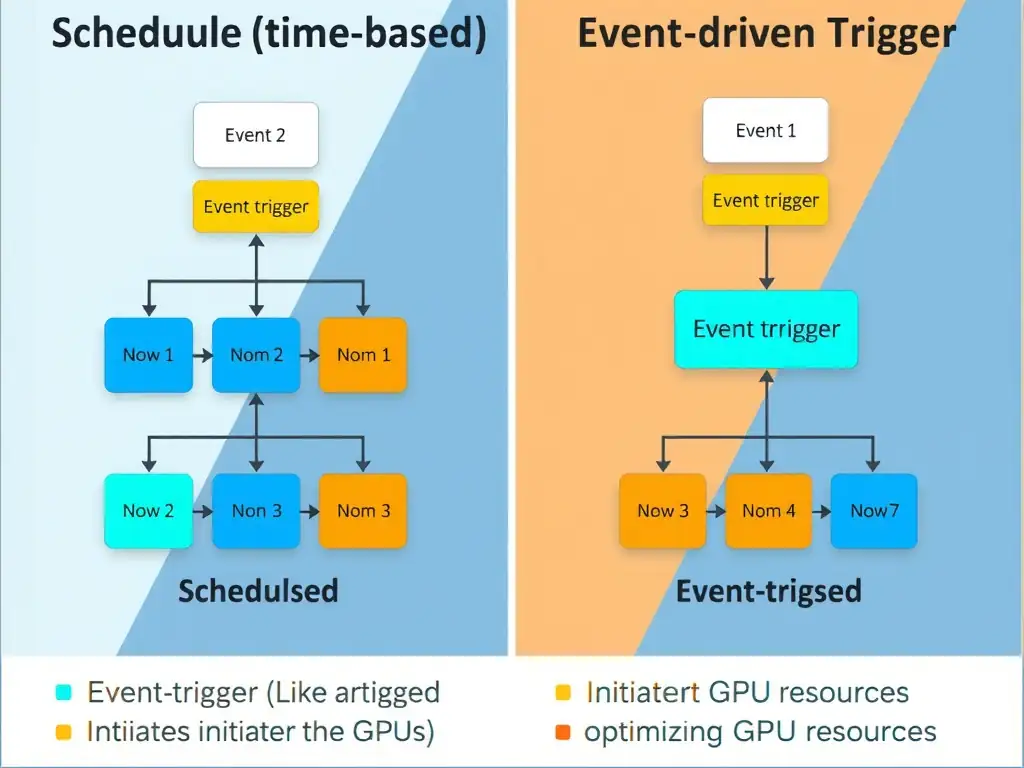
Short Explanation
Here's the deal: you want the pipeline to fire only when fresh sensor data actually shows up and crosses a useful threshold. That keeps your predictive-maintenance model current without burning GPU cycles on empty runs. Event-driven triggers give you automation, freshness, and hardware sanity.
Full Explanation
In MLOps (Machine Learning Operations), designing efficient pipelines requires balancing model accuracy (which depends on training on the most current data) with resource optimization (minimizing compute costs and hardware wear). Event-driven orchestration is the most effective way to achieve this balance. Instead of running pipelines on arbitrary schedules, the orchestration platform (such as Kubeflow Pipelines, Apache Airflow, or Prefect) listens for specific events—such as a file upload to an S3 bucket, a new database record, or a message in a queue. When new data arrives and meets pre-defined criteria (like data volume or quality checks), the event triggers the preprocessing, training, and deployment steps. This ensures that the model is updated only when there is new information to learn from, eliminating redundant runs that would otherwise overload the compute cluster. Reviewing the alternatives: the static, hourly cron schedule regardless of whether new data has arrived leads to resource waste when data is static, as the system consumes power and GPU cycles to retrain on unchanged datasets. The off-peak weekend-hours restriction ensures low load during busy hours but fails to keep the model updated in a timely manner. If critical data arrives on Monday morning, the model remains outdated until the weekend. The manual-intervention configuration does not scale, introduces human error, and contradicts the core MLOps goal of automation.