
An infrastructure manager at a hyperscale AI data center running thousands of NVIDIA Tensor Core GPUs wants to transition from reactive troubleshooting to a proactive operations model. The goal is to detect early-stage hardware anomalies and predict GPU failures before they cause training jobs to crash. Which strategy should they implement to achieve this?
Select an answer to reveal the explanation.
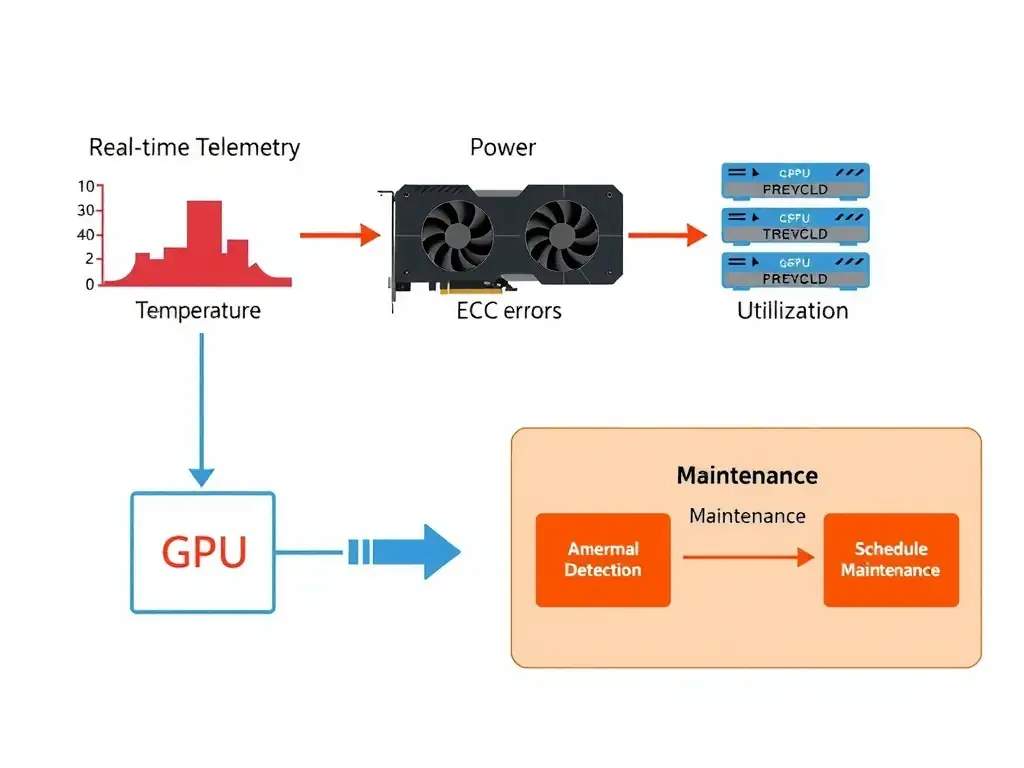
Short Explanation
Check this out: if you're running thousands of Tensor Core GPUs, you can't wait for a card to fry and kill a training run. You need real-time telemetry fed into machine-learning predictive maintenance so you catch subtle anomalies before failure. Proactive is the only way to live in production.
Full Explanation
In a high-density artificial-intelligence data center, GPU hardware failures are a leading cause of job interruptions and costly downtime. Traditional monitoring methods, such as simple threshold-based alerts or periodic manual inspections, are inherently reactive or insufficient. They fail to capture complex, multi-variable degradation patterns that precede hardware failure. The most effective approach is a predictive maintenance system that ingests and analyzes high-frequency, real-time GPU telemetry data. This telemetry includes parameters such as voltage fluctuations, memory error rates (ECC errors), fan speeds, power consumption patterns, and thermals. Machine learning models trained on historical failure data can identify anomalous signatures across these metrics, predicting failures days or hours in advance. This allows operations teams to gracefully drain workloads from the affected node and schedule maintenance without interrupting active training runs. The nightly shell-script approach that queries GPU health using nvidia-smi and logs output to a central repository is too slow; it misses transient issues or sudden failures that occur during active training. The static threshold-alert approach in Prometheus that pages when any GPU exceeds 85°C is limited because thermals are only a single metric; a GPU can fail due to memory degradation (SRAM/HBM) or power delivery issues without ever crossing a temperature threshold. The manual daily log-auditing approach, including network switch utilization review, is slow, non-scalable, and prone to human error, making it impractical for modern, fast-paced artificial-intelligence infrastructures.