
Imagine you are managing a shared AI cluster where the computer vision team is doing heavy training, the NLP team is running real-time chatbots, and the data science team is spinning up hyperparameter sweeps. You notice some GPUs are sitting completely idle while others are pinned at 100%, causing massive job queues. What is the most efficient strategy to maximize cluster-wide GPU utilization and ensure fair access?
Select an answer to reveal the explanation.
Short Explanation
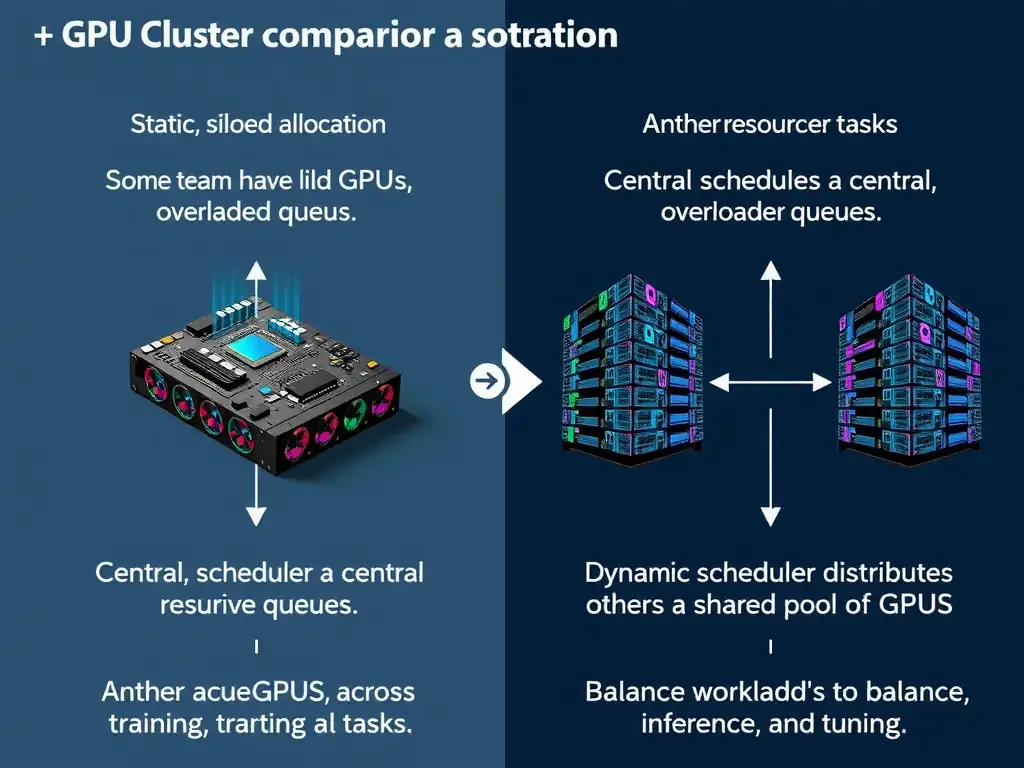
Here's the deal: if you lock your GPUs into fixed team pools, you'll have idle hardware and stuck queues. Configure dynamic GPU resource allocation so the cluster shifts capacity to active workloads in real time. That's how you maximize utilization and keep teams from fighting over scarce GPUs.
Full Explanation
In a multi-tenant AI infrastructure, workload requirements are highly variable. Training deep learning models is compute-intensive and can run for days, while inference tasks require low-latency, intermittent compute, and hyperparameter tuning involves running many small, parallel trials. Dividing the GPU pool into fixed, permanent partitions based on each team's initial estimates leads to resource silos, where some GPUs are over-committed and others sit idle, failing to maximize return on investment. Putting hard limits on the number of concurrent training jobs each team can submit artificially throttles developer productivity instead of optimizing infrastructure. Enforcing a strict policy that prioritizes long-running model training jobs over all low-latency inference requests is impractical because inference directly serves end-users and requires strict SLA compliance. Configuring dynamic GPU resource allocation that adjusts distribution in real time based on active workload demands is the industry best practice. Schedulers, such as Kubernetes with specialized GPU plugins, monitor real-time resource demands and queue lengths, shifting available GPU capacity to where it is needed most. When a training run finishes or inference traffic drops, those resources are instantly reclaimed and given to waiting jobs. This ensures maximum cluster utilization, minimizes idle power waste, and prevents performance bottlenecks across all teams.