
A engineering team is training a large language model across an NVIDIA DGX cluster using distributed data parallel training. During monitoring, they notice poor scaling efficiency: as they add more nodes, the GPUs remain underutilized, and training throughput does not increase linearly. Which of the following issues are the most likely causes of this distributed training bottleneck? (Select two)
Select all correct answers, then click Submit.
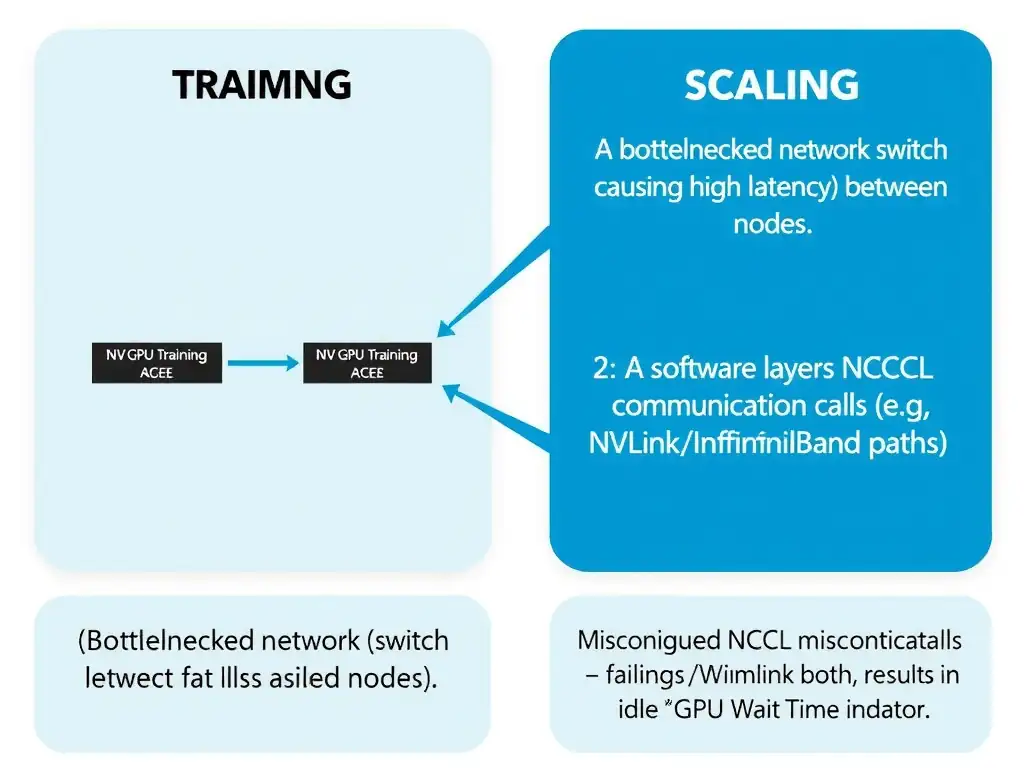
Short Explanation
Check this out: when you scale out to multiple DGX nodes, your GPUs have to talk constantly to share gradients. If the node interconnect is slow or NCCL isn't tuned, the GPUs idle waiting on data instead of computing.
Full Explanation
In DGX clusters, distributed deep learning, particularly with large models, relies heavily on rapid communication between GPUs across different nodes to synchronize gradients, such as during All-Reduce operations. The two most likely causes of poor scaling efficiency are low-bandwidth or high-latency network interconnects between cluster nodes and misconfigured or unoptimized NVIDIA Collective Communications Library (NCCL) operations.
Low-bandwidth or high-latency network interconnects, such as standard 10GbE instead of dedicated high-speed NVIDIA Quantum InfiniBand or RoCE at 100/200/400 Gbps, become severe bottlenecks because nodes must exchange massive amounts of model parameter data. The GPUs then spend significant portions of their time idle waiting for network transfers to complete, which is known as being communication-bound, and this produces low GPU utilization.
NCCL provides multi-GPU and multi-node collective communication primitives, such as All-Gather, All-Reduce, Broadcast, and Reduce, that are highly optimized for NVIDIA GPUs. If NCCL is improperly configured, disabled, or if environment variables such as NCCL_DEBUG, NCCL_IB_DISABLE, or interface selections are misconfigured, the system may fall back to slower communication paths, such as host TCP/IP, which severely increases latency and degrades distributed training scaling.
The issue of configuring incorrect clock speeds of individual CUDA cores on local GPU engines is not likely because CUDA cores cannot be individually configured or misconfigured in terms of physical layouts; their clock speed and performance are managed automatically by the driver and runtime.
Running out of physical VRAM during the forward pass on the primary node would cause an out-of-memory crash during the allocation phase, not poor scaling efficiency or GPU underutilization during execution.
Implementing model tensor parallelism incorrectly across the layers of the neural network can cause performance issues, but standard distributed data parallel training is typically used for cluster scaling, and incorrect parallelism implementation usually results in runtime crashes or incorrect mathematical outputs rather than purely underutilizing communication resources on multi-node runs.