
An enterprise radiology group is deploying a deep learning model for real-time detection of anomalies in CT scans. The primary operational requirements are ultra-low latency and maximum image throughput on their local NVIDIA-powered inference servers. To achieve this, you need to optimize the trained neural network models specifically for the underlying GPU hardware before deploying them. Which NVIDIA software tool is designed specifically to compile, optimize, and run high-performance inference engines?
Select an answer to reveal the explanation.
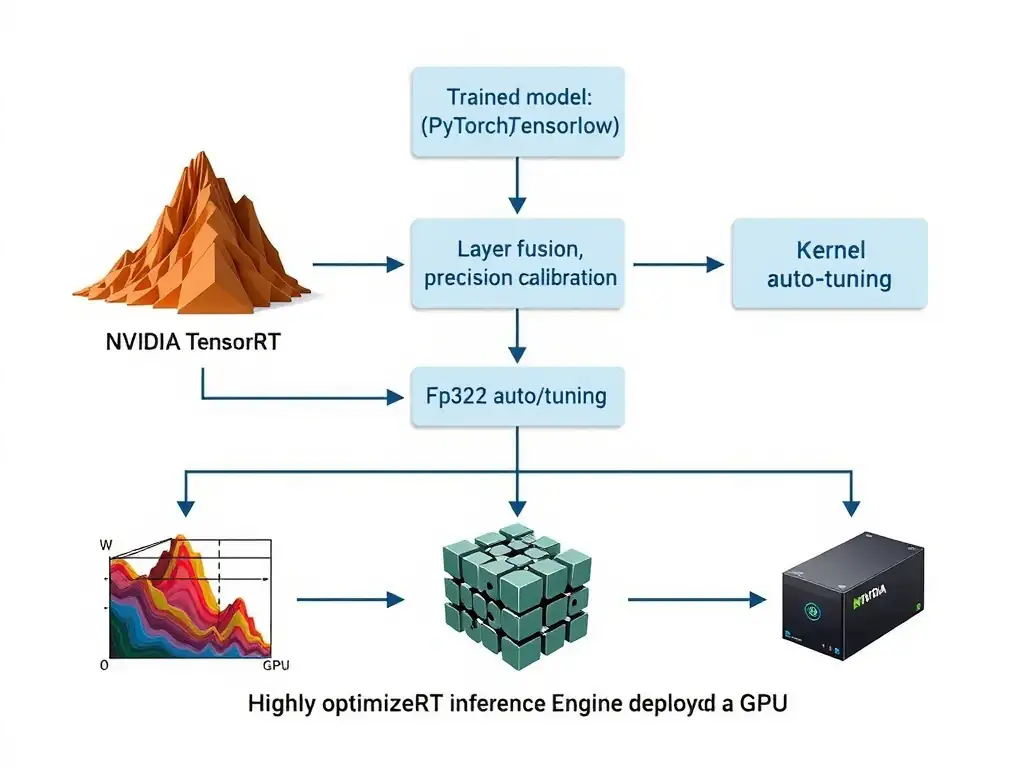
Short Explanation
You need TensorRT because it compiles your trained model into a fast inference engine tuned for NVIDIA GPUs. It fuses layers, calibrates precision, and picks optimized kernels so you get low latency and high throughput. The other tools profile, train, or manage clusters—they don't run optimized inference.
Full Explanation
Deploying deep learning models in production environments requires minimizing inference latency and maximizing throughput. During the training phase, models are typically built with high-precision representations, such as 32-bit floating point, or FP32, and architectures optimized for weight updates. However, for inference, many of these elements can be optimized.
NVIDIA TensorRT is an SDK designed specifically for high-performance deep learning inference. It includes a deep learning inference optimizer and runtime that delivers low latency and high throughput. TensorRT optimizes models by: 1. Layer and Tensor Fusion: Combining nodes in a kernel to minimize GPU memory transfers and launch overhead. 2. Precision Calibration: Quantizing FP32 models to FP16 or INT8 precision while maintaining accuracy, which significantly accelerates execution on Tensor Cores. 3. Kernel Auto-Tuning: Selecting the optimal CUDA kernels based on the target GPU architecture. 4. Dynamic Tensor Memory: Minimizing memory footprint and reusing memory blocks efficiently.
Let's evaluate the incorrect choices: - The system-wide profiling tool NVIDIA Nsight Systems is used to analyze application performance, visualize CPU/GPU thread execution, and identify bottlenecks. It is not an inference optimizer or runtime environment. - The medical imaging training framework NVIDIA Clara Train is tailored for training medical imaging models, not for optimizing general production inference engines. - The infrastructure deployment suite NVIDIA DeepOps uses Ansible and Kubernetes to bootstrap GPU clusters. It manages hardware provisioning, not model compilation or execution optimization.
Therefore, NVIDIA TensorRT is the most appropriate software solution for compiling and optimizing trained models for high-speed production inference.