
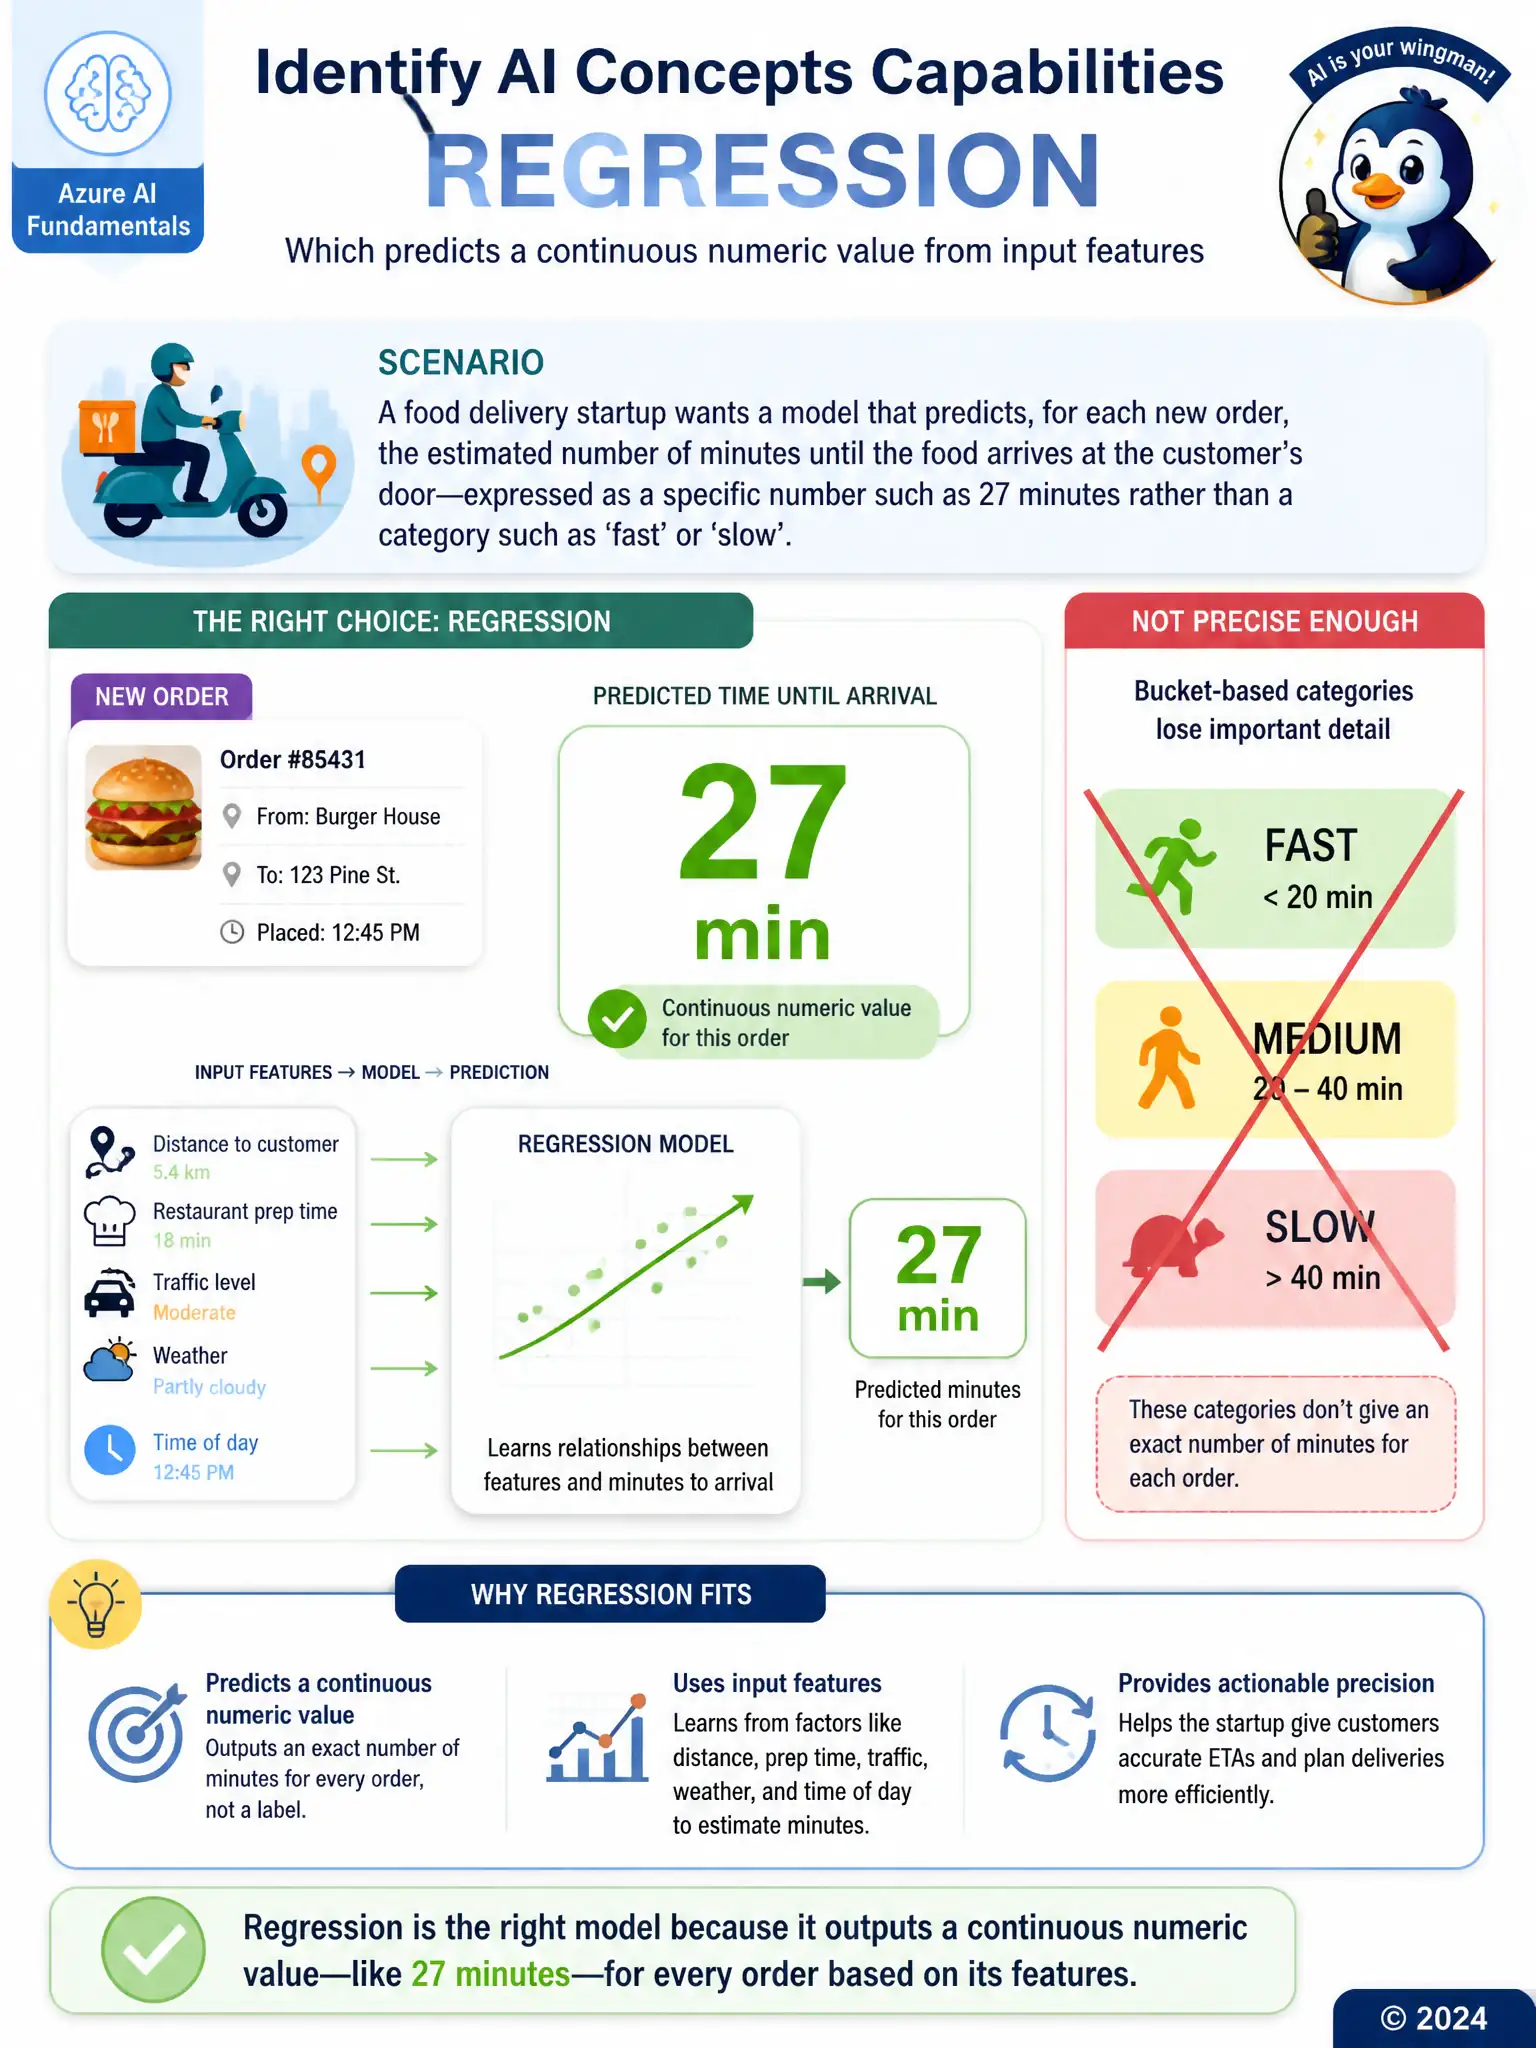
A food delivery startup wants a model that predicts, for each new order, the estimated number of minutes until the food arrives at the customer's door, expressed as a specific number such as 27 minutes rather than a category such as 'fast' or 'slow'. Which type of machine learning model fits this requirement?
Select an answer to reveal the explanation.
Short Explanation
The giveaway is the answer shape: you need an exact minute count, not a bucket like 'fast' or 'slow'. That's regression, because it predicts a continuous numeric value from each order's details. Bucketing, clustering, and outlier flagging don't give you that per-order number.
Full Explanation
The correct answer is regression. The startup wants a specific numeric estimate, such as 27 minutes, rather than a label chosen from a fixed set, and predicting a continuous numeric value from input features is exactly what a regression model is built to do. The classification approach is incorrect because it would assign each order to one of a predefined set of discrete buckets, such as 'fast' or 'slow', which loses the precision of an exact minute count that the startup explicitly wants. The clustering approach is incorrect because it groups similar orders together based on shared characteristics, but it has no target value to predict at all, and grouping orders into segments would not tell a customer how many minutes to expect. The anomaly detection approach is incorrect because it is built to flag orders that fall outside a typical pattern for review, which addresses outlier detection, not the routine task of estimating a delivery time for every order. Because the requirement is a precise numeric prediction for every order, regression is the model type that fits.