
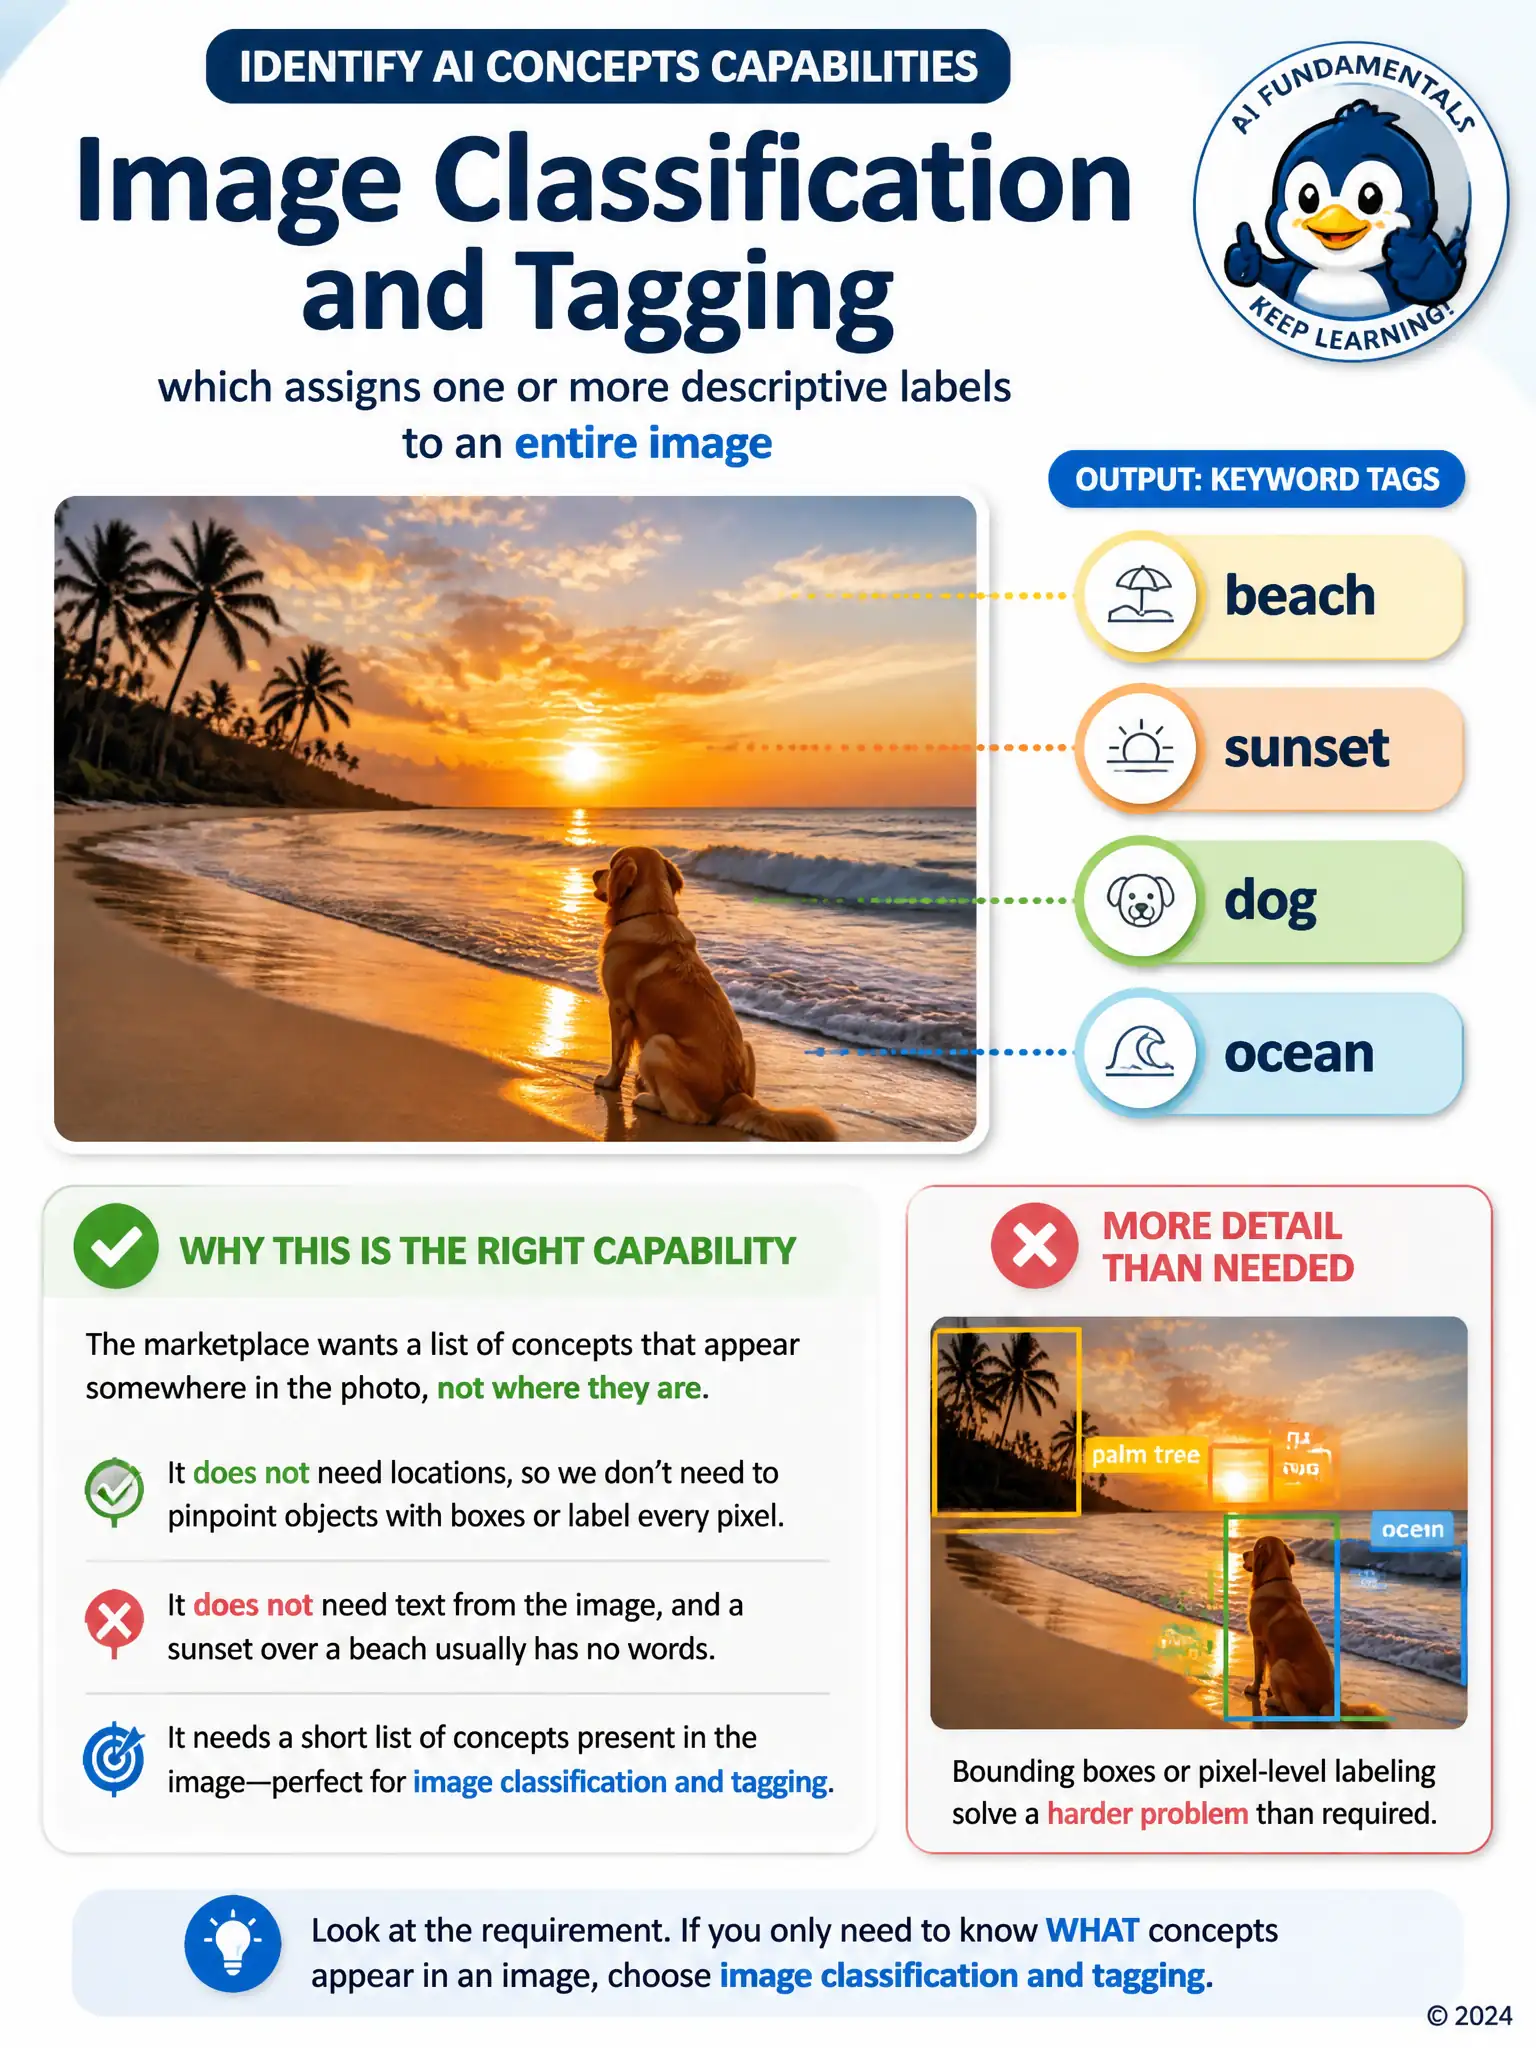
A stock-photography marketplace wants to automatically generate a list of descriptive keywords for each uploaded photo, such as 'beach', 'sunset', and 'dog', so customers can find the photo through keyword search. The marketplace does not need to know where each object sits within the frame, only which concepts appear somewhere in the image. Which AI capability best fits this requirement?
Select an answer to reveal the explanation.
Short Explanation
Pay attention to what the marketplace says it doesn't need: it doesn't care where the dog is, only that a dog appears. That rules out capabilities whose point is pinpointing location or reading text. What you need is the capability that looks at the whole photo and hands back a short list of concepts, which is exactly the searchable keyword list.
Full Explanation
Image classification and tagging is designed to look at an entire photo and return one or more descriptive labels for what it contains, matching the marketplace's need for keyword tags without any spatial information. The object detection approach is incorrect because it would draw a bounding box around every dog or every umbrella instead of simply listing that a dog and an umbrella appear somewhere in the photo, which is more information than the marketplace asked for and a different output shape entirely. The image segmentation approach is incorrect because it classifies every pixel in the photo, producing a detailed pixel map rather than a short list of searchable keywords, which is far more granular than the tagging use case requires. The optical character recognition approach is incorrect because it reads printed or handwritten text within an image, such as a sign or label, but it does nothing to identify visual concepts like a beach or a sunset that contain no text at all. The marketplace's stated need, whole-image descriptive tags with no location data, points directly to image classification and tagging.