
A job-search platform wants to match resumes to job postings based on overall meaning rather than exact keyword overlap, so that a resume mentioning 'led a team of developers' matches a posting asking for 'engineering management experience' even though the wording is different. Which Foundry capability should the team use to build this matching feature?
Select an answer to reveal the explanation.
Short Explanation
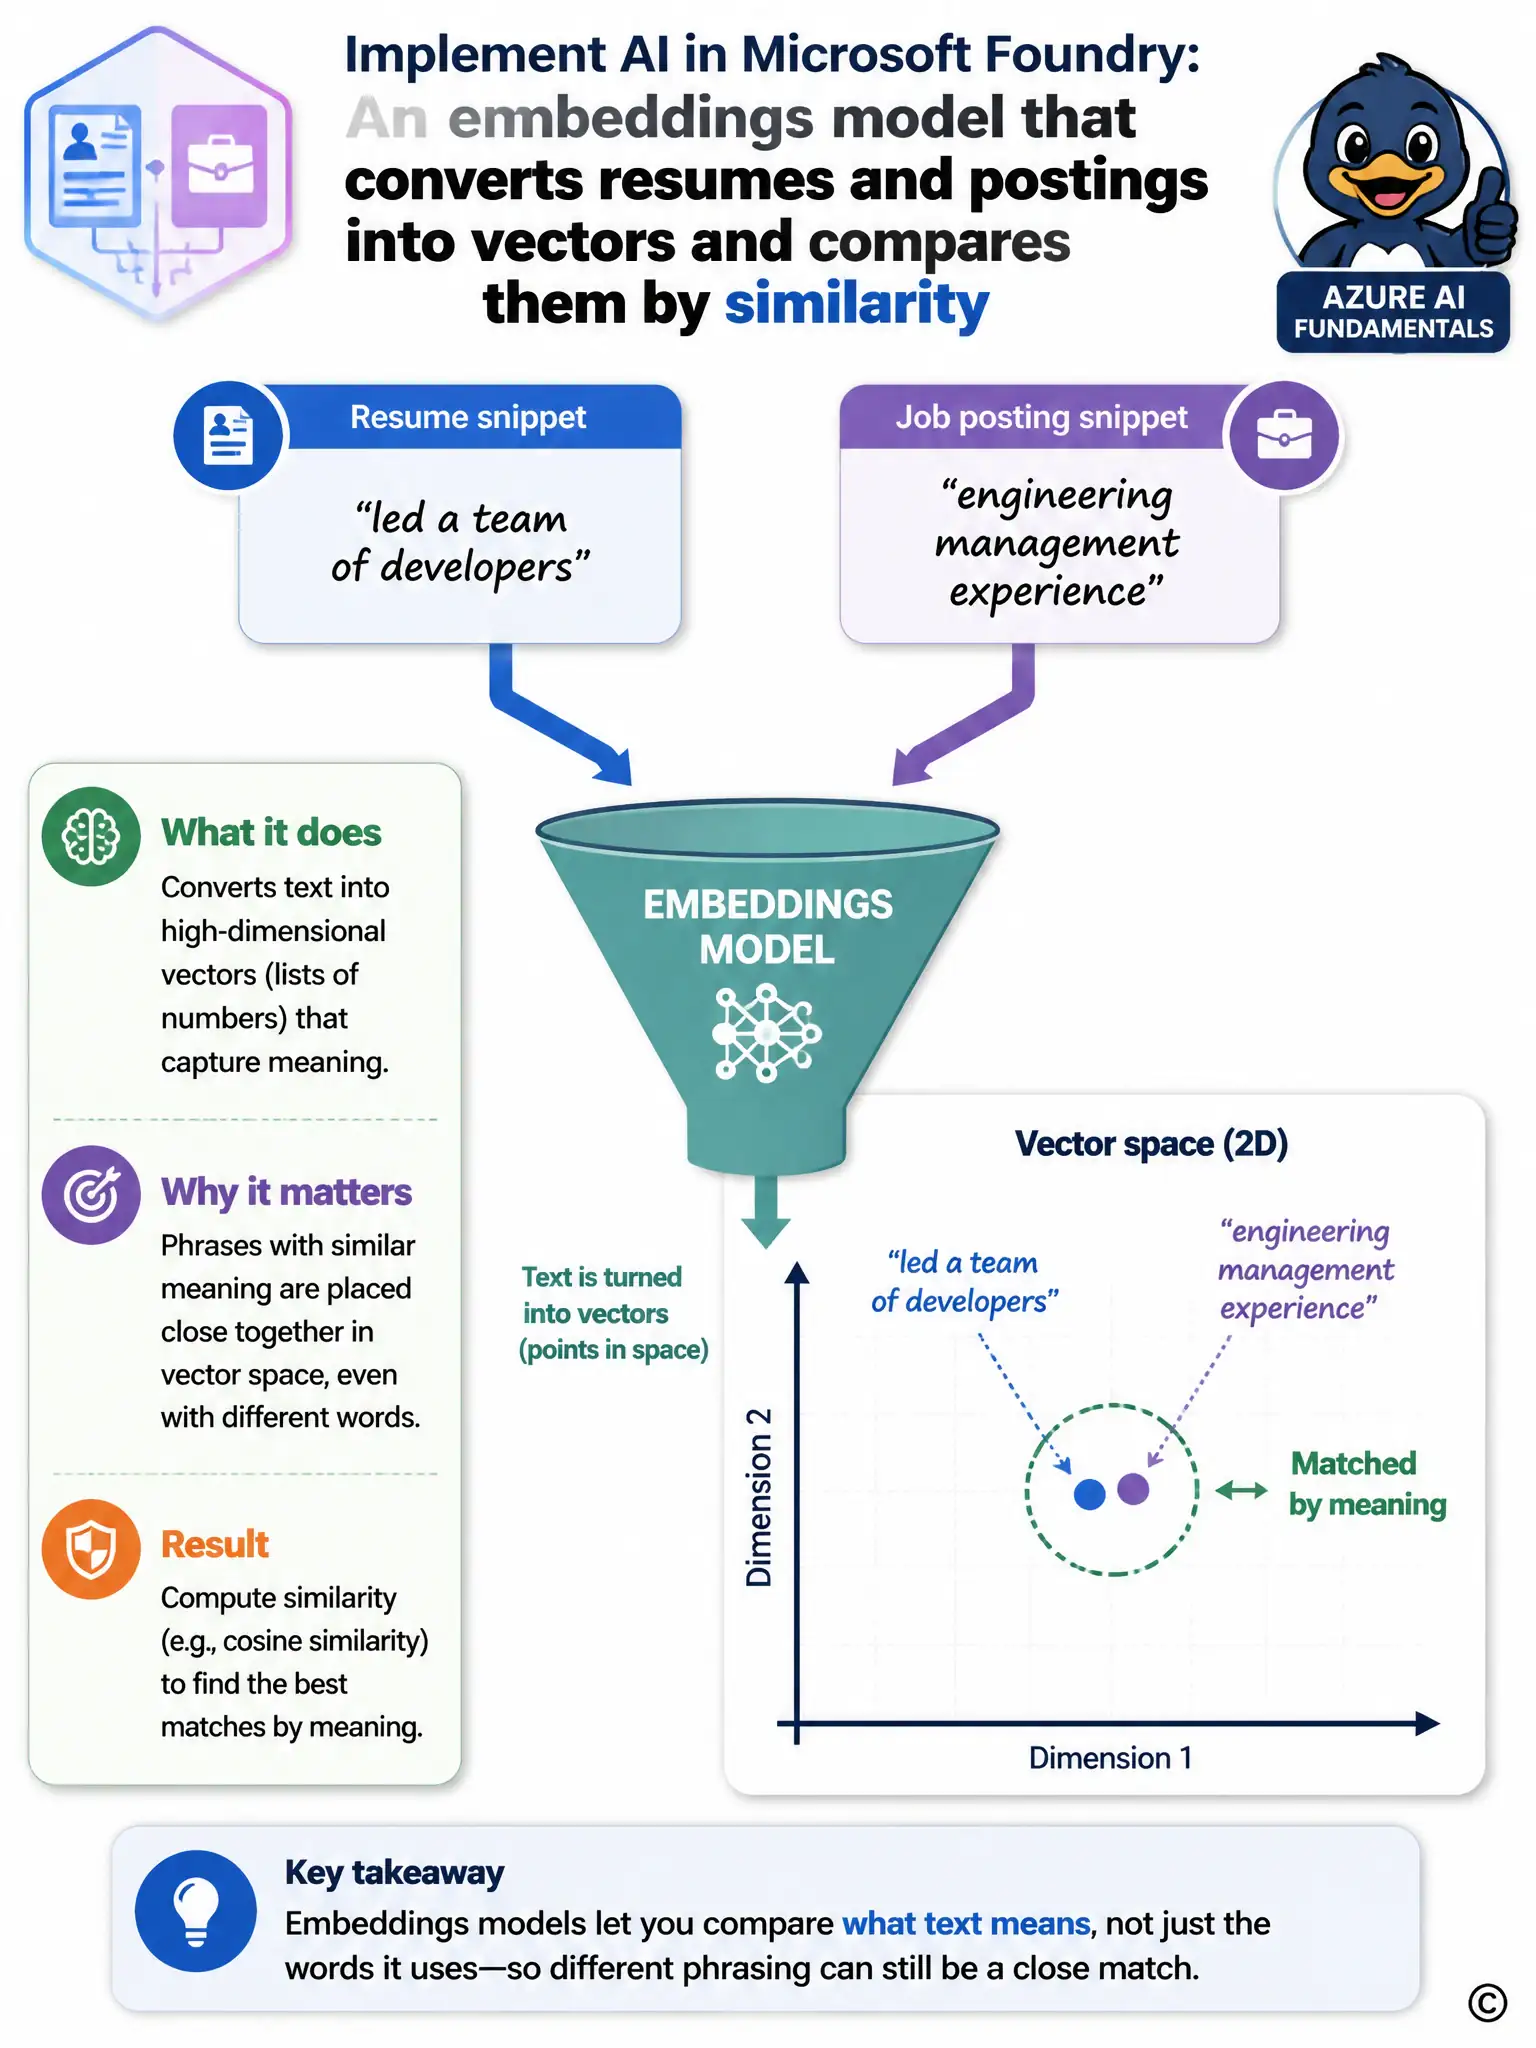
You need a way to compare meaning, not exact words. An embeddings model turns each resume and posting into vectors, so 'led a team of developers' and 'engineering management experience' land close together even with different wording. That's the capability that powers semantic matching.
Full Explanation
The embeddings model option is correct because it converts each resume and posting into a numeric vector that captures its meaning, so texts with different wording but similar intent, such as 'led a team of developers' and 'engineering management experience,' end up close together in vector space and can be matched by similarity rather than by shared keywords. The text-to-speech model option is incorrect because it converts written text into audio for accessibility purposes; it has no role in comparing the meaning of two pieces of text and would not help match resumes to postings at all. The larger context window option is incorrect because it only changes how much text a chat model can process in a single request; it does not give the system a way to numerically compare meaning across two separate documents, which is what matching requires. The stricter content filter option is incorrect because content filtering is a safety control for detecting harmful or biased content, not a mechanism for measuring semantic similarity, so applying it would not help the platform find resumes that mean the same thing as a posting even when the wording differs. Embeddings are purpose-built for exactly this kind of meaning-based comparison, which is why they fit the matching requirement described.