
A platform aimed at teenagers hosts a Foundry-powered writing assistant that helps users draft short fiction. The moderation team wants to strictly block sexual content and self-harm content at the lowest severity threshold, while still allowing mild fictional violence such as a sword fight in an adventure story to pass through. Which content safety configuration approach fits this requirement?
Select an answer to reveal the explanation.
Short Explanation
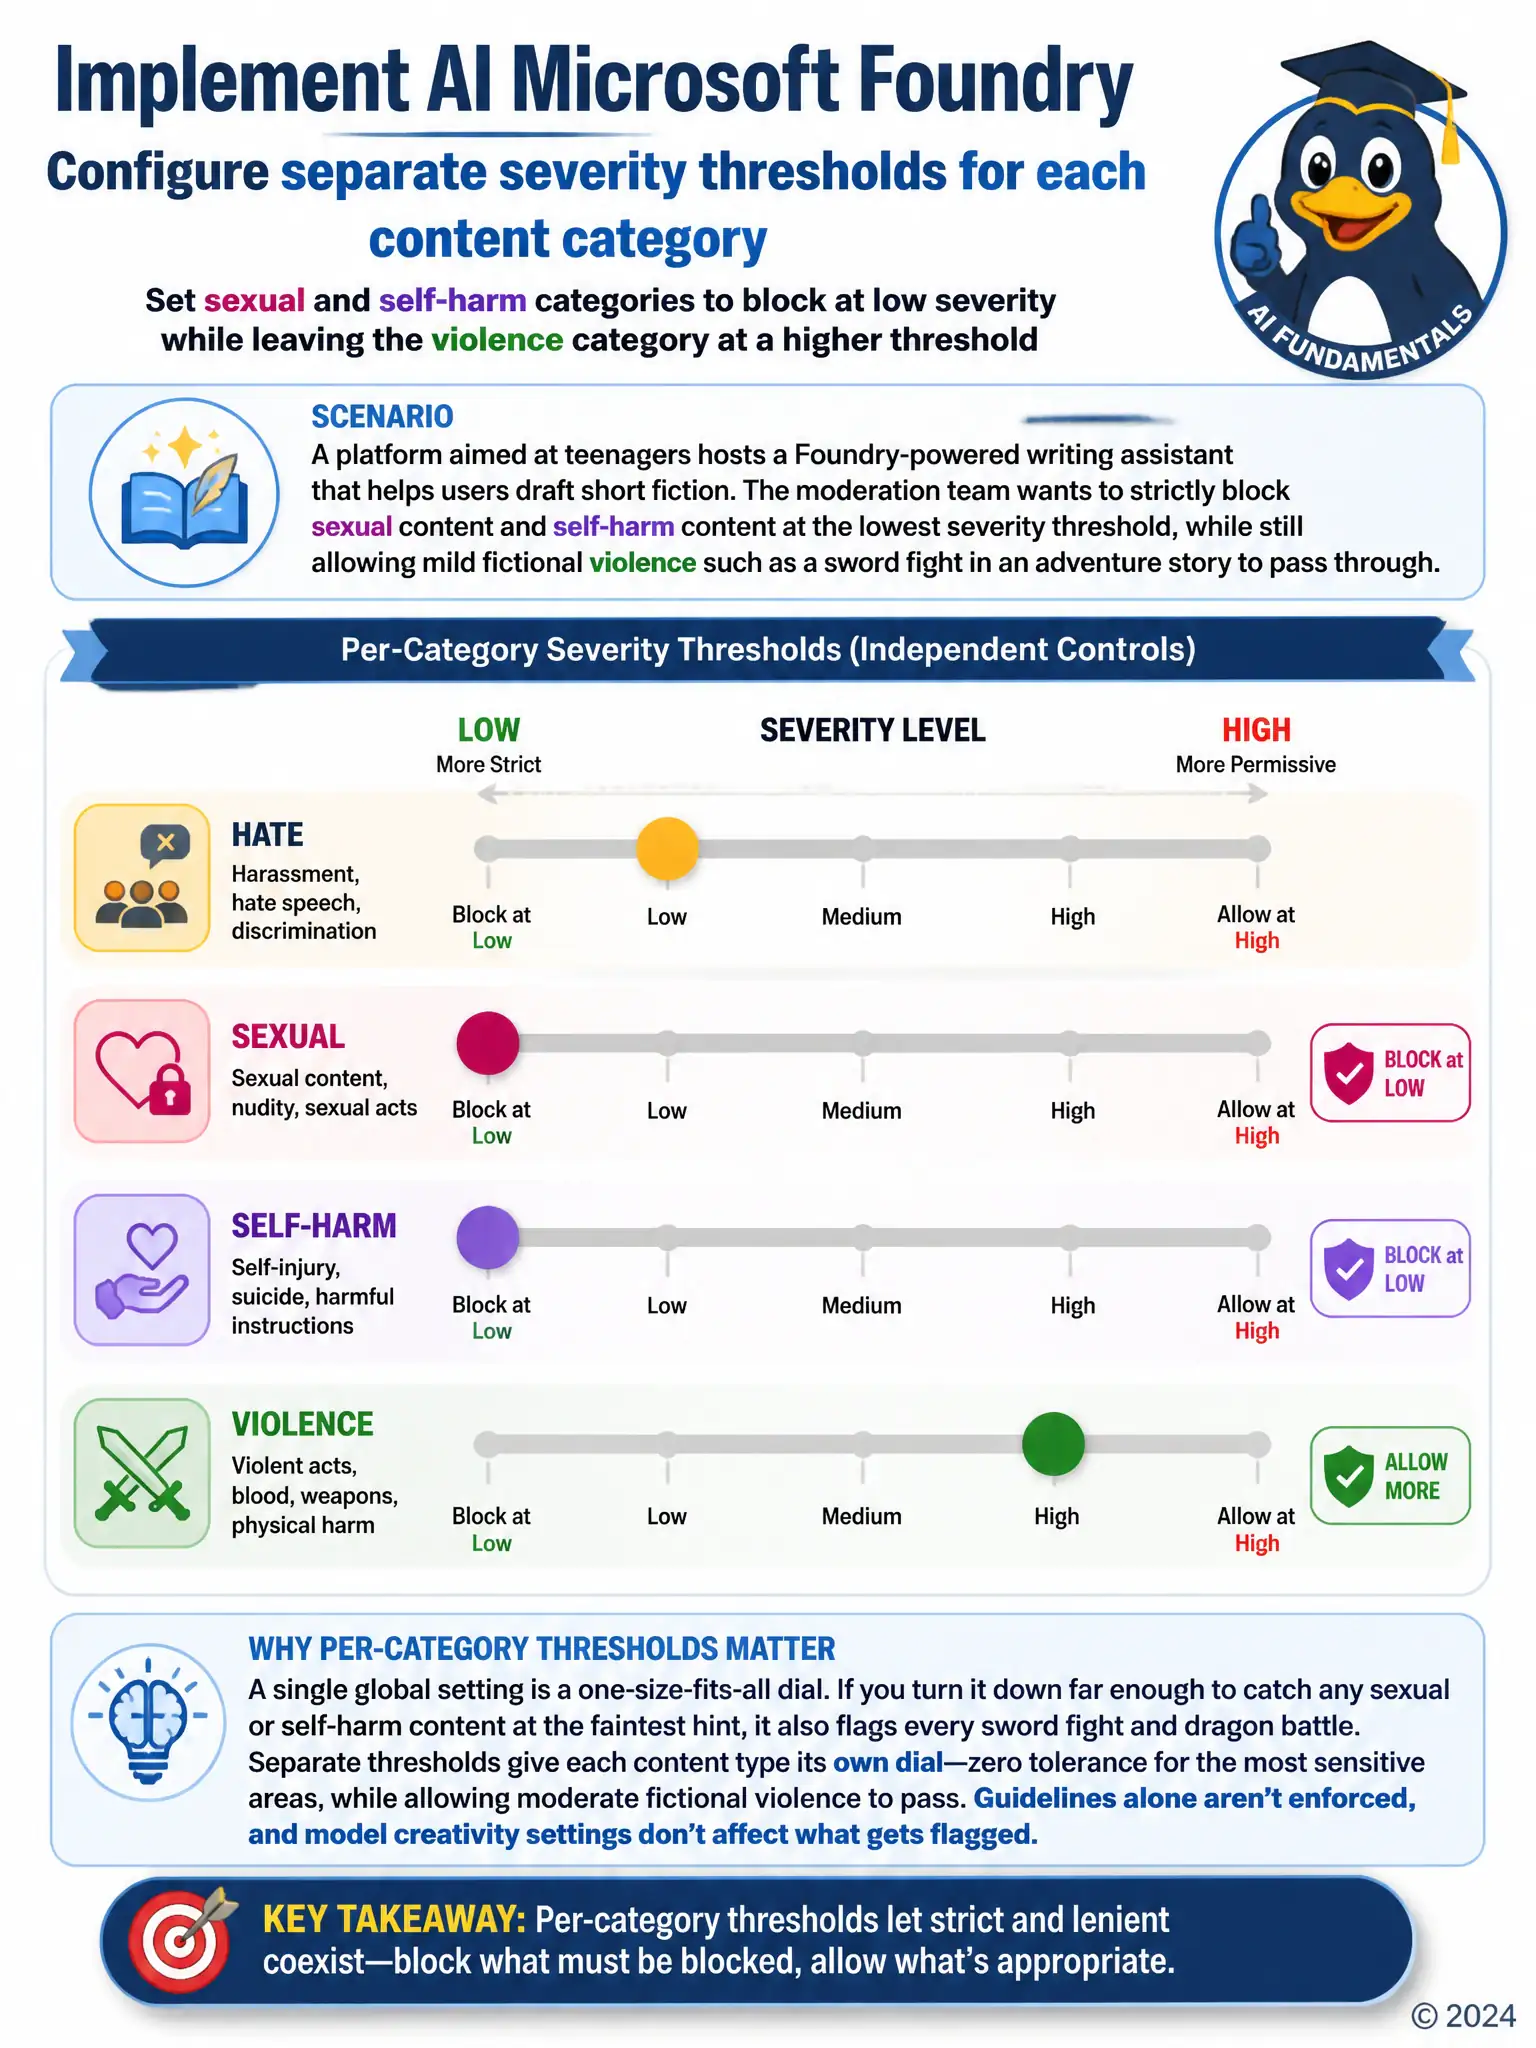
You need separate severity thresholds for each content category. That lets you block sexual and self-harm content at the lowest severity while still letting mild fictional violence through. One global setting can't give strict and lenient rules at the same time.
Full Explanation
The correct approach is to configure separate severity thresholds for each content category, setting sexual and self-harm categories to block at low severity while leaving the violence category at a higher threshold. Azure AI Foundry's content safety filtering lets a team set independent severity thresholds per category, such as hate, sexual, self-harm, and violence, so the moderation team can strictly block sexual and self-harm content at low severity while still permitting the milder violence typical of adventure fiction, which a single blanket setting cannot do. The single global content safety toggle is incorrect because it applies the same threshold to every category at once, meaning any setting strict enough to catch sexual or self-harm content at low severity would also block the mild fictional violence the team wants to allow. Removing the content safety filter entirely and relying on the writing assistant's system message to discourage inappropriate topics is incorrect because it leaves the assistant with no enforced technical safeguard; a system message is an instruction the model may not always follow, especially under adversarial or unusual prompts, so it cannot substitute for a moderation layer. Setting the model's temperature to zero so it only generates the most predictable, safest word choices is incorrect because temperature controls the randomness of word choice, not the detection or blocking of harmful content categories; a model with temperature set to zero can still generate sexual or self-harm content if nothing is filtering for it. Per-category thresholds are the tool designed for exactly this mixed tolerance.