
A logistics company's Foundry-hosted assistant now handles 200,000 customer support conversations per day with a contractual requirement of consistent sub-second response times during peak hours. The pay-as-you-go deployment occasionally throttles requests when traffic spikes, causing missed SLA targets. What should the team do to meet the latency guarantee?
Select an answer to reveal the explanation.
Short Explanation
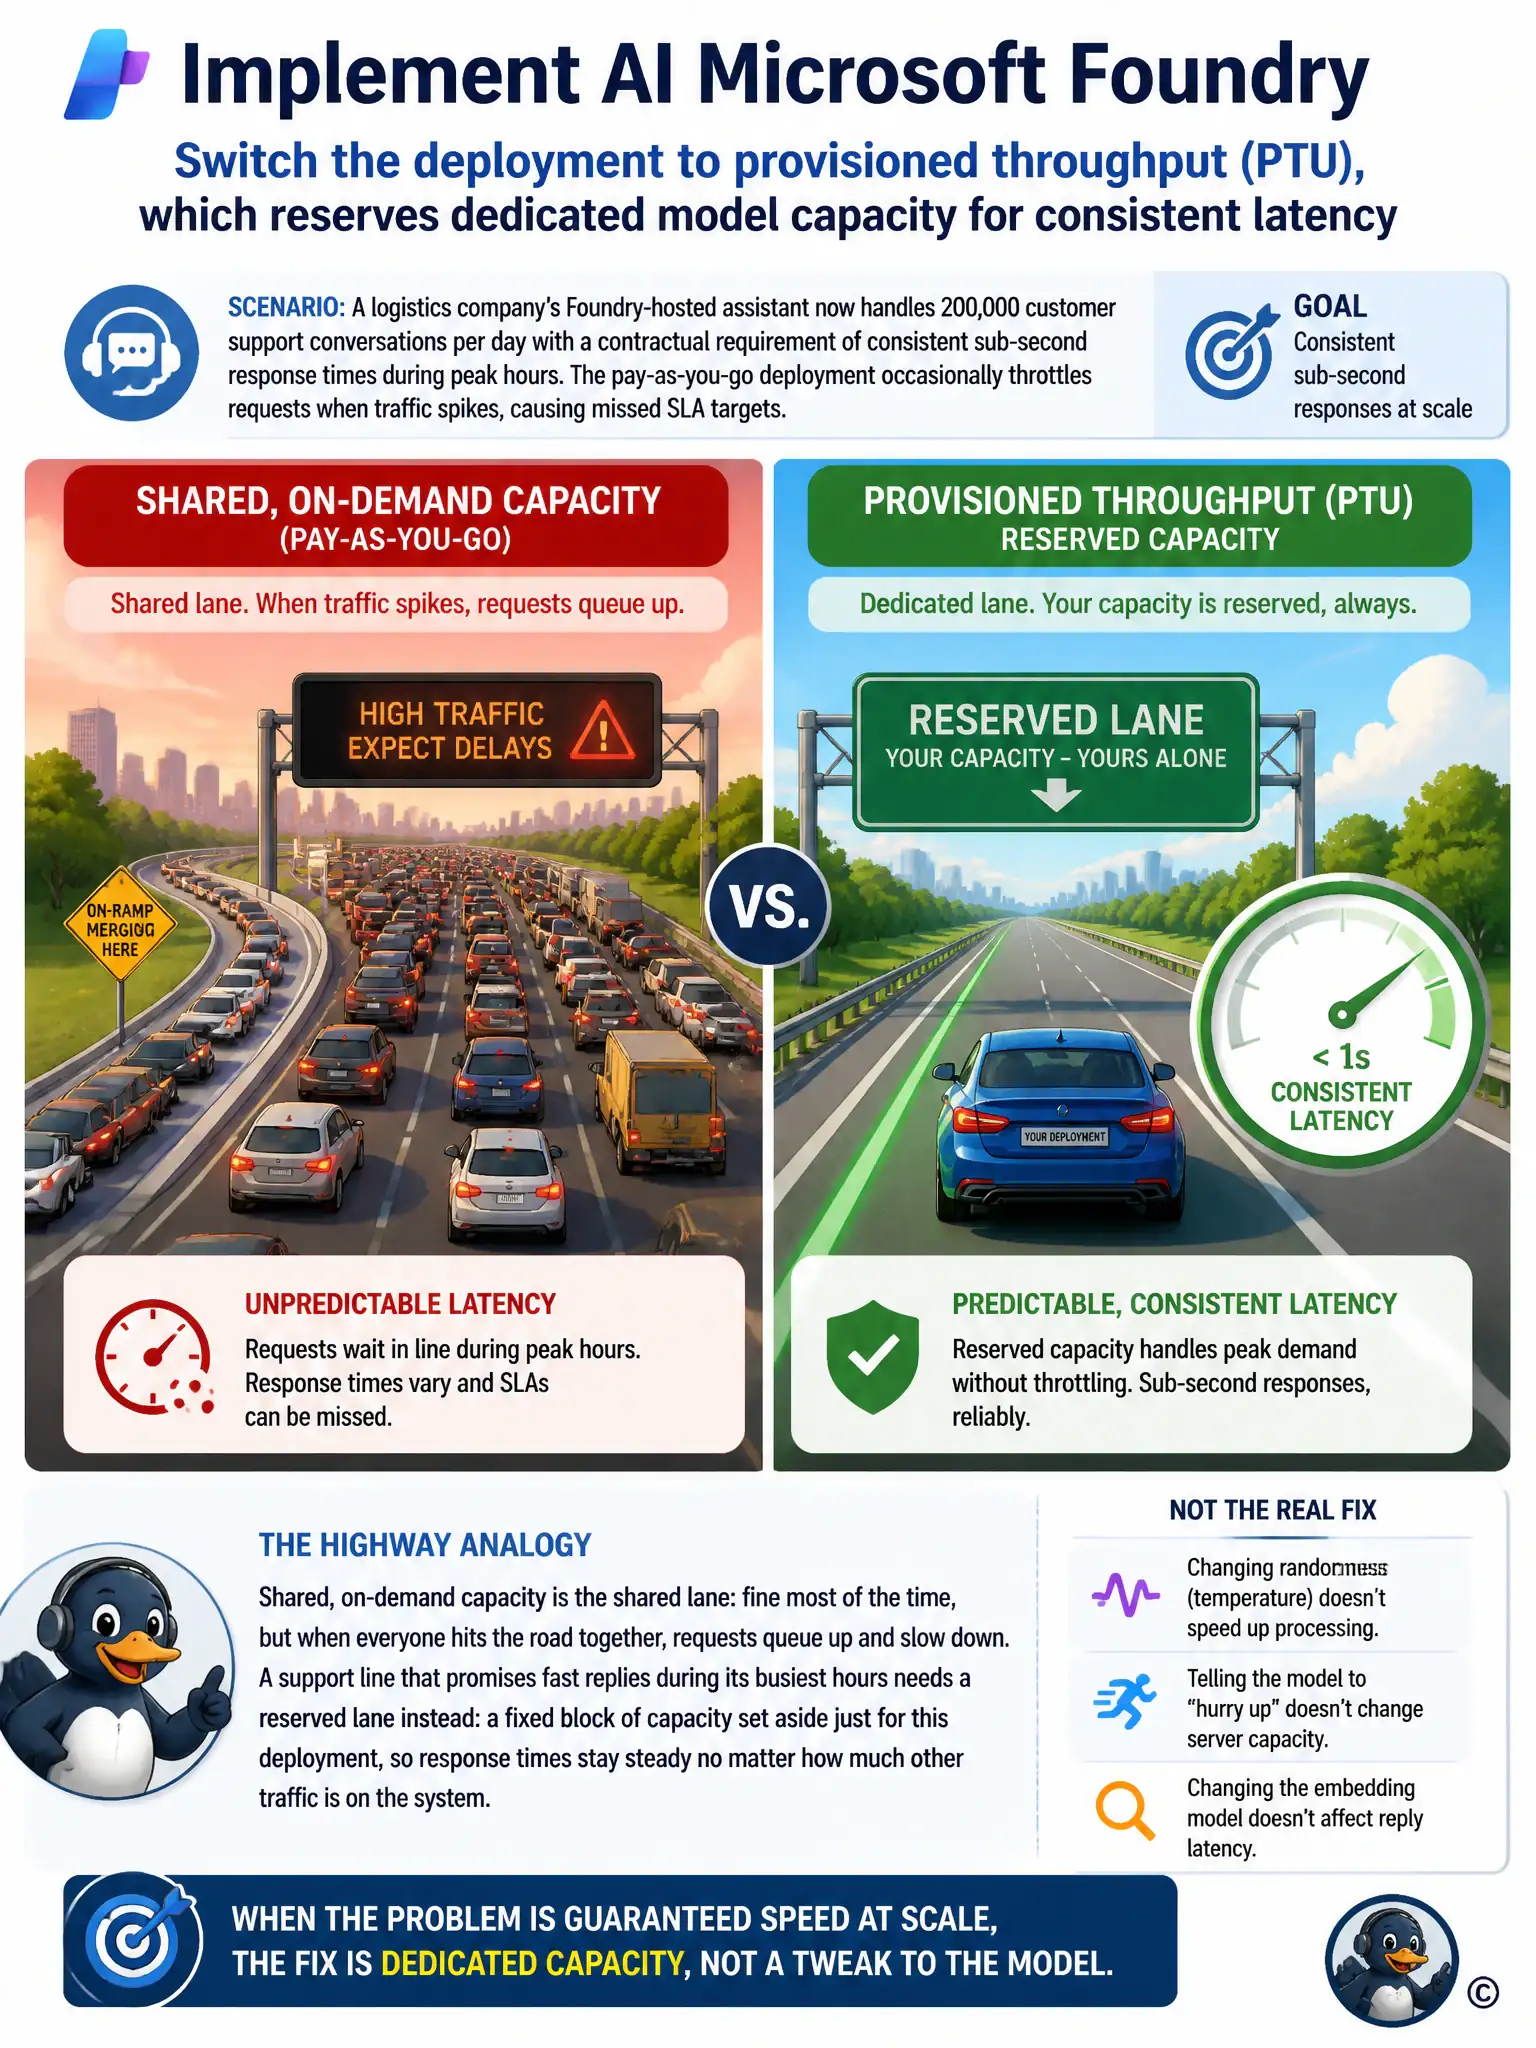
You need dedicated capacity, not a behavior tweak. Switching to provisioned throughput reserves model capacity so your assistant can keep sub-second responses during peak spikes. Shared pay-as-you-go traffic is the bottleneck, so it throttles when everyone hits it at once.
Full Explanation
The option that switches the deployment to provisioned throughput (PTU) is correct because PTU reserves dedicated compute capacity for a Foundry deployment, so the logistics company's assistant gets predictable, guaranteed latency and throughput even during the busiest hours, which is exactly what an SLA for sub-second response times demands. Pay-as-you-go capacity is shared and best-effort, which explains the throttling the team is already seeing under peak load. The option suggesting a lower model temperature is incorrect because temperature controls how random or varied the model's word choices are, not how much compute a request consumes; lowering it does not reduce processing time or prevent throttling. The option recommending a longer system message telling the model to answer faster is incorrect because a system message shapes the content and tone of a response, but it cannot change the underlying infrastructure capacity allocated to the deployment, so it has no effect on throughput limits. The option recommending a smaller embedding model is incorrect because embedding models are used for search and similarity tasks, not for generating the chat responses described here, and swapping the embedding model would do nothing to address latency in the conversational assistant itself. Provisioned throughput is the mechanism built specifically to guarantee capacity.