
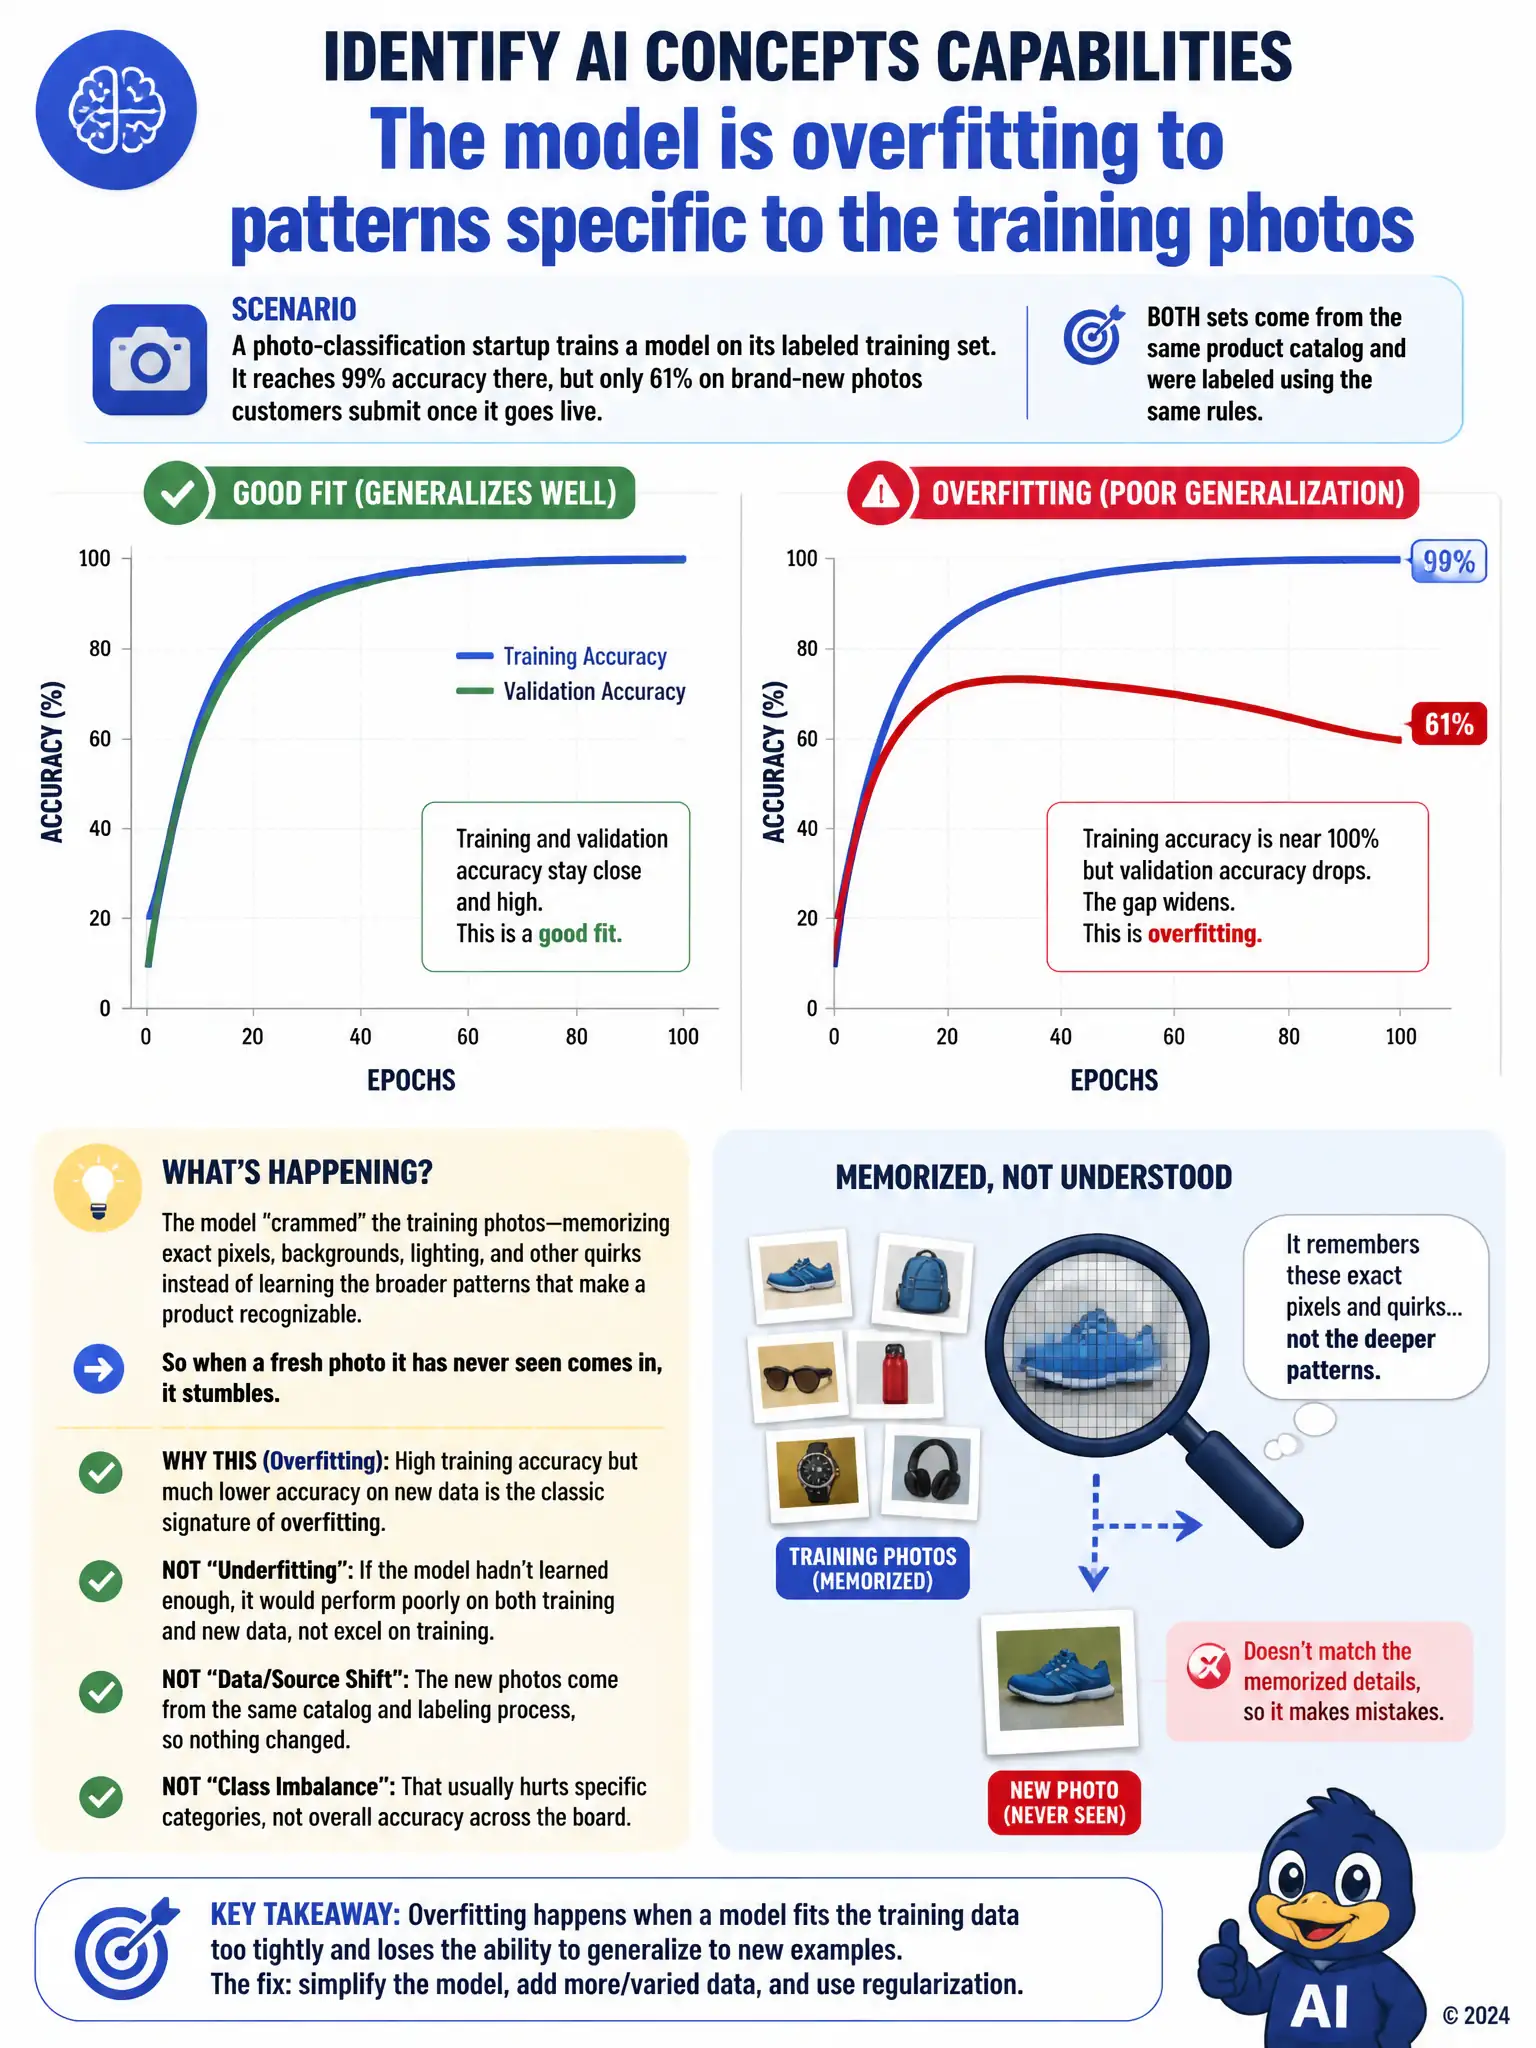
A photo-classification startup trains a model on its labeled training set and it reaches 99 percent accuracy there, but the same model correctly labels only 61 percent of brand-new photos customers submit once it goes live. The live photos come from the same product catalog and were labeled using the same rules as the training set. Which concept best explains the gap between training and live performance?
Select an answer to reveal the explanation.
Short Explanation
This is a model that crammed for the test instead of actually learning the material. You got 99 percent on the training photos because it memorized their quirks, not the broader patterns, so it stumbles on fresh photos. The gap comes from overfitting to patterns specific to the training photos.
Full Explanation
The correct answer is the overfitting explanation: a model that scores 99 percent on the data it was trained on but drops sharply on new, similarly-sourced data has memorized quirks of the training photos rather than learning patterns that generalize, which is the definition of overfitting. The underfitting explanation is incorrect because underfitting produces low accuracy on the training data itself, not the 99 percent score described here; an underfit model has not learned enough to do well anywhere. The data-drift explanation is incorrect because data drift refers to the incoming data's characteristics changing over time or across sources, but the stem states the live photos come from the same catalog and are labeled the same way, so there is no evidence the source shifted. The class-imbalance explanation is incorrect because class imbalance describes an uneven number of examples per category in the training set, which typically shows up as poor performance on the rare categories specifically, not as a broad gap between training and live accuracy across the board.