
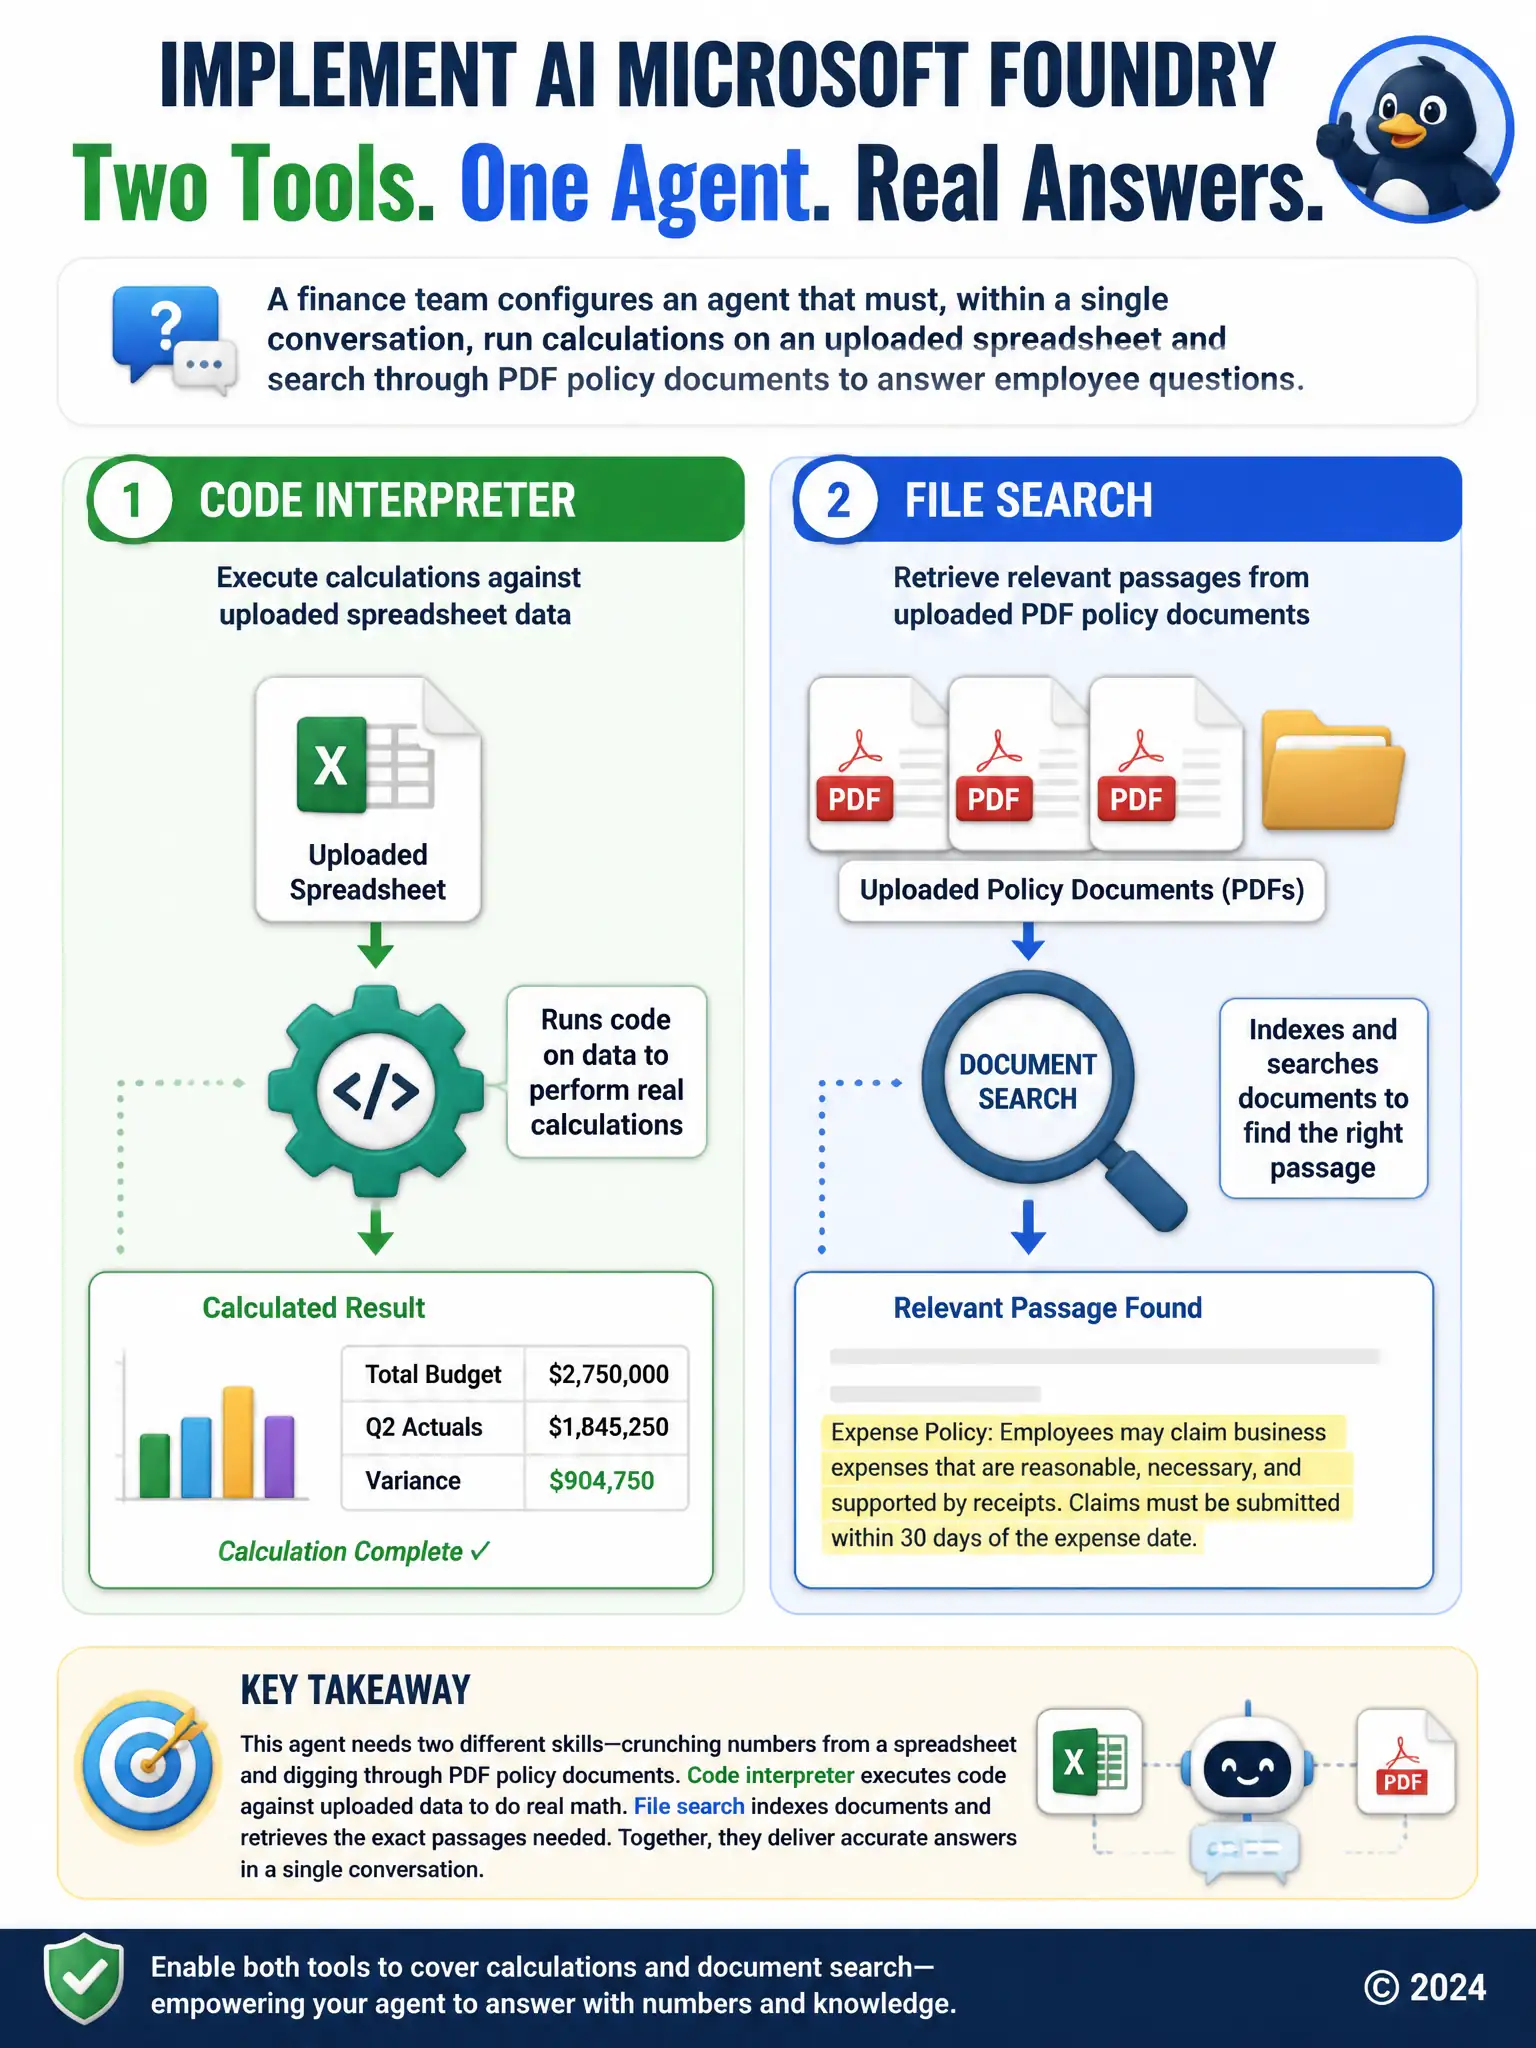
A finance team is configuring an agent in Microsoft Foundry that must, within a single conversation, run calculations on an uploaded spreadsheet and also search through a folder of uploaded PDF policy documents to answer employee questions. (Select TWO.) Which two built-in agent tools should they enable to support these two needs?
Select all correct answers, then click Submit.
Short Explanation
You need two built-in tools working together: code interpreter to run real calculations against uploaded spreadsheet data, and file search to find relevant passages in uploaded PDF policy documents. Content safety filtering doesn't translate documents, and the model catalog doesn't run calculations.
Full Explanation
The correct answers are the code interpreter tool and the file search tool. Code interpreter is the built-in agent tool designed to execute code against uploaded files such as a spreadsheet, which covers the team's need to run calculations on the uploaded data within the conversation. File search is the built-in tool designed to index and retrieve relevant passages from uploaded documents such as PDFs, which covers the team's need to answer questions grounded in the policy documents. The content safety filtering option, described as translating PDF documents into another language, is incorrect because content safety filtering screens content for harm categories like hate or violence; it has no translation function and would not help retrieve or search PDF content. The model catalog option, described as running spreadsheet calculations directly inside the catalog interface, is incorrect because the model catalog is a browsing and comparison interface for selecting which model to deploy; it does not execute calculations or run any computation against uploaded files, and that execution happens through the code interpreter tool once an agent is configured. Together, code interpreter and file search give the agent the two distinct capabilities the finance team needs in one conversation: real computation on structured data and grounded retrieval from unstructured documents, each handled by the tool purpose-built for that job.