
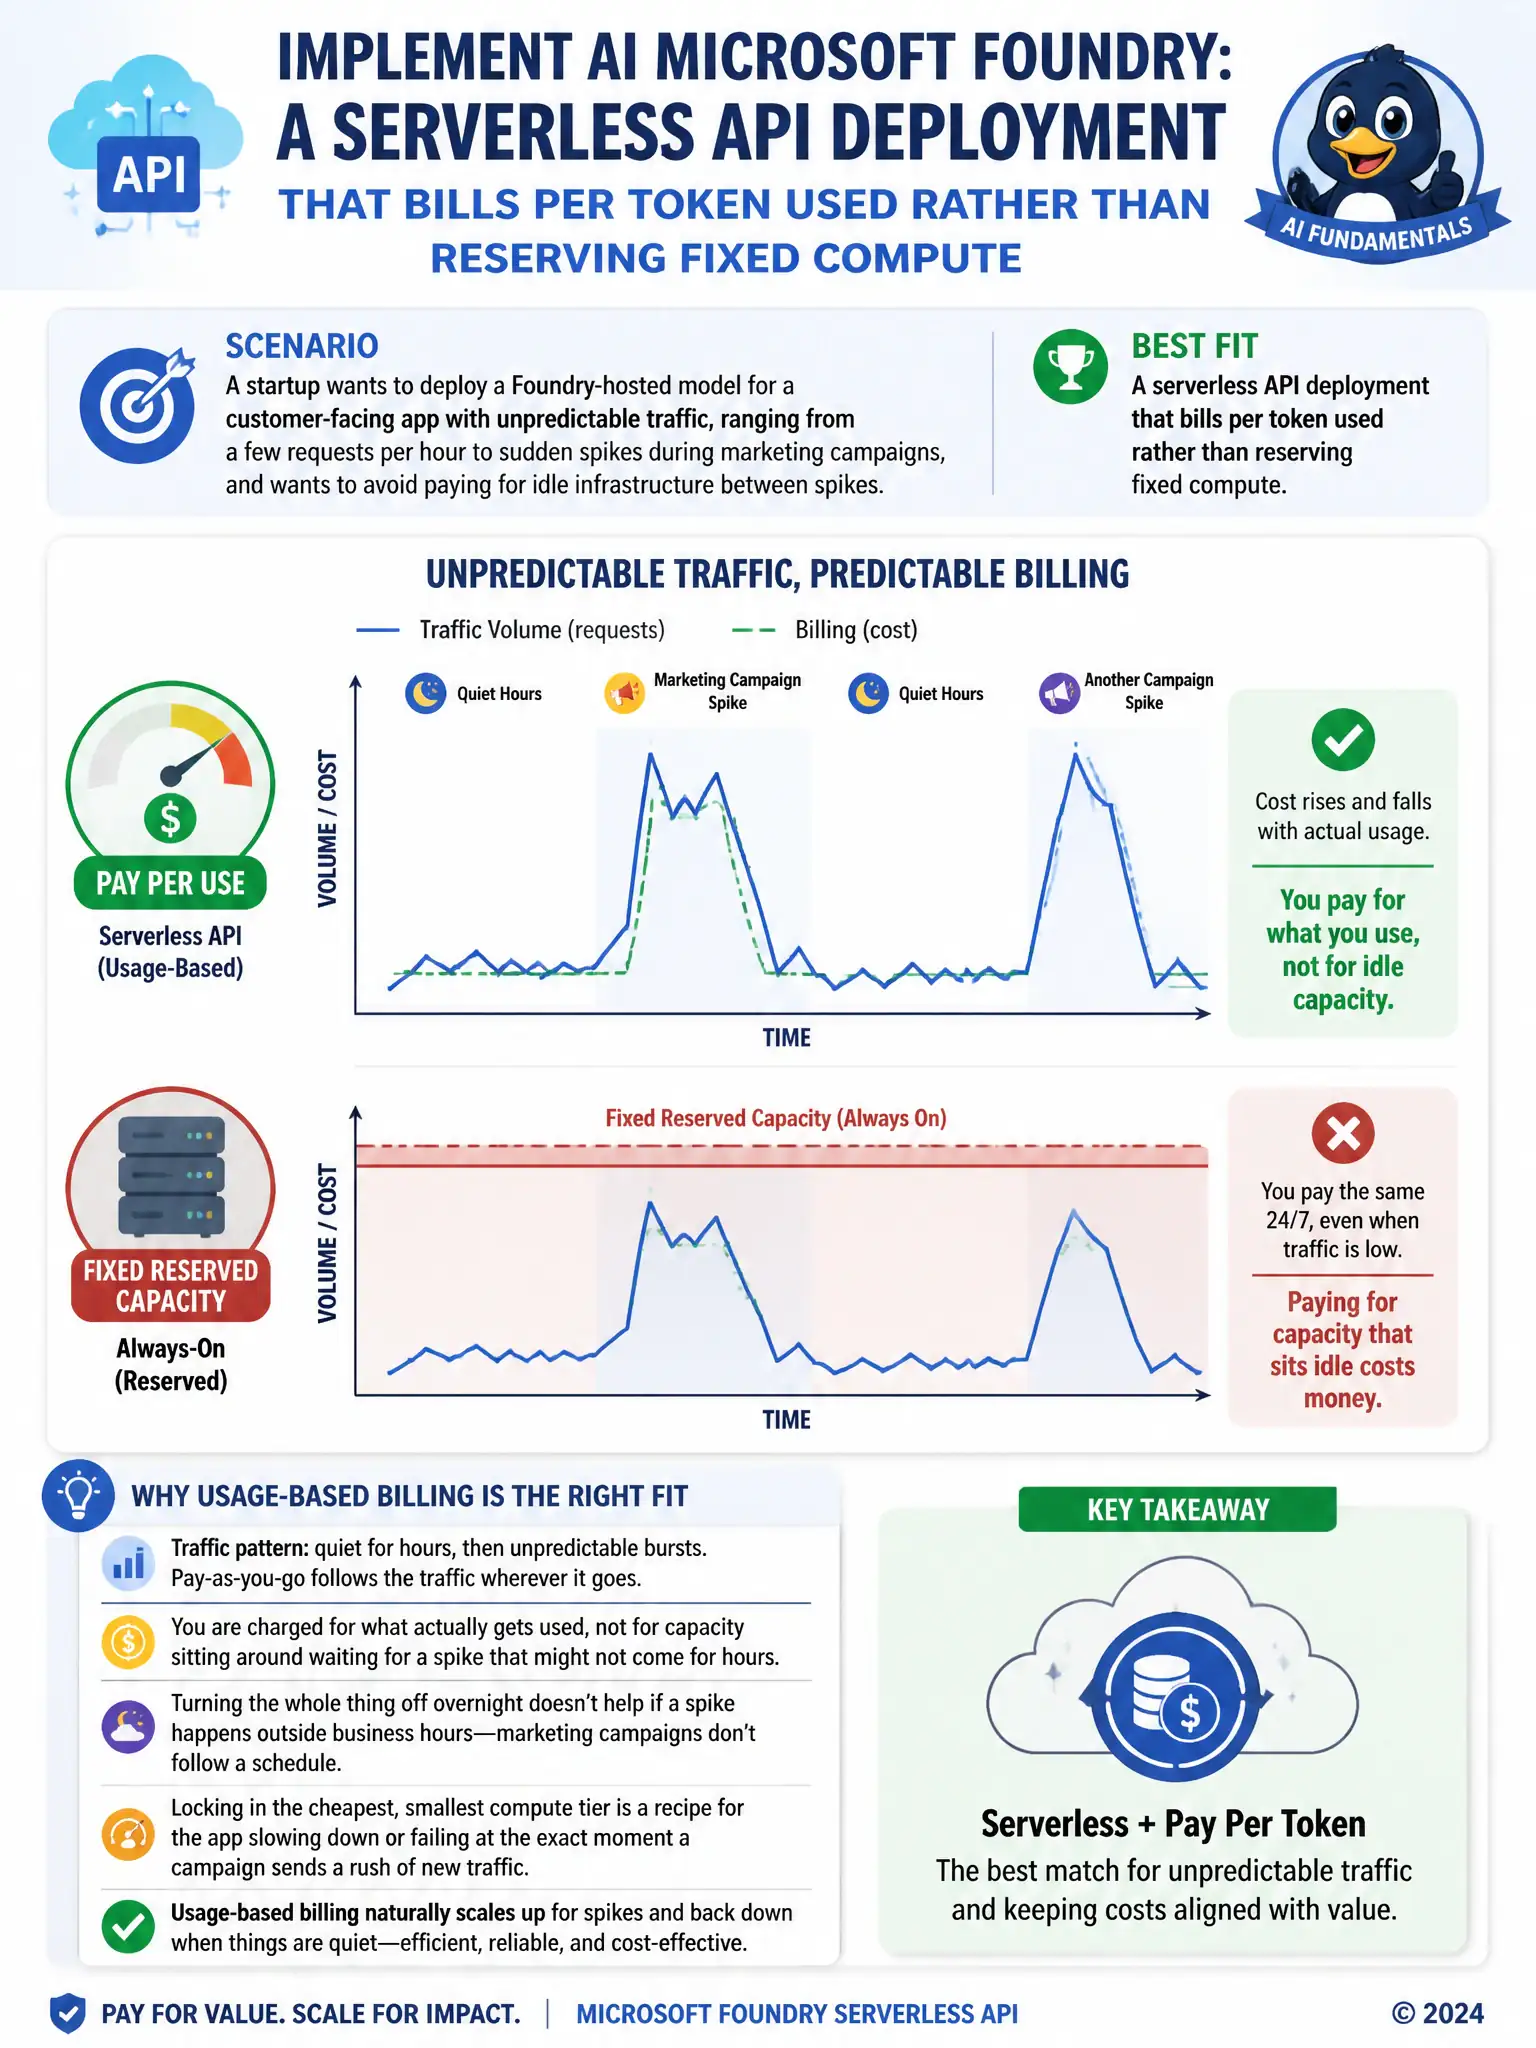
A startup wants to deploy a Foundry-hosted model for a customer-facing app with unpredictable traffic, ranging from a few requests per hour to sudden spikes during marketing campaigns, and wants to avoid paying for idle infrastructure between spikes. Which deployment option best fits this pattern?
Select an answer to reveal the explanation.
Short Explanation
You've got quiet stretches followed by sudden campaign bursts, so you want to pay for what actually gets used. A serverless API deployment that bills per token used fits because it scales with traffic instead of charging for idle capacity.
Full Explanation
The correct answer is a serverless API deployment that bills per token used rather than reserving fixed compute. This deployment model bills based on actual token usage rather than requiring a reserved block of compute, which matches a workload that swings from a handful of requests per hour to sudden campaign-driven spikes without the team paying for capacity that sits idle most of the time. The managed compute deployment sized for peak campaign traffic and left running continuously is incorrect because it means paying for peak-level capacity even during the many quiet hours, which is the opposite of the cost efficiency the startup wants. Deploying the model only during business hours and shutting it down every night manually is incorrect because it does not solve unpredictable within-day spikes, and marketing campaigns are not guaranteed to align with business hours, so real traffic could arrive while the service is off. The single-instance deployment fixed at the lowest available compute tier regardless of traffic is incorrect because it will not handle sudden spikes in demand and risks slow responses or failures during exactly the moments, campaign launches, when reliable performance matters most. Serverless billing tied to actual usage is the option that scales automatically with the unpredictable pattern described.