
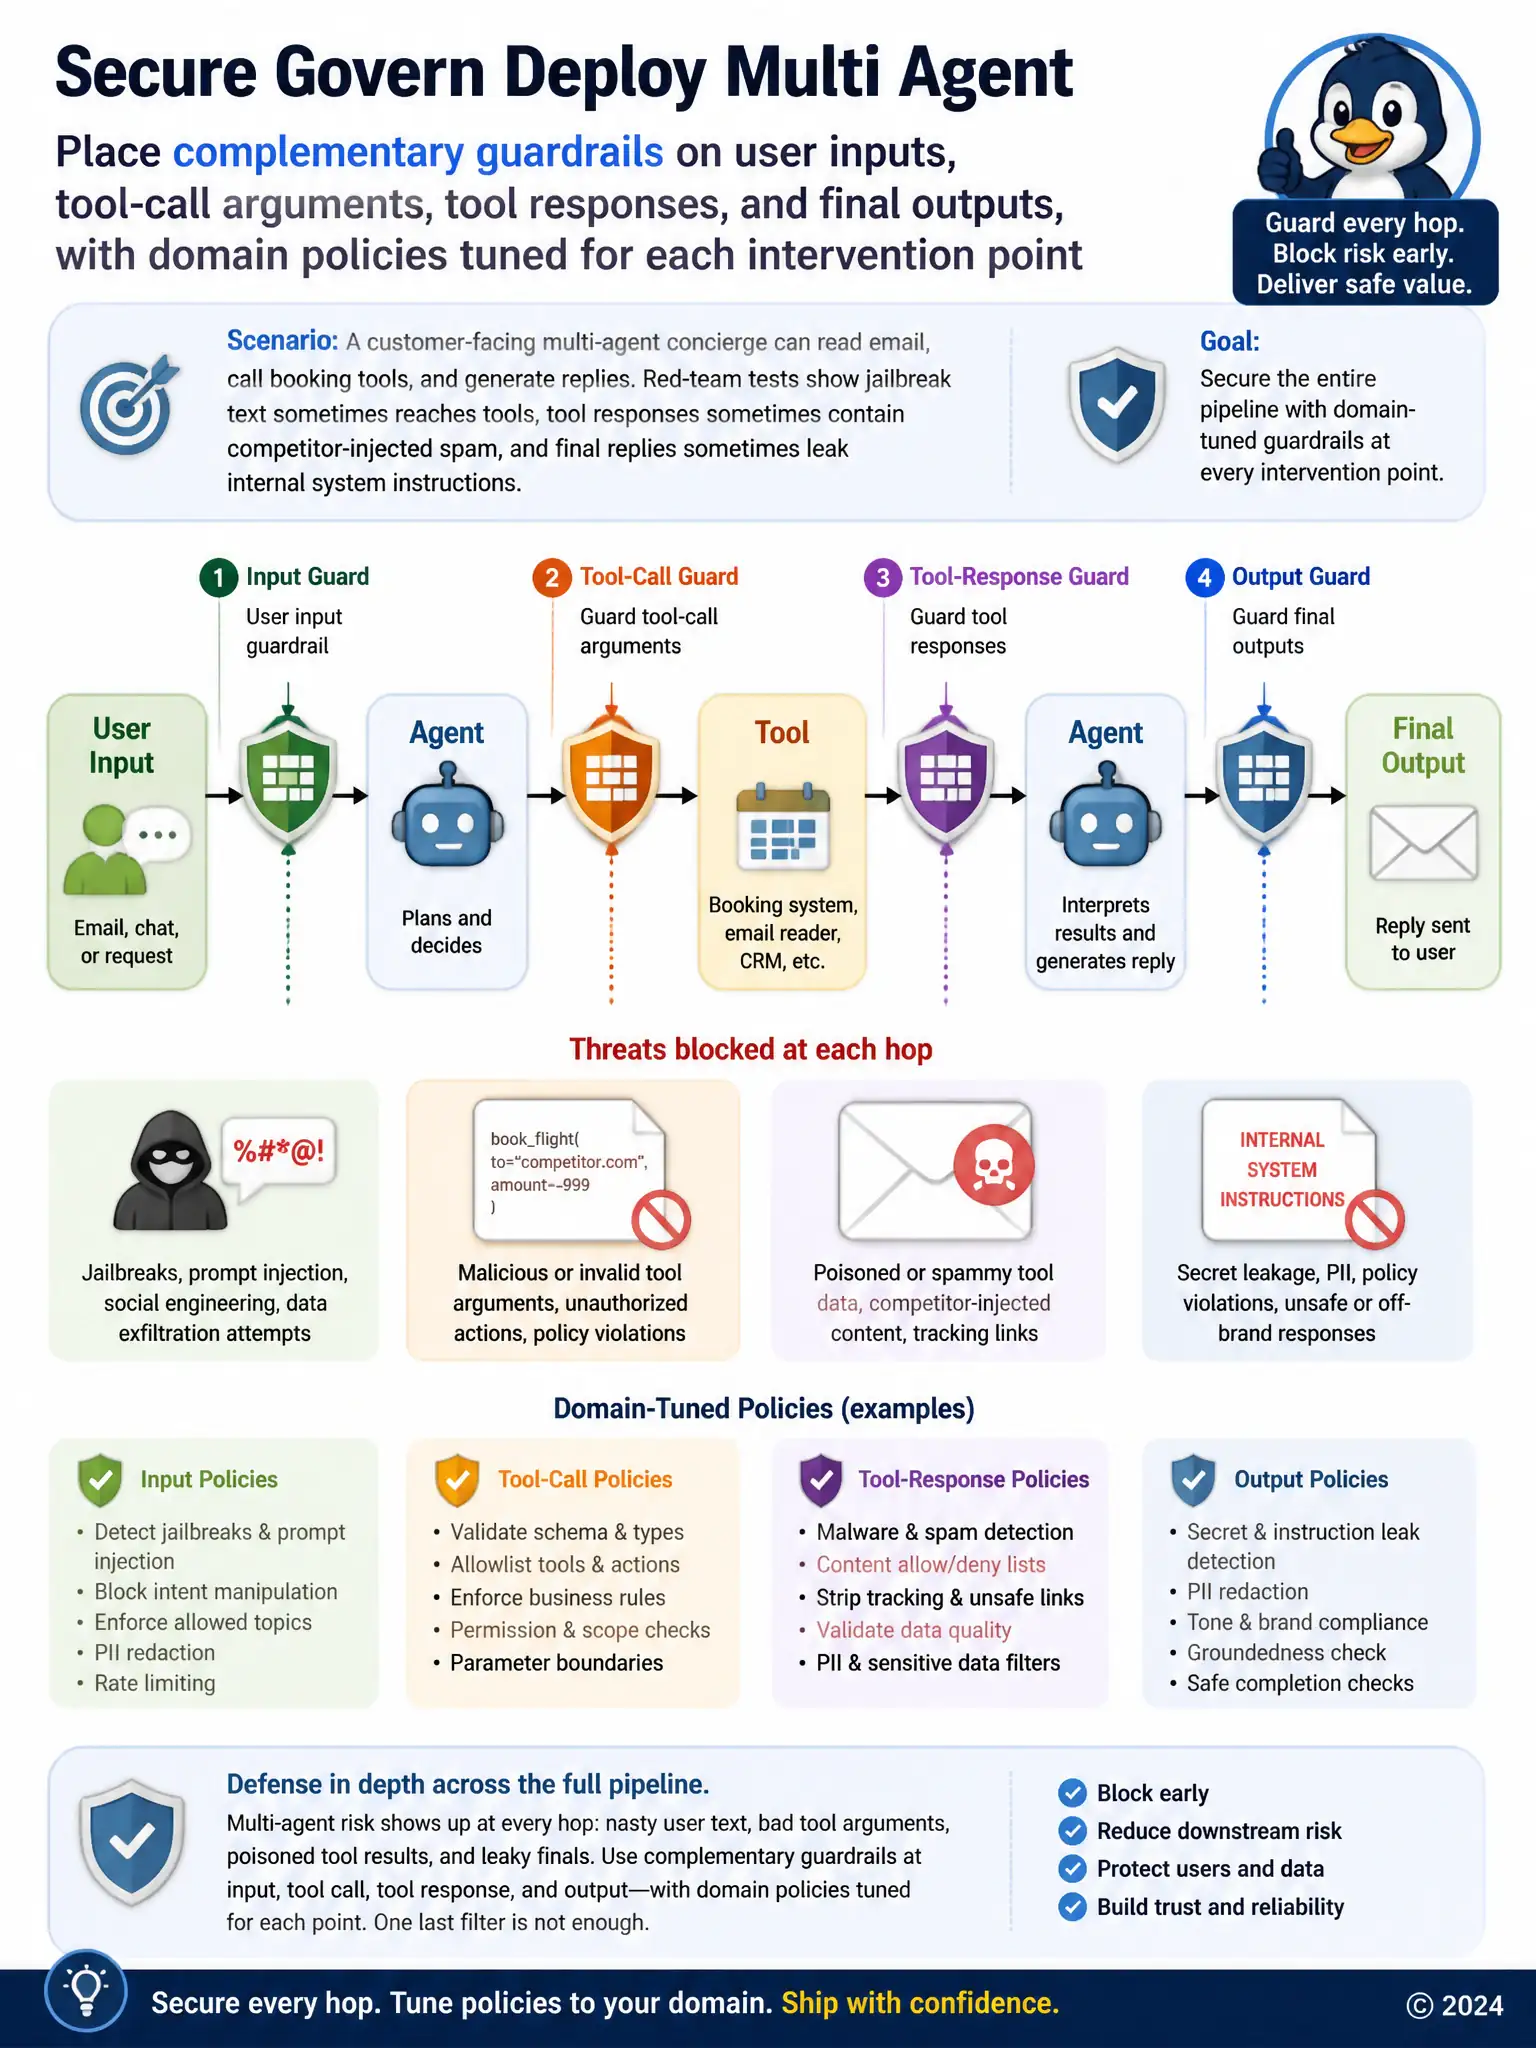
A customer-facing multi-agent concierge can read email, call booking tools, and generate replies. Red-team tests show jailbreak text sometimes reaches tools, tool responses sometimes contain competitor-injected spam, and final replies sometimes leak internal system instructions. Which guardrail strategy best matches a multi-intervention design?
Select an answer to reveal the explanation.
Short Explanation
Multi-agent risk shows up at every hop: nasty user text, bad tool arguments, poisoned tool results, and leaky finals. You need complementary guardrails at input, tool call, tool response, and output—not one last filter and a prayer. Model refusals alone aren't a control plane, and going offline just abandons the product.
Full Explanation
The correct strategy is placing complementary guardrails on user inputs, tool-call arguments, tool responses, and final outputs, with domain policies tuned for each intervention point. Secure multi-agent design calls for multi-intervention guardrails covering user inputs, tool calls, tool responses, and outputs, including custom domain constraints. Each stage has different threat patterns: prompt injection, unsafe tool arguments, untrusted tool content, and system-prompt leakage.
The option that applies a single output filter only on the final message and trusts all intermediate tool traffic is incorrect because output-only filtering misses malicious tool invocations and contaminated tool results that already executed side effects.
The option that relies only on the base model's built-in refusal behavior with no additional controls is incorrect because built-in model refusals are incomplete, inconsistent under adversarial pressure, and lack auditable policy controls.
The option that moves the entire system offline with no network tools so guardrails become unnecessary is incorrect because removing connectivity avoids some tool risks but fails product requirements and is not a guardrail strategy for a tool-using concierge.