
A support multi-agent system struggles with company-specific shorthand that few-shot prompting only partially fixes. Leadership asks about fine-tuning. What strategy should you design?
Select an answer to reveal the explanation.
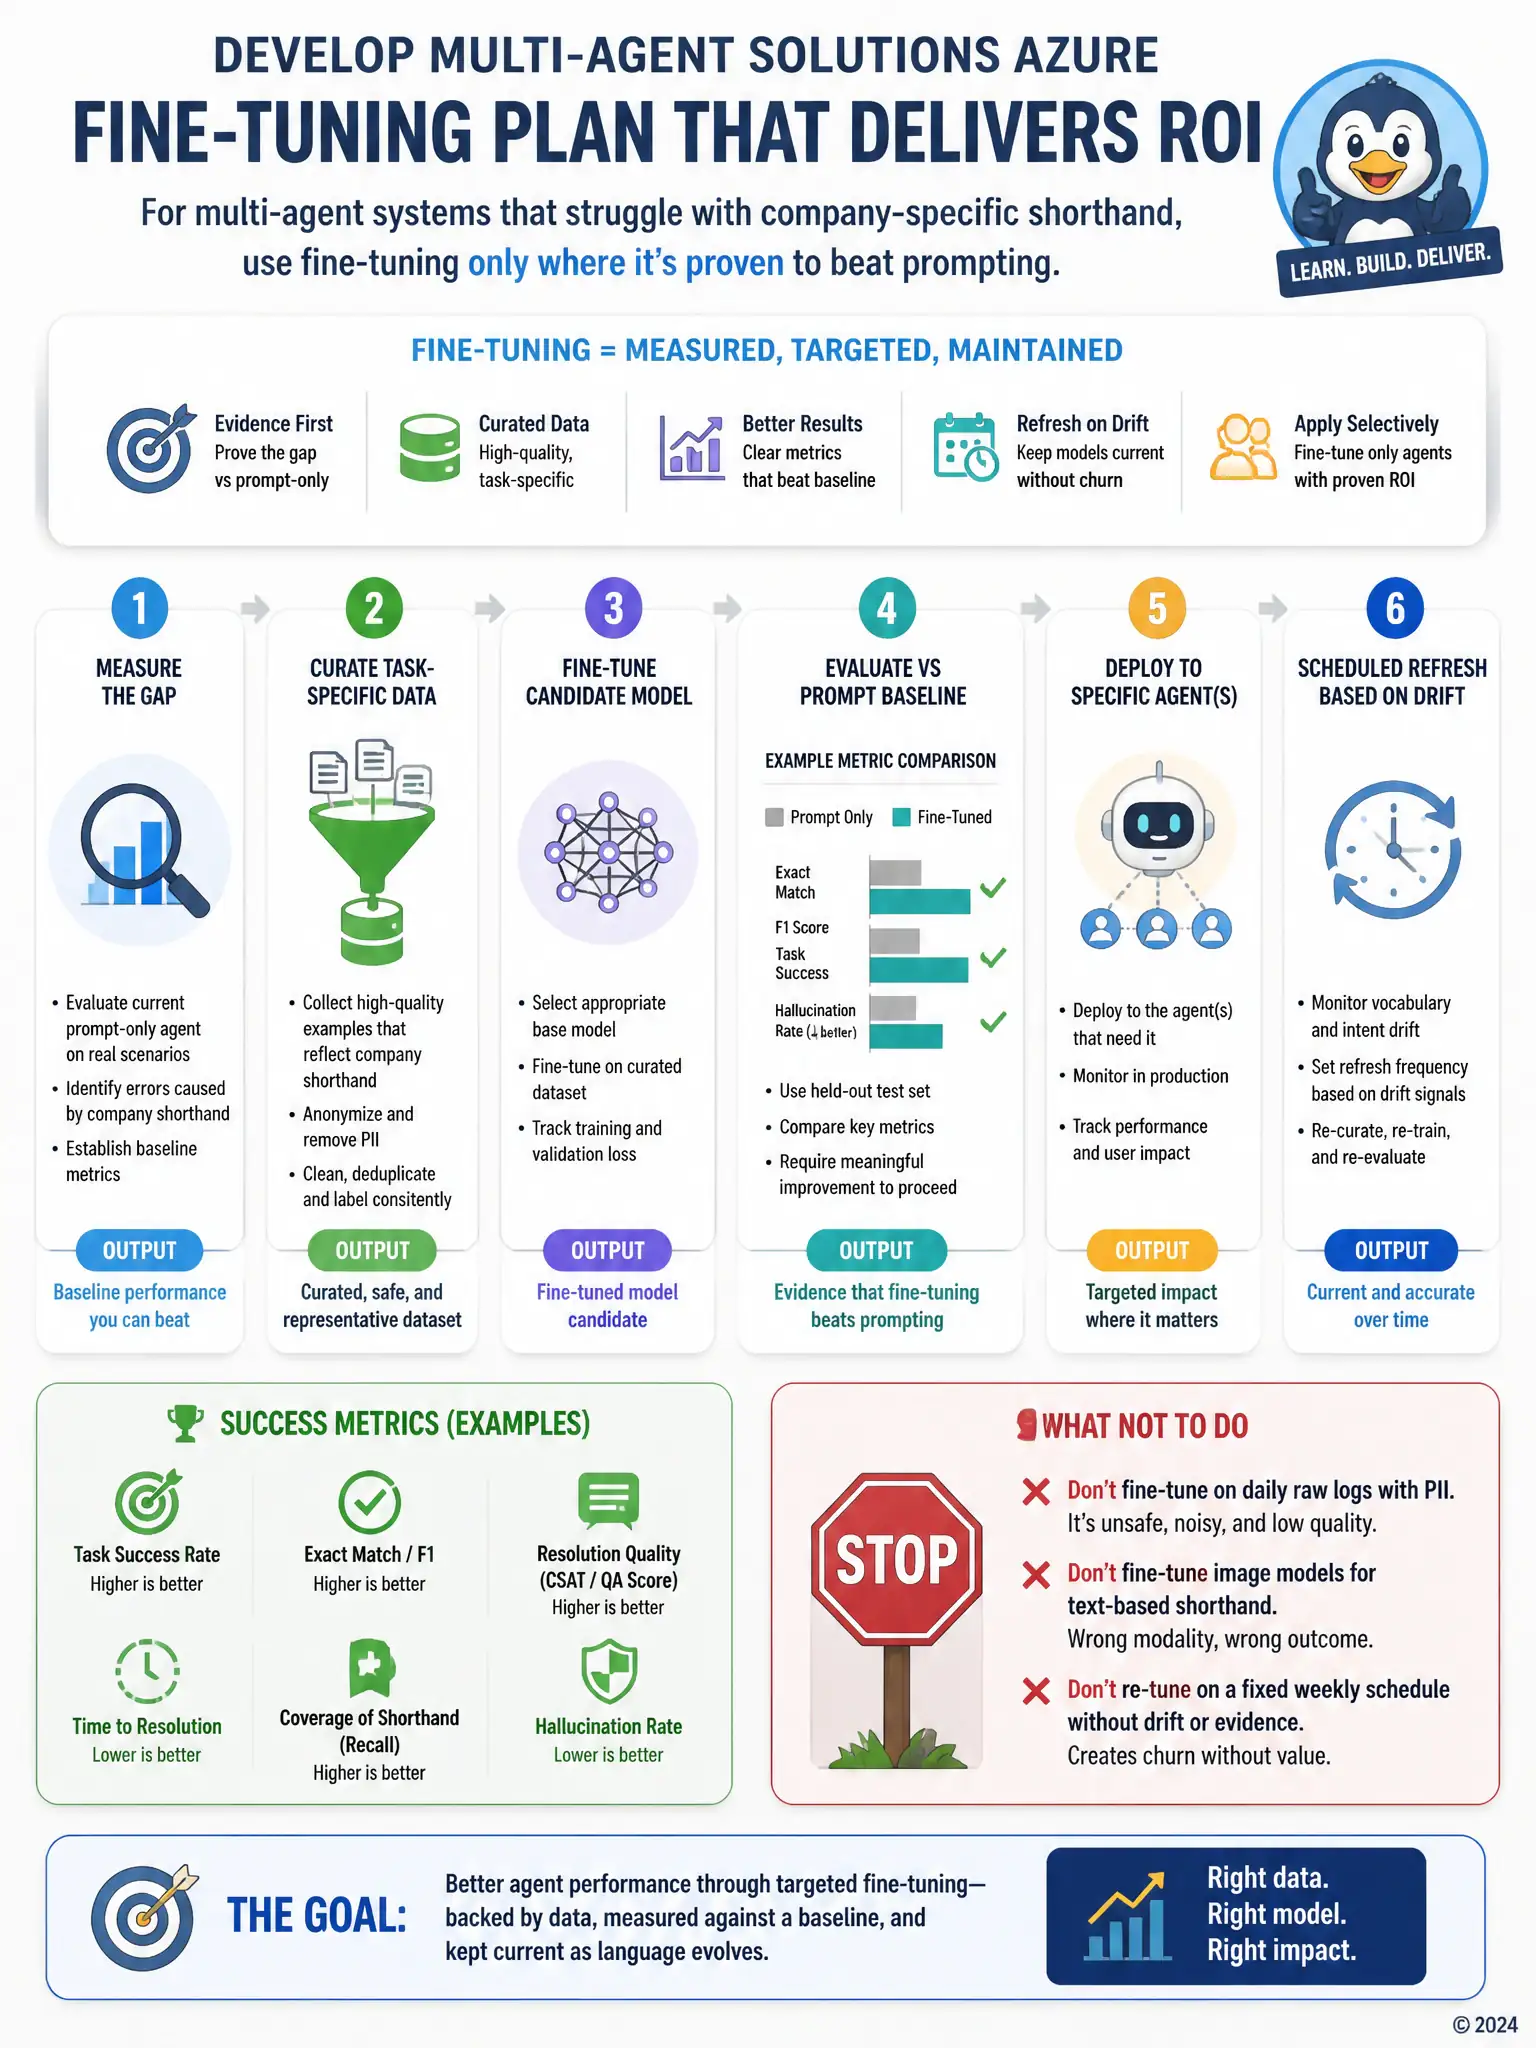
Short Explanation
You should design a controlled fine-tuning plan that uses curated task-specific datasets, evaluation baselines, clear success metrics versus prompt-only, and a refresh cadence tied to vocabulary drift, and apply it only to agents or models where the return is proven.
Full Explanation
Designing fine-tuning strategy includes data and frequency decisions. The curated task-specific datasets plan with baselines, success metrics versus prompt-only, and refresh cadence tied to vocabulary drift is controlled, evaluable, and selective, applying fine-tuning only where ROI is proven. Daily raw logs with secrets and PII without review risk privacy violations and reward hacking on noisy logs. Fine-tuning a single model on unrelated images to improve text shorthand uses the wrong data modality. Weekly re-tuning every agent regardless of metrics optimizes for change rate rather than quality. Prefer prompt/RAG improvements first; fine-tune when stable stylistic or domain-token gaps remain after retrieval and prompting. Exam caveat: Fine-tuning plans always include evaluation gates and data governance.