
A parallel research workflow spawns eight specialist agents that all hit the same model deployment and the same external search API. Median task duration has doubled; logs show frequent 429 responses. What optimization should you apply first?
Select an answer to reveal the explanation.
Short Explanation
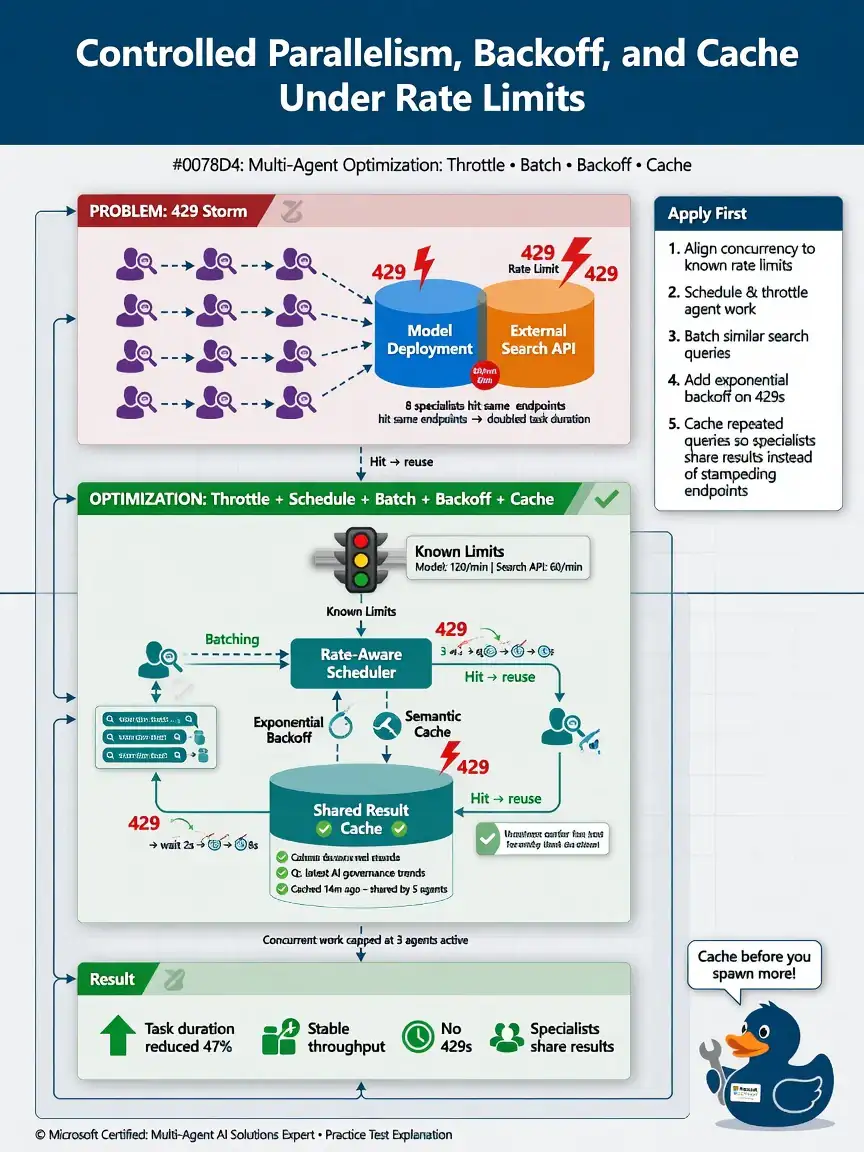
You need to treat shared model and search quotas as a controlled resource. Throttle and schedule the eight agents, batch where possible, back off on 429s, and cache repeated searches so they don't stampede the same endpoints. More chaos or no caching only makes the 429 storm worse.
Full Explanation
The correct optimization is to throttle and schedule concurrent agent work against known rate limits, use batching where possible, add backoff on 429s, and cache repeated search queries so specialists share results instead of stampeding the same endpoints. Optimizing task duration covers parallelism and rate limits. When parallel specialists share model deployments and external APIs, bound concurrency to quotas, implement backoff on 429s, batch where appropriate, and cache repeated queries so agents do not stampede identical endpoints. Removing all caching so every specialist always performs fresh identical searches is wrong because it increases duplicate load and worsens throttling. Increasing max concurrent spawns from 8 to 80 to finish faster regardless of 429s is wrong because raising concurrency under 429 conditions amplifies throttling and usually increases median duration. Forcing fully sequential execution of all eight specialists with no concurrency controls review is wrong because full sequentialization can reduce 429s but is a blunt instrument; controlled parallelism with caching is preferred when steps are independent. Exam tip: Parallelism helps only within rate limits; add backoff and a shared cache.